
Table 1:
Summary of handcrafted and hybrid gait feature extraction methods
| Ref. | Year | Feature used | Dataset used | Type of representation | Covariates | Key contribution | Finding |
|---|---|---|---|---|---|---|---|
| [16] | 2017 | MHI, BSIF, HOG | OU-ISIR D, CASIA-B, CMU MoBo | Skeleton-based motion features | Walking speed variations | Proposed a hybrid handcrafted descriptor pipeline that combining motion template (MHI), texture encoding (BSIF), and gradient information (HOG). | The fusion of motion, texture, and gradient descriptors was more effective than using any single handcrafted descriptor alone. |
| [17] | 2018 | Motion-based local descriptors + Fisher Vector encoding | TUM GAID and CASIA-A datasets | Motion-based (spatio-temporal) | - | Proposed a spatio-temporal gait recognition algorithm combining handcrafted motion features, Fisher Vector encoding, and linear SVM classification. | Showed that combining Fisher Vector encoding with motion-based descriptors improved gait recognition robustness and discriminative power. |
| [18] | 2020 | HTG | OU-ISIR D, CASIA-B, CMU MoBo | Silhouette based, Shape/texture representation | - | Proposed a new descriptor: HTG that accumulates temporal pixel gradients instead of just spatial gradients (unlike HOG). | The temporal gradient encoding improved robustness by incorporating dynamic motion cues in addition to static shape cues. |
| [19] | 2021 | SIFT, SURF, Shi-Tomasi edge corner detector | CASIA-A | Silhouette-based, shape/texture representation | General variations | Evaluation of individual and combined feature descriptors (SIFT, SURF, Shi-Tomasi) with multiple classifiers for gait recognition. | Combining descriptors improved recognition accuracy, and Random Forest gives the highest accuracy on CASIA-A. |
| [20] | 2021 | PVTM | CASIA-B | Silhouette-based, shape | View variation, carrying bag, clothing | Proposed PVTM that transforms semantically selected gait parts across views to mitigate angle variation and covariate factors. | Achieved better recognition accuracy than multi-view baselines on CASIA-B, proving robustness under bag-carrying and clothing variations. |
| [21] | 2022 | SURF, HOG, HOF, MBH | KTH, YouTube, and UCF50 datasets | Optical flow-based motion representation | - | Proposed a video representation for motion recognition called MoSURF, which integrates multiple complementary descriptors | Combined motion-based and appearance-based features for more robust recognition in video. |
| [22] | 2022 | HOG | CASIA-B | Silhouette-based (GEI representation) | Clothing, Carrying | Proposed GEI + HOG + SVM approach for gait recognition under clothing and carrying covariates | Clothing changes affected recognition less than carrying conditions. |
| [23] | 2022 | ISMAEI (derived from active energy image with mid-body masking using Improved-Sobel-Masking operator) | CAISA-B, TUM-GAID | Hybrid: Appearance + Silhouette-based (Shape 27 Motion AEI) | Clothing, carrying | Proposed a two-branch Re-ID framework that fuses deep appearance features (ResNet50) with handcrafted gait features (ISMAEI) to handle covariate changes in long-term person Re-ID. | Achieved better Rank-1 and mAP on CASIA-B and TUM-GAID. |
| [24] | 2023 | LR2P descriptor (Local Rotation Robust Pattern) | OU-ISIR B, CASIA-B | GEI based shape and motion representation | Rotation and clothing | Introduced the handcrafted LR2P descriptor for gait recognition, which is rotation- and clothing-invariant | On OUISIR B dataset achieved 86.12% accuracy across different clothing sets. On CASIA-B dataset achieved 92.02% accuracy across 32 tests. |
| [25] | 2025 | LFHEI | CASIA-A, CASIA-B | Optical flow-based motion representation | - | Combined handcrafted LFHEI with deep metric learning to build a robust embedding space. | Showed that frontal-view gait recognition was feasible. Achieved 95.0% accuracy on CASIA-A and 89.9% on CASIA-B datasets. |
| [26] | 2025 | SIFT, SURF | CAISA-A | Silhouette-based, Shape/texture representation | - | Evaluated SIFT and SURF features for non-intrusive gait recognition using Decision Tree and Random Forest classifiers. | Random Forest achieved higher accuracy (87.80%) on CASIA-A, and showed effectiveness of these feature-classifier combinations. |
| [27] | 2025 | Skeletal landmarks + LightGBM | RUET-GAIT | Skeleton-based | Outdoor uncontrolled environment | Proposed OptiGait-LGBM model for skeleton-based gait recognition with low memory usage and minimal computational cost. | Outperformed ensemble methods (Random Forest, CatBoost) in accuracy, memory usage, and training time. |
[i] BSIF, binarized statistical image features, GEI, gait energy image; HOG, histogram of oriented gradients, HTG, histogram of temporal gradients, LFHEI, local fuzzy histogram energy image, MBH, motion boundary histograms, MHI, motion history image, PVTM, part view transformation model, SIFT, scale-invariant feature transform, SURF, speeded-up robust features, SVM, support vector machine.
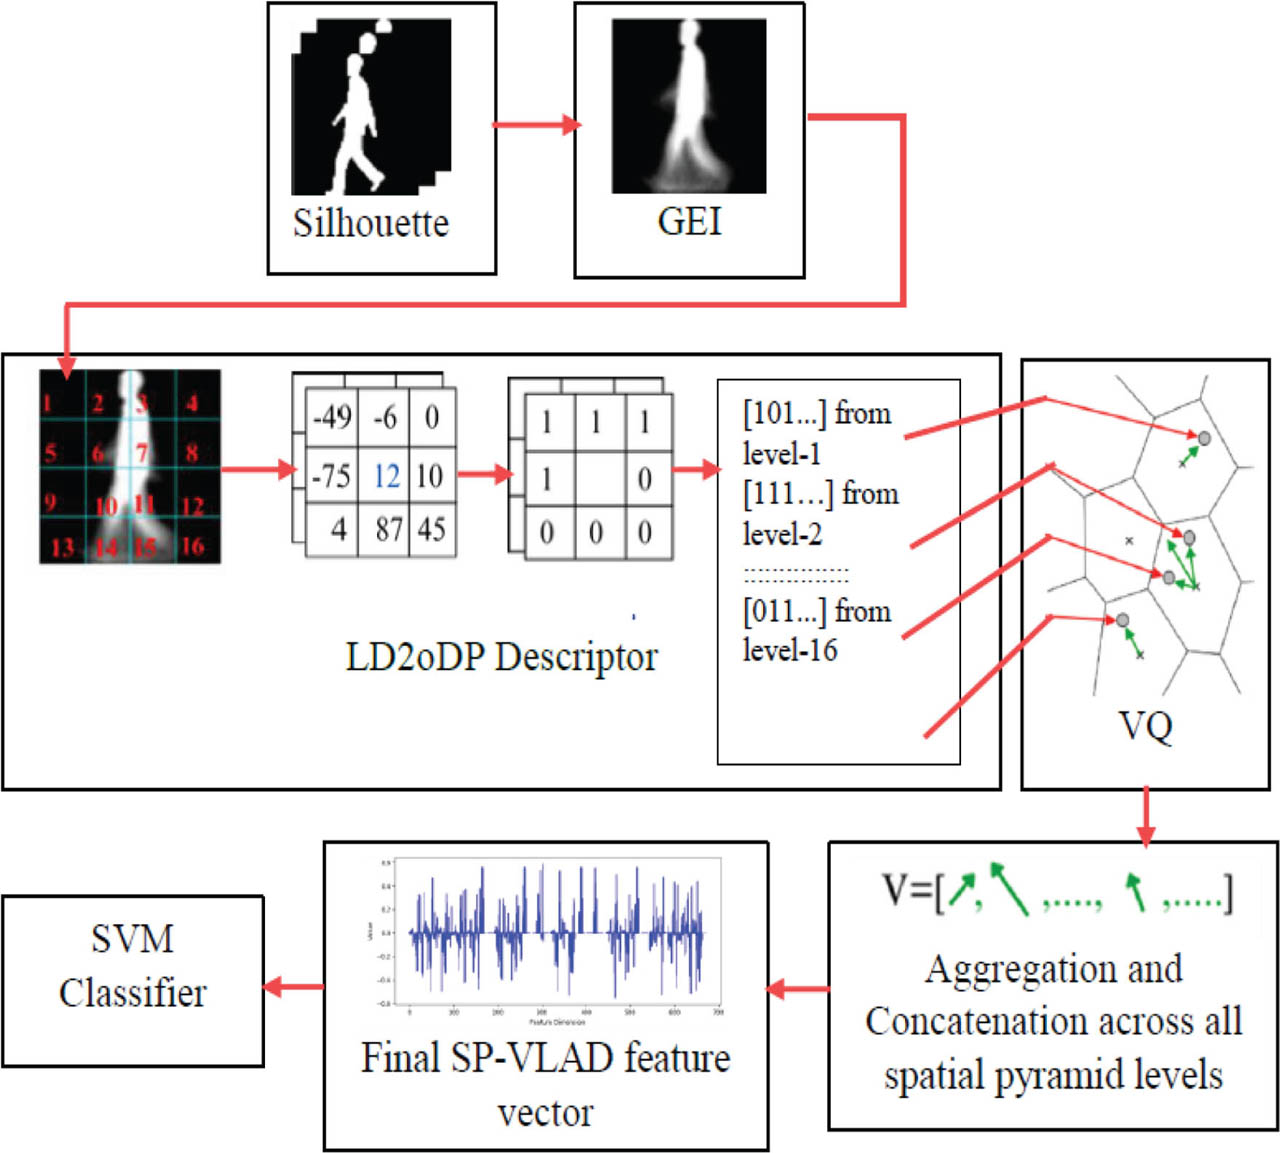
Figure 1:
Block diagram of proposed methodology. GEI, gait energy image; LD2oDP, local directional second-order derivative pattern; SP-VLAD, spatial pyramid vector of locally aggregated descriptors; SVM, support vector machine; VQ, vector quantization.
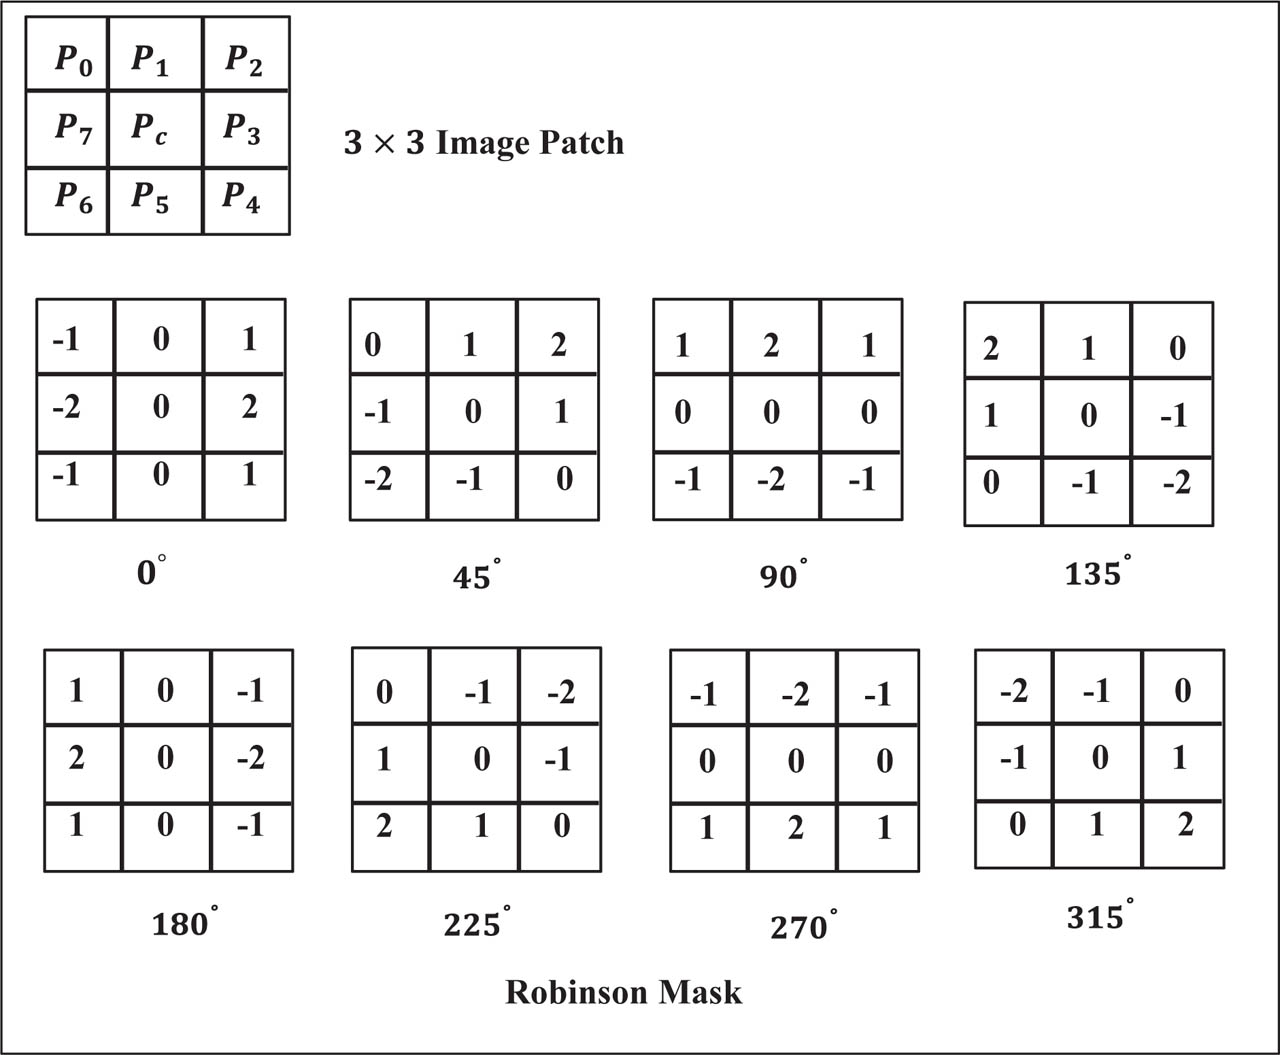
Figure 2:
Robinson mask with 3 × 3 image patch.
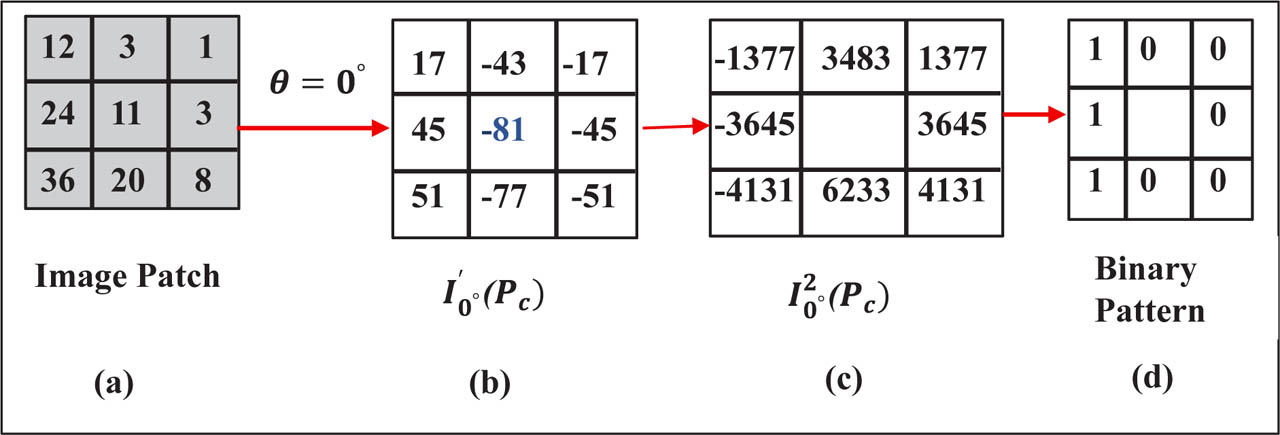
Figure 3:
Example calculation of with θ = 0. The reference pixel Pc is highlighted in blue. (A) GEI image patch. (B) First-order directional derivative response at direction. (C) Second-order directional derivative response at direction. (D) Generated binary pattern at direction.
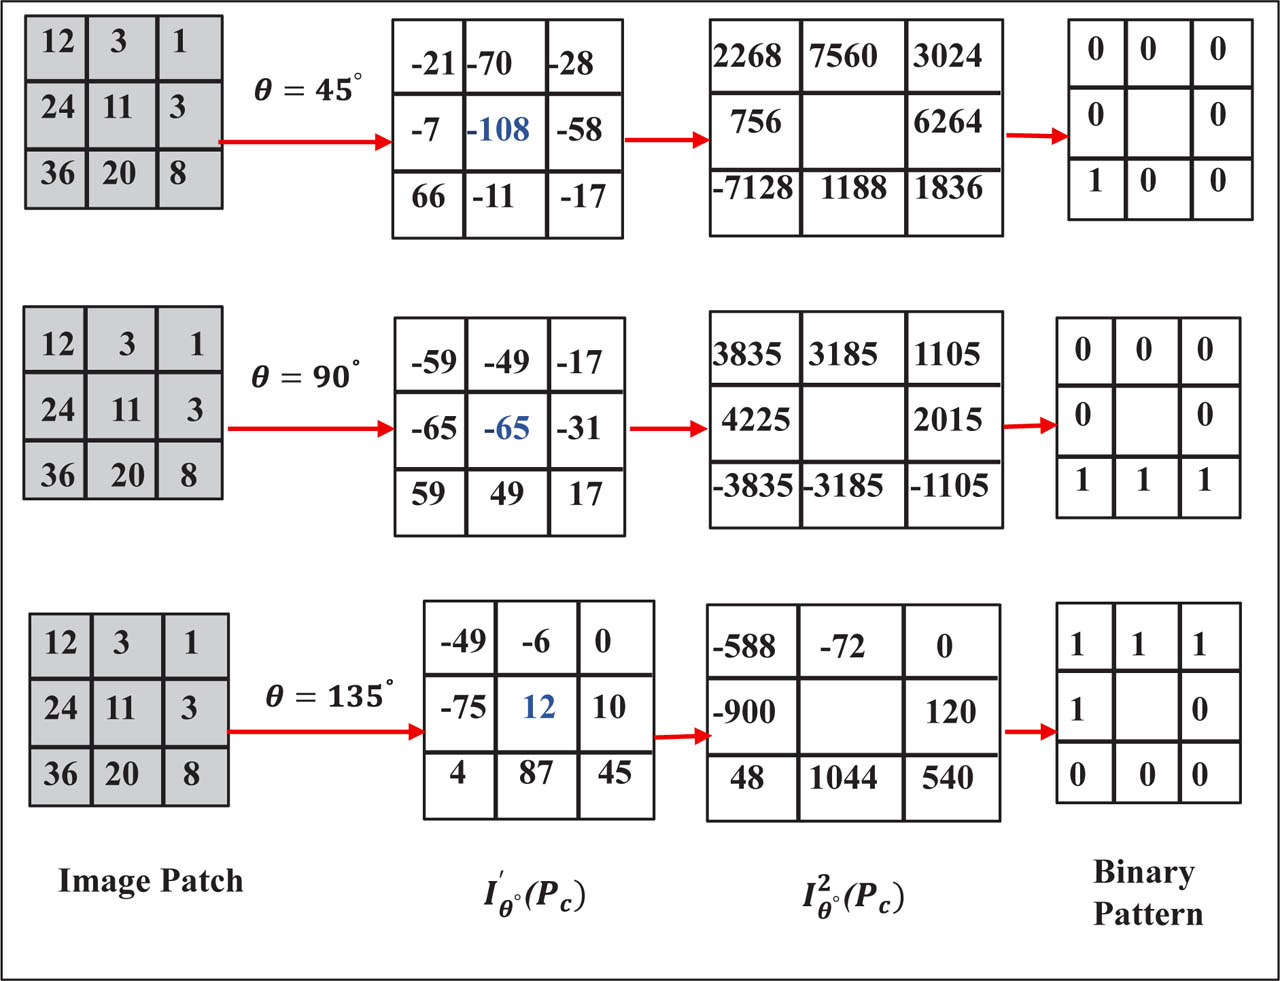
Figure 4:
Example calculation of with θ = 45°, 90°, 135°.
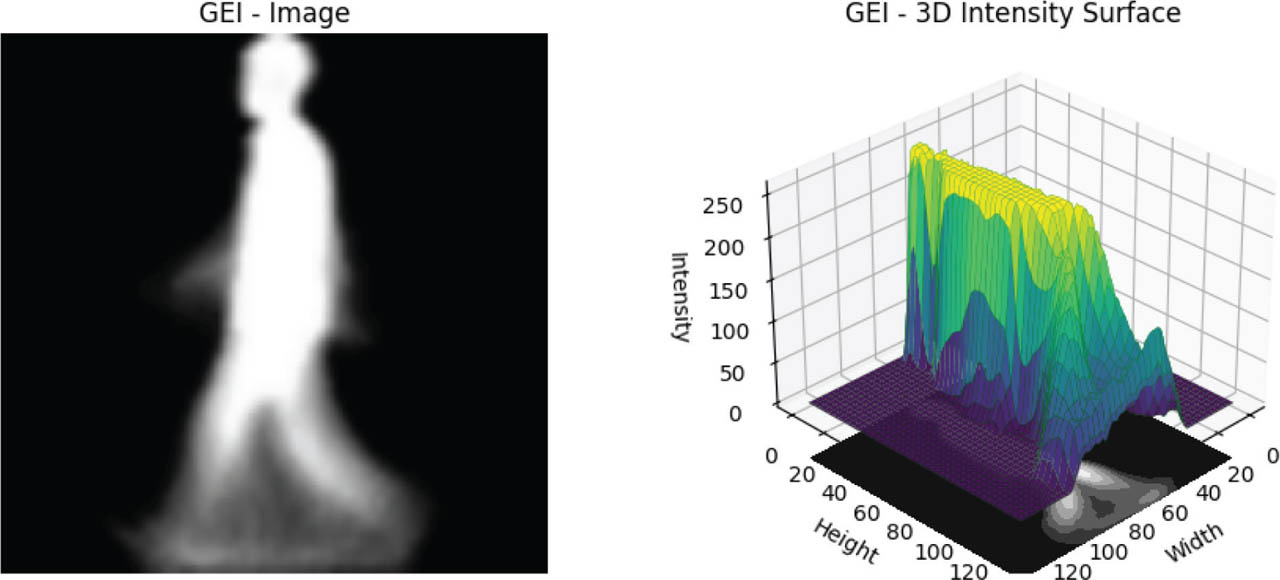
Figure 5:
GEI representation of a sample subject and corresponding intensity plot. GEI, gait energy image.
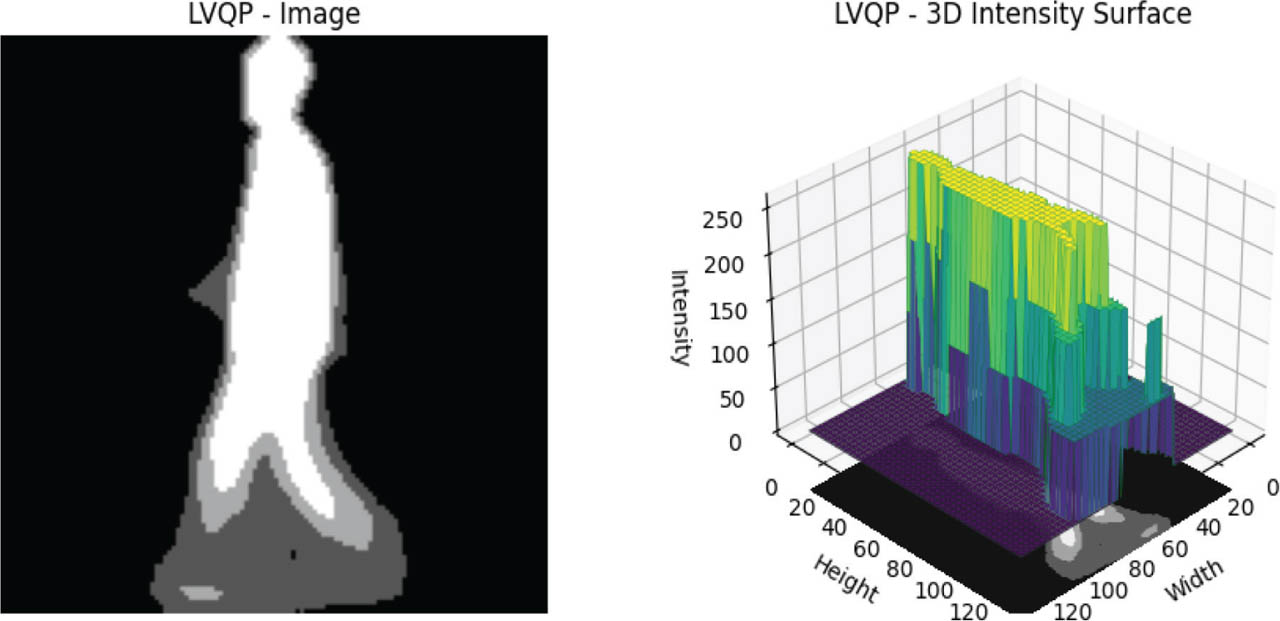
Figure 6:
LVQP descriptor and corresponding intensity plot. LVQP, local vector quantization pattern.
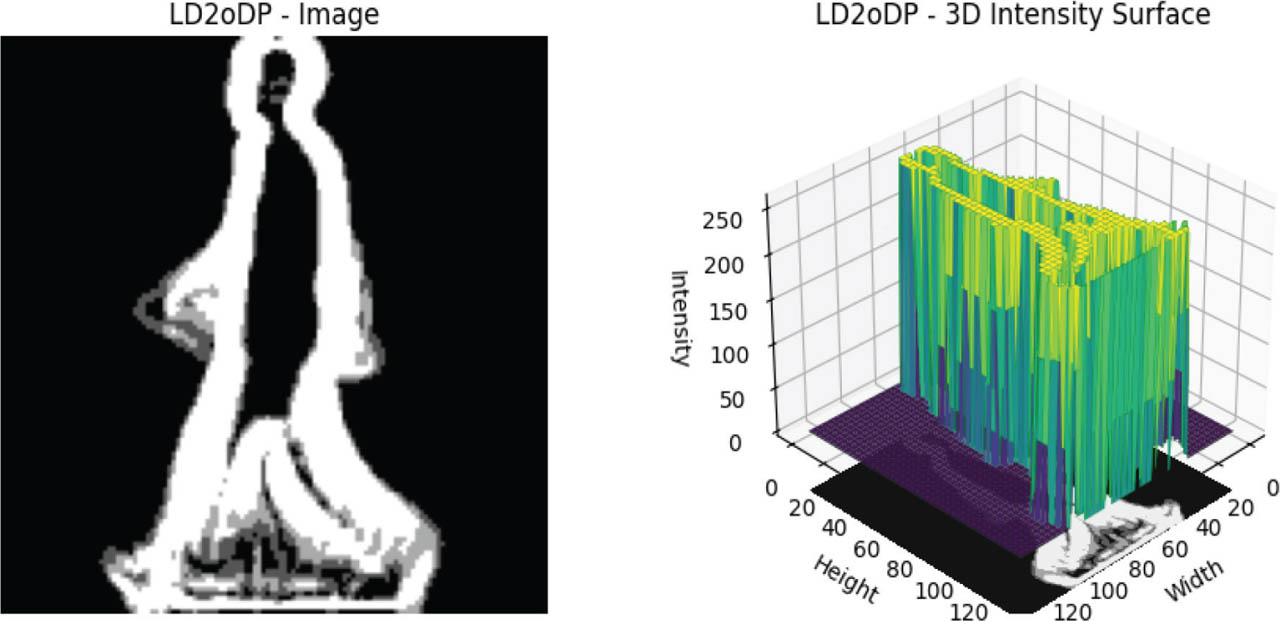
Figure 7:
LD2oDP descriptor with simple VQ and corresponding intensity plot. LD2oDP, local directional second-order derivative pattern; VQ, vector quantization.
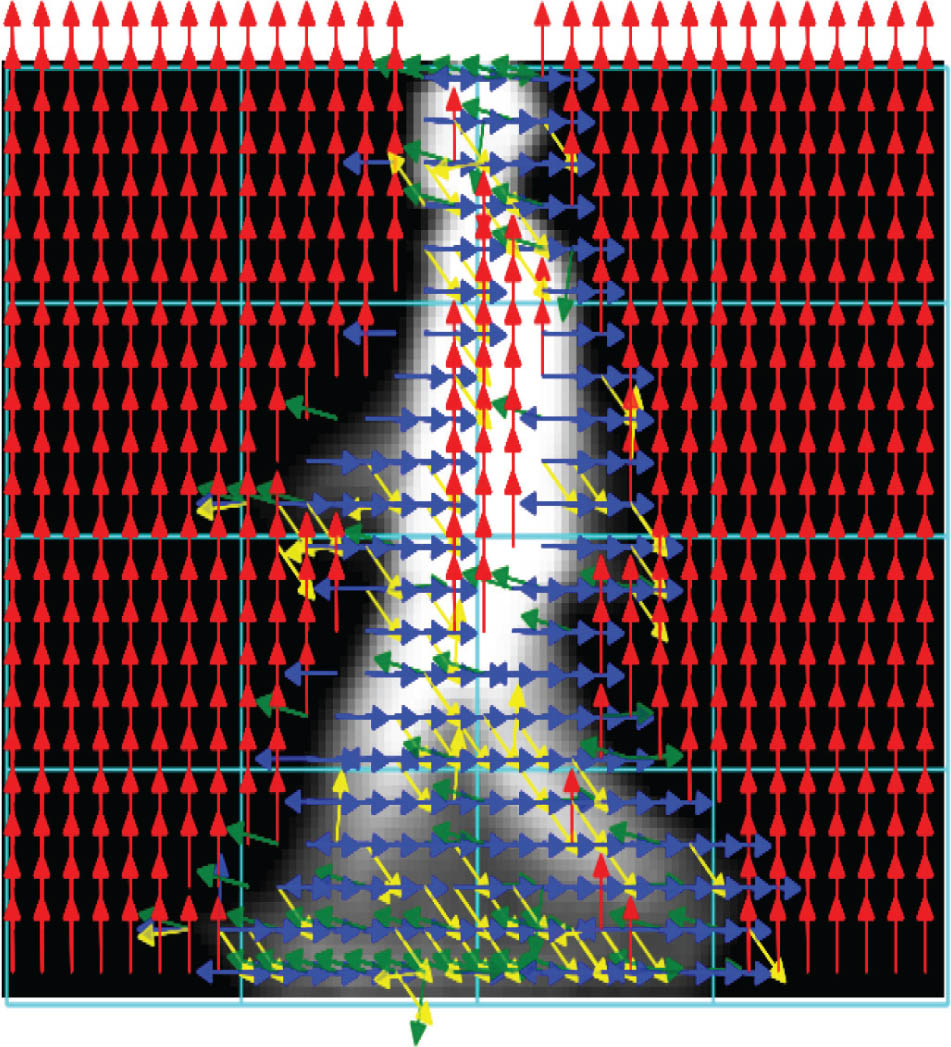
Figure 8:
Visualization of the SP level 2 with LD2oDP descriptor. LD2oDP, local directional second-order derivative pattern; SP, spatial pyramid.
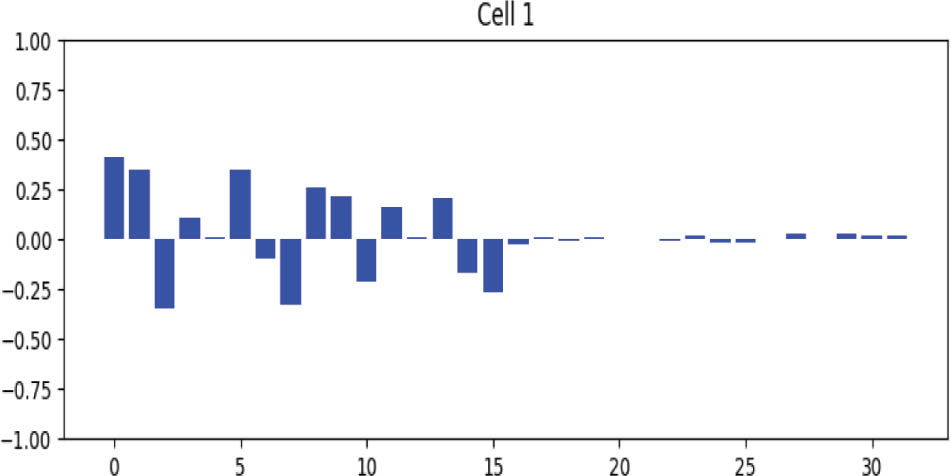
Figure 9:
VLAD residual histograms across SP level-0. SP, spatial pyramid; VLAD, vector of locally aggregated descriptors.
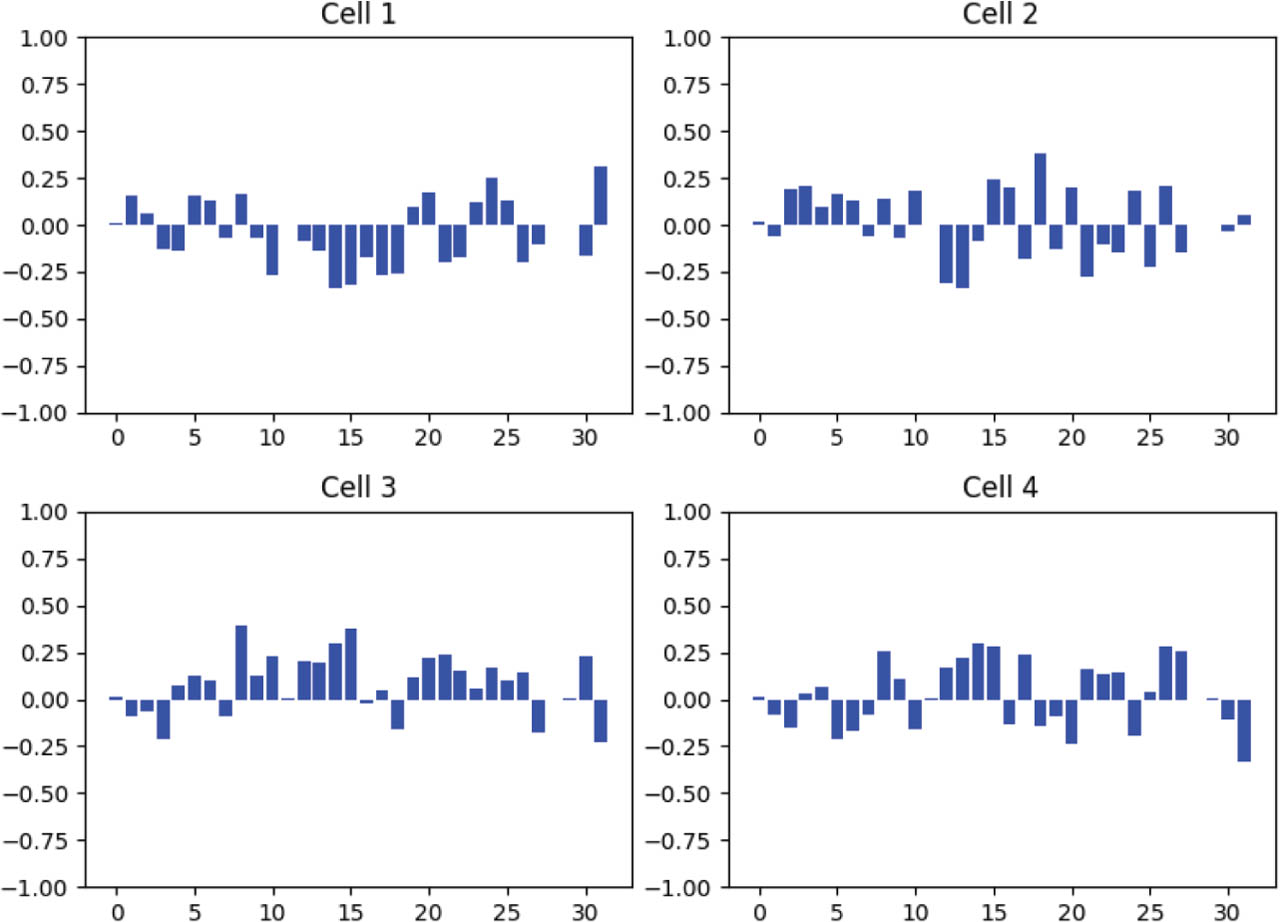
Figure 10:
VLAD residual histograms across SP level-1. SP, spatial pyramid; VLAD, vector of locally aggregated descriptors.
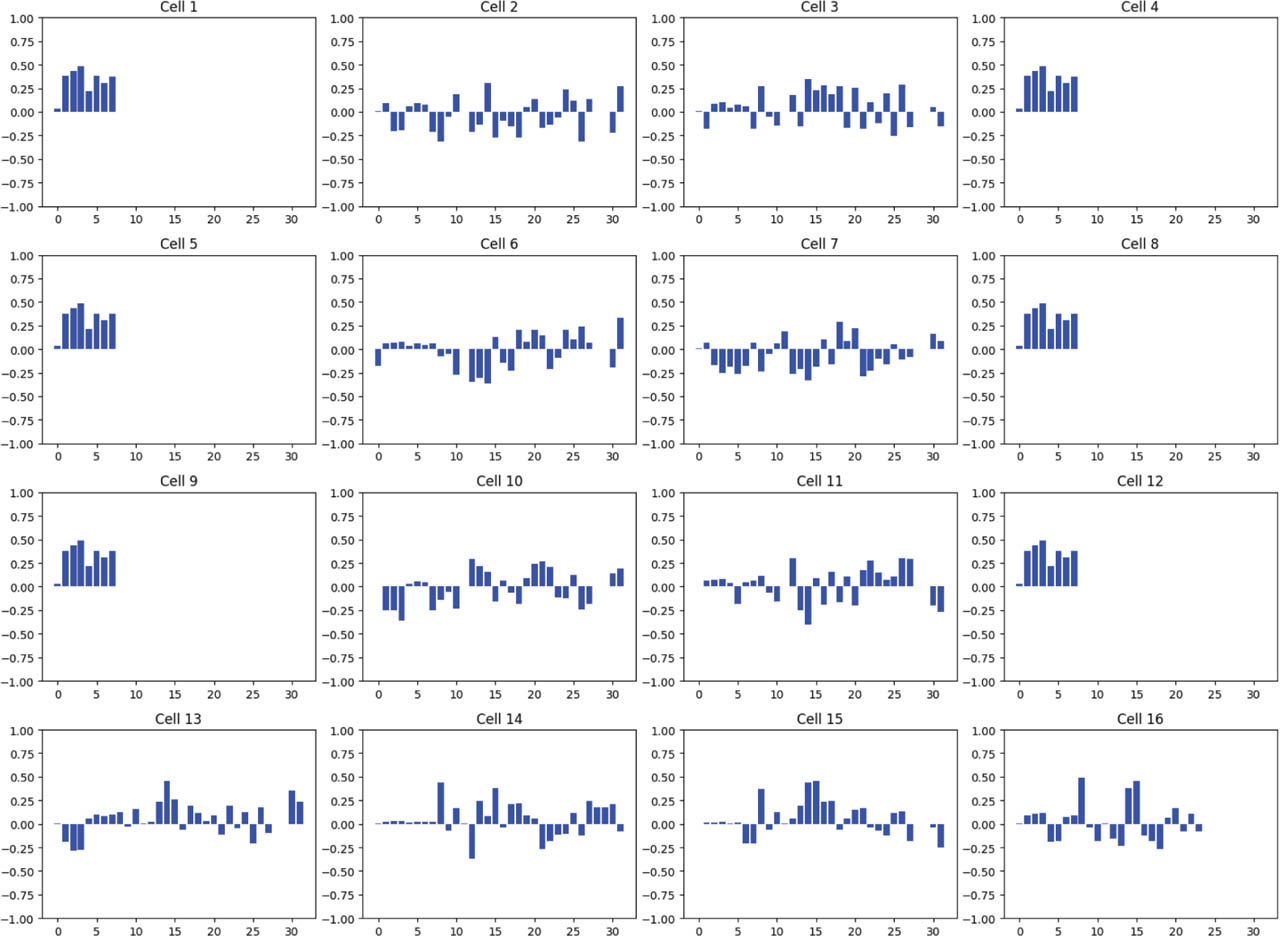
Figure 11:
VLAD residual histograms across SP level-2. SP, spatial pyramid; VLAD, vector of locally aggregated descriptors.
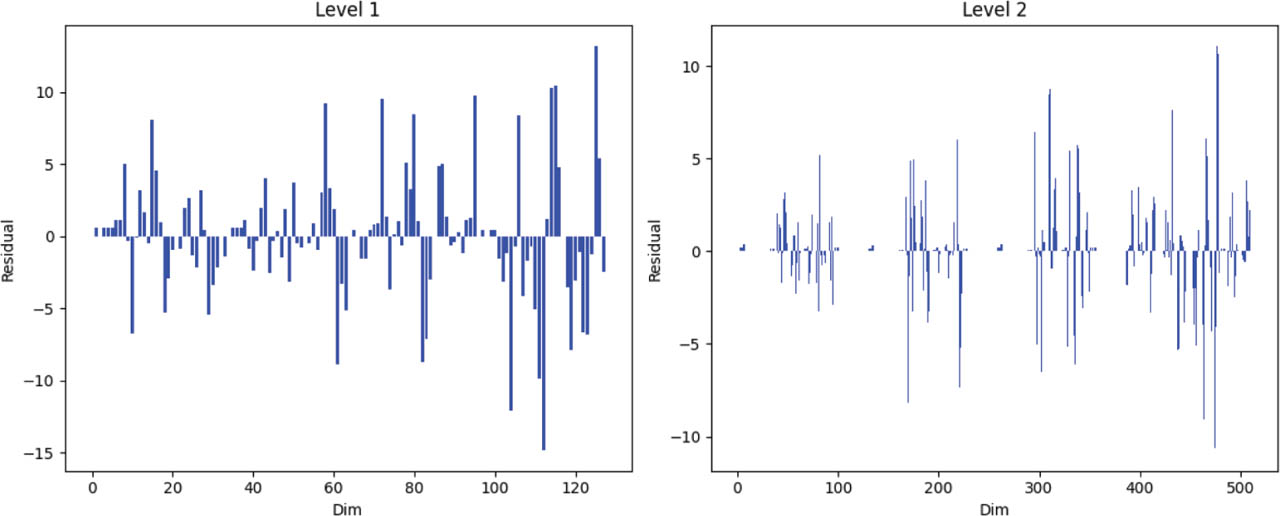
Figure 12:
Combined VLAD residual histograms across SP level-1 and level-2. SP, spatial pyramid; VLAD, vector of locally aggregated descriptors.
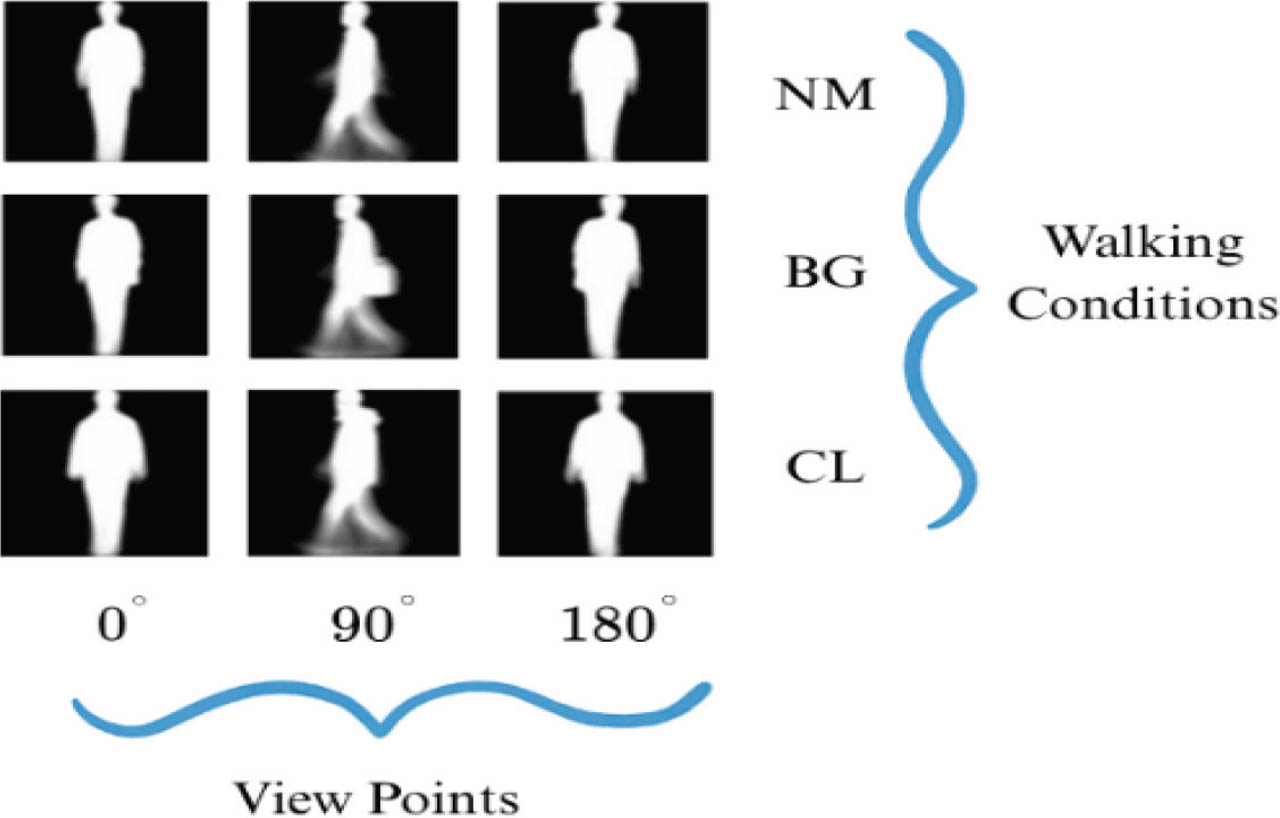
Figure 13:
Sample GEI image examples from the CASIA-C dataset. GEI, gait energy image.
Table 2:
View-wise performance of the proposed LD2oDP + SP-VLAD method on the CASIA-B dataset in terms of accuracy, precision, recall and F1 score under NW condition
| View | Accuracy (%) | Precision (%) | Recall (%) | F1-score (%) |
|---|---|---|---|---|
| 0° | 98.20 | 98.10 | 97.97 | 97.72 |
| 18° | 95.54 | 95.03 | 95.97 | 94.89 |
| 36° | 87.05 | 86.22 | 87.10 | 84.73 |
| 54° | 87.44 | 85.95 | 87.10 | 84.52 |
| 72° | 92.57 | 93.41 | 93.15 | 91.69 |
| 90° | 93.07 | 93.65 | 93.94 | 92.60 |
| 108° | 94.20 | 94.35 | 94.76 | 93.36 |
| 126° | 94.14 | 94.17 | 94.72 | 93.50 |
| 144° | 88.74 | 89.05 | 89.11 | 86.96 |
| 162° | 95.05 | 94.62 | 95.16 | 93.82 |
| 180° | 98.20 | 96.91 | 97.98 | 97.15 |
Table 3A:
Comparison of recognition accuracy (%) at lower viewing angles on the CASIA-B dataset
| Method (Ref) | Year | Category | 0° | 18° | 36° | 54° | 72° |
|---|---|---|---|---|---|---|---|
| Genetic template segmentation [30] | 2017 | Handcrafted | 97.00 | 99.49 | 97.50 | 94.00 | 88.00 |
| Specialized CNN [31] | 2017 | Deep learning | 79.10 | 82.52 | 76.00 | 81.63 | 85.20 |
| Deterministic learning [32] | 2018 | Handcrafted | 97.81 | 98.80 | 98.05 | 95.00 | 92.56 |
| Deep learning framework [33] | 2024 | Deep learning | 96.20 | 98.70 | 97.70 | 97.10 | 85.30 |
| Frontal-view gait dynamics + deep transfer learning [25] | 2025 | Hybrid (handcrafted + deep learning) | 96.9 | - | - | - | - |
| Part-based Ensemble CNN [34] | 2025 | Deep learning | 88.30 | 94.60 | 97.30 | 94.90 | 90.80 |
| GaitSet-based [35] | 2025 | Deep learning | 89.8 | 96.40 | 97.70 | 96.30 | 91.40 |
| Deep learning fusion + MFO (EfficientNetB0 + MobileNetV2) [36] | 2025 | Deep learning | 95.70 | 91.90 | - | - | - |
| Proposed method (LD2oDP + SP-VLAD) | Handcrafted | 98.20 | 95.97 | 87.05 | 87.44 | 92.57 |
Table 3B:
Comparison of recognition accuracy (%) at higher viewing angles on the CASIA-B dataset
| Method (Ref) | Year | Category | 90° | 108° | 126° | 144° | 162° | 180° |
|---|---|---|---|---|---|---|---|---|
| Genetic template segmentation [30] | 2017 | Handcrafted | 90.50 | 89.50 | 94.50 | 92.00 | 91.28 | 93.94 |
| Specialized CNN [31] | 2017 | Deep learning | 84.46 | 82.77 | 79.26 | 84.70 | 86.40 | 82.00 |
| Deterministic learning [32] | 2018 | Handcrafted | 92.80 | 91.52 | 93.10 | 92.73 | 91.60 | 94.52 |
| Deep learning framework [33] | 2024 | Deep learning | 88.90 | 93.20 | 88.90 | 93.20 | 88.20 | 90.90 |
| Frontal-view gait dynamics + deep transfer learning [25] | 2025 | Hybrid (handcrafted + deep learning) | - | - | - | - | - | - |
| Part-based Ensemble CNN [34] | 2025 | Deep learning | 88.50 | 90.70 | 93.40 | 96.10 | 94.60 | 85.70 |
| GaitSet-based [35] | 2025 | Deep learning | 88.40 | 92.80 | 96.00 | 97.70 | 96.10 | 82.70 |
| Deep learning Fusion + MFO (EfficientNetB0 + MobileNetV2) [36] | 2025 | Deep learning | 82.70 | 85.30 | - | - | 91.70 | 98.90 |
| Proposed method (LD2oDP + SP-VLAD) | Handcrafted | 93.07 | 94.20 | 94.14 | 88.74 | 95.05 | 98.20 |
Table 4:
Experiments conducted on the CASIA-B gait database to evaluate robustness against variations in viewpoint and clothing
| View point | Training dataset | Test dataset | Size of training dataset | Size of test dataset | Proposed method (accuracy in %) |
|---|---|---|---|---|---|
| 0° (NM) | NM + CL | NM | 124 × 5 | 124 × 2 | 99.59 |
| 0° (CL) | NM + CL | CL | 124 × 5 | 124 × 1 | 96.75 |
| 18°(NM) | NM + CL | NM | 124 × 5 | 124 × 2 | 97.98 |
| 18°(CL) | NM + CL | CL | 124 × 5 | 124 × 1 | 90.32 |
| 36°(NM) | NM + CL | NM | 124 × 5 | 124 × 2 | 93.95 |
| 36°(CL) | NM + CL | CL | 124 × 5 | 124 × 1 | 87.10 |
| 54°(NM) | NM + CL | NM | 124 × 5 | 124 × 2 | 92.74 |
| 54°(CL) | NM + CL | CL | 124 × 5 | 124 × 1 | 82.11 |
| 72°(NM) | NM + CL | NM | 124 × 5 | 124 × 2 | 97.18 |
| 72°(CL) | NM + CL | CL | 124 × 5 | 124 × 1 | 95.97 |
| 90°(NM) | NM + CL | NM | 124 × 5 | 124 × 2 | 96.77 |
| 90°(CL) | NM + CL | CL | 124 × 5 | 124 × 1 | 95.97 |
| 108°(NM) | NM + CL | NM | 124 × 5 | 124 × 2 | 95.97 |
| 108°(CL) | NM + CL | CL | 124 × 5 | 124 × 1 | 91.94 |
| 126°(NM) | NM + CL | NM | 124 × 5 | 124 × 2 | 95.97 |
| 126°(CL) | NM + CL | CL | 124 × 5 | 124 × 1 | 92.68 |
| 144°(NM) | NM + CL | NM | 124 × 5 | 124 × 2 | 95.16 |
| 144°(CL) | NM + CL | CL | 124 × 5 | 124 × 1 | 95.92 |
| 162°(NM) | NM + CL | NM | 124 × 5 | 124 × 2 | 97.18 |
| 162°(CL) | NM + CL | CL | 124 × 5 | 124 × 1 | 83.99 |
| 180°(NM) | NM + CL | NM | 124 × 5 | 124 × 2 | 99.19 |
| 180°(CL) | NM + CL | CL | 124 × 5 | 124 × 1 | 96.77 |
| Avg (NM) | 96.51 | ||||
| Avg (CL) | 91.77 |
Table 5:
Experimental conducted on the CASIA-B gait dataset to evaluate robustness against viewpoint and carrying variations (e.g., walking with a bag)
| View point | Training dataset | Test dataset | Size of training dataset | Size of test dataset | Proposed method (accuracy in %) |
|---|---|---|---|---|---|
| 0° (NM) | NM + BG | NM | 124 × 5 | 124 × 2 | 99.19 |
| 0° (BG) | NM + BG | BG | 124 × 5 | 124 × 1 | 95.12 |
| 18°(NM) | NM + BG | NM | 124 × 5 | 124 × 2 | 97.98 |
| 18°(BG) | NM + BG | BG | 124 × 5 | 124 × 1 | 89.52 |
| 36°(NM) | NM + BG | NM | 124 × 5 | 124 × 2 | 94.76 |
| 36°(BG) | NM + BG | BG | 124 × 5 | 124 × 1 | 87.10 |
| 54°(NM) | NM + BG | NM | 124 × 5 | 124 × 2 | 93.95 |
| 54°(BG) | NM + BG | BG | 124 × 5 | 124 × 1 | 86.89 |
| 72°(NM) | NM + BG | NM | 124 × 5 | 124 × 2 | 95.97 |
| 72°(BG) | NM + BG | BG | 124 × 5 | 124 × 1 | 95.16 |
| 90°(NM) | NM + BG | NM | 124 × 5 | 124 × 2 | 97.18 |
| 90°(BG) | NM + BG | BG | 124 × 5 | 124 × 1 | 94.35 |
| 108°(NM) | NM + BG | NM | 124 × 5 | 124 × 2 | 95.56 |
| 108°(BG) | NM + BG | BG | 124 × 5 | 124 × 1 | 95.16 |
| 126°(NM) | NM + BG | NM | 124 × 5 | 124 × 2 | 95.56 |
| 126°(BG) | NM + BG | BG | 124 × 5 | 124 × 1 | 93.50 |
| 144°(NM) | NM + BG | NM | 124 × 5 | 124 × 2 | 95.16 |
| 144°(BG) | NM + BG | BG | 124 × 5 | 124 × 1 | 93.55 |
| 162°(NM) | NM + BG | NM | 124 × 5 | 124 × 2 | 97.58 |
| 162°(BG) | NM + BG | BG | 124 × 5 | 124 × 1 | 94.26 |
| 180°(NM) | NM + BG | NM | 124 × 5 | 124 × 2 | 98.79 |
| 180°(BG) | NM + BG | BG | 124 × 5 | 124 × 1 | 97.77 |
| Avg (NM) | 96.51 | ||||
| Avg (BG) | 92.94 |
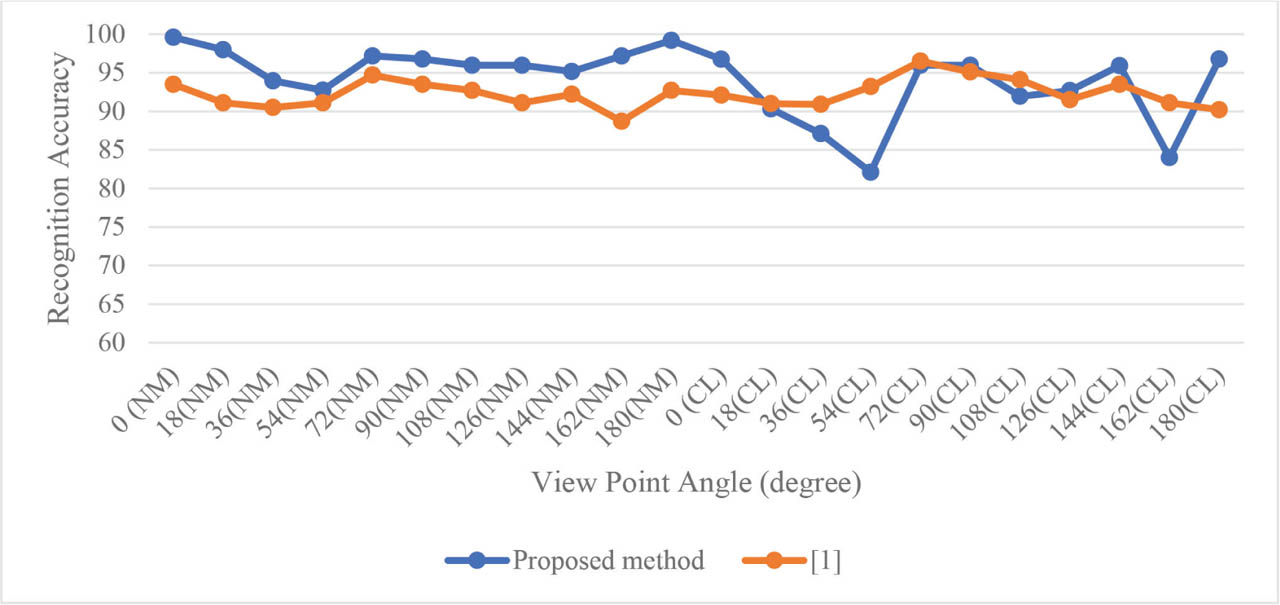
Figure 14:
Comparison of the proposed method with [1] on the CASIA-B gait database under viewpoint and clothing variations.
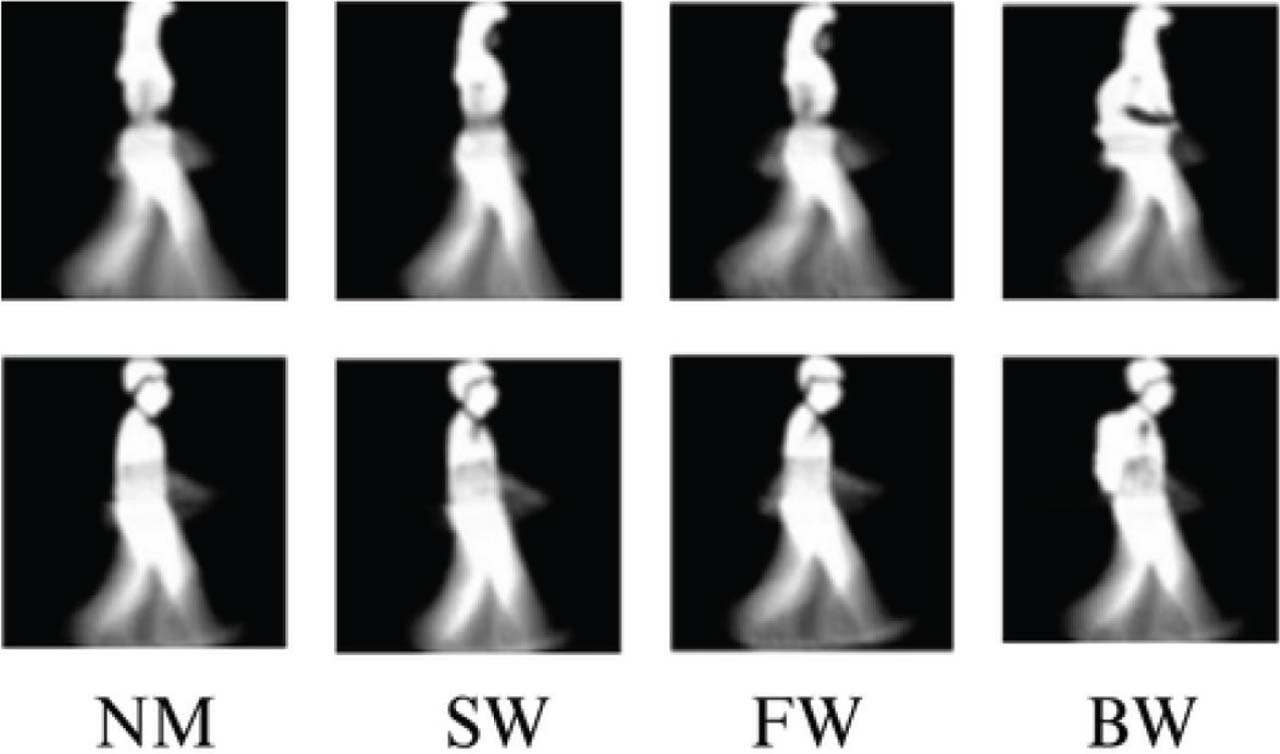
Figure 15:
Sample GEI image examples from the CASIA-C dataset. FW, fast walking; GEI, gait energy image; SW, slow walking.
Table 6:
Cross-condition performance of the proposed method on the CASIA-C dataset under different walking conditions
| Condition | Accuracy (%) | Precision (%) | Recall (%) | F1-score (%) |
|---|---|---|---|---|
| FW | 81.32 | 80.08 | 81.32 | 78.50 |
| SW | 76.37 | 76.01 | 76.37 | 73.31 |
| BW | 36.26 | 35.11 | 36.26 | 32.17 |
Table 7:
Comparison of cross-condition gait recognition accuracy (%) on the CASIA-C dataset
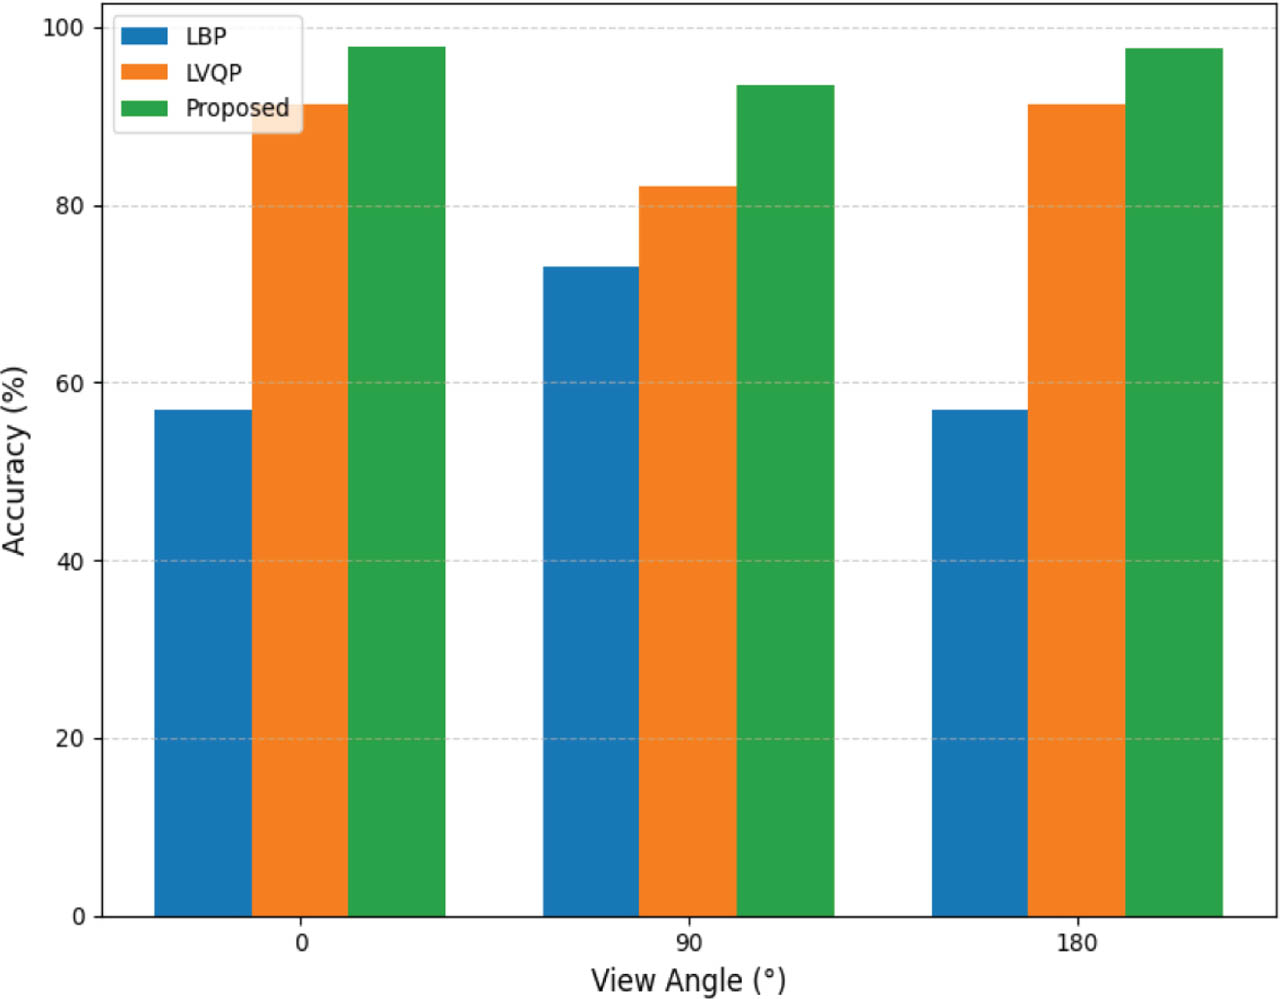
Figure 16:
Performance analysis of different feature descriptors on the CASIA-B dataset at 0°, 90°, and 180° view angles. LBP, local binary pattern; LVQP, local vector quantization pattern.
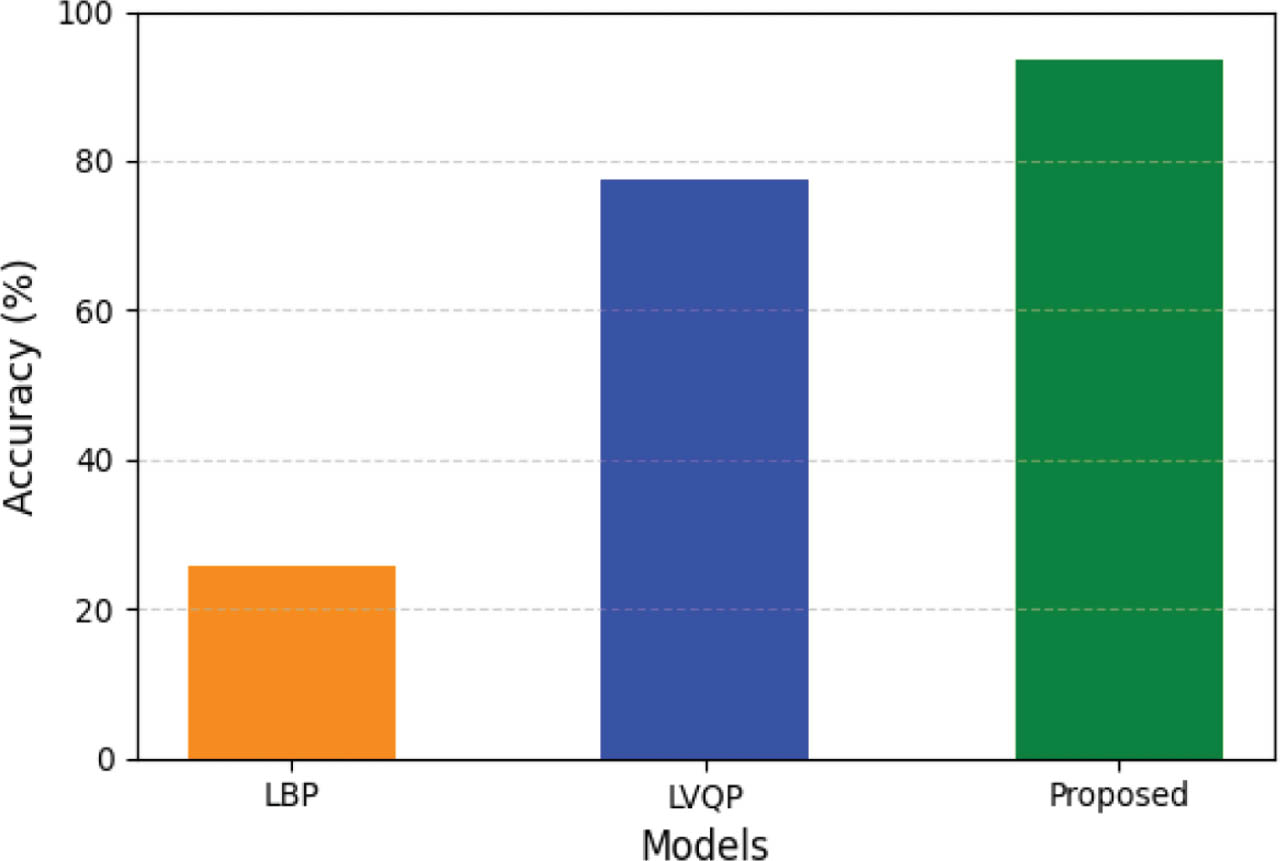
Figure 17:
Performance evaluation of various feature descriptors on the CASIA-C dataset under NW condition. NW, normal walking.
Table 8:
Ablation experiments on LD2oDP + SP-VLAD with CASIA-B dataset
| Method | Codebook size | Stride | SP-levels | 0° (%) | 90° (%) | 180° (%) |
|---|---|---|---|---|---|---|
| LD2oDP + SP-VLAD | 64 | 1 | [0, 1, 2] | 98.20 | 93.07 | 98.20 |
| LD2oDP + SP-VLAD | 64 | 2 | [0, 1, 2] | 96.85 | 85.40 | 97.30 |
| LD2oDP + SP-VLAD | 64 | 1 | [0] | 80.63 | 66.29 | 77.93 |
| LD2oDP + SP-VLAD | 64 | 2 | [0] | 56.76 | 38.61 | 57.66 |
| LD2oDP + SP-VLAD | 96 | 1 | [0, 1, 2] | 98.30 | 92.18 | 98.65 |
| LD2oDP + SP-VLAD | 96 | 2 | [0, 1, 2] | 98.20 | 87.71 | 95.95 |
Table 9:
Ablation experiments on LD2oDP + SP-VLAD with CASIA-C dataset
| Representation | Codebook size | Stride | SP-levels | FW (%) | SW (%) | BW (%) |
|---|---|---|---|---|---|---|
| LD2oDP + SP-VLAD | 64 | 1 | [0, 1, 2] | 81.32 | 76.37 | 36.26 |
| LD2oDP + SP-VLAD | 64 | 2 | [0, 1, 2] | 58.24 | 52.75 | 27.47 |
| LD2oDP + SP-VLAD | 64 | 1 | [0] | 32.97 | 37.91 | 17.03 |
| LD2oDP + SP-VLAD | 64 | 2 | [0] | 16.48 | 15.38 | 10.44 |
| LD2oDP + SP-VLAD | 96 | 1 | [0, 1, 2] | 81.32 | 76.37 | 36.26 |
| LD2oDP + SP-VLAD | 96 | 2 | [0, 1, 2] | 58.24 | 52.75 | 27.47 |