
I. Introduction
Gait is recognized as a behavioural trait that can be utilized for human identification. Other biometric modalities, including voice, signature, face, fingerprint, handwriting, and iris, are also available but typically require close-range capture and high-resolution images. In contrast, gait has gained considerable attention as a promising biometric feature due to its ability to identify individuals from a distance under low quality imaging without requiring their active cooperation [1]. Human gait identification can be categorized as either model-based or model-free [2]. However, many studies favor model-free approaches due to the high computational cost and relatively limited performance associated with model-based methods [3]. Numerous model-free techniques have been proposed in the literature, employing different strategies for feature extraction.
Key variables influencing a person's gait include clothing-induced appearance changes, variations in walking speed, surface conditions, footwear type, camera viewpoint, and the presence of carried objects [4]. These factors can significantly alter the appearance of the silhouette and reduce the reliability of recognition systems [5]. Gait energy image (GEI), a shortened depiction of the temporal dynamics of a person's gait, has been widely used to solve some of these issues. GEI reduces frame-level noise and captures both spatial and temporal properties by averaging silhouettes throughout a gait cycle. This makes feature extraction and classification easier. Despite these advantages, GEIs are sensitive to changes in covariates such as clothing or carried objects, which can obscure discriminative gait patterns and reduce recognition performance [5], [6]. In this context, local descriptors such as local directional second-order derivative pattern (LD2oDP) provide a robust mechanism for capturing fine-grained directional and gradient information from GEIs. When combined with vector quantization (VQ) methods such as vector of locally aggregated descriptors (VLAD) or its spatial pyramid variant (spatial pyramid vector of locally aggregated descriptors [SP-VLAD]), LD2oDP transforms local information into a global, discriminative representation, enhancing the ability to recognize individuals even under covariate variations. This approach leverages the advantages of GEI compact representation and temporal averaging while addressing its primary limitation by encoding covariate-robust features. By integrating local descriptor extraction, VQ, and spatial pyramid (SP) aggregation, the proposed method achieves enhanced recognition performance across varying conditions such as clothing variation, carrying scenarios, and different camera observation angles, thereby providing a significant improvement over basic GEI-based method.
The major contributions of this work are summarized as follows:
A novel LD2oDP descriptor that exploits second-order directional gradients, is proposed for gait representation. Unlike first-order descriptors, LD2oDP captures sharper local intensity variations, preserves structural edge details, and suppresses noise. This provides a more stable and discriminative local representation, which when combined with residual encoding, yields a powerful feature set for gait recognition.
The Integration of LD2oDP with an advanced VQ-based SP-VLAD framework is proposed to build a discriminative global representation. This is the first work in the gait recognition field to use SP-VLAD encoding with LD2oDP. This representation not only preserves fine-grained local variations but also captures multi-scale spatial structure, significantly improving global discriminability. This strategy reduces the bias introduced by outliers, ensures unequal contributions of inlier vs. outlier descriptors are properly balanced, and captures subtle variations that are often lost in fixed quantization methods.
Extensive evaluation and comparative analysis against state-of-the-art handcrafted descriptors such as local binary pattern (LBP), local vector quantization pattern (LVQP) show that our method achieves superior performance. Experimental results demonstrate that LD2oDP with SP-VLAD encoding consistently outperforms existing approaches.
The rest of the paper is structured as follows: Section “RELATED WORK” discusses the related works and the concepts that motivate the proposed method. Section “PROPOSED METHODOLOGY” describes the proposed methodology. Section “EXPERIMENTAL RESULT ANALYSIS” details the datasets, experimental settings, analysis of results, and ablation study. Finally, Section “CONCLUSION” concludes the paper.
II. Related Work
This section reviews local pattern-based descriptors, quantization and aggregation-based feature encoders, and other handcrafted gait feature extraction techniques, and provides a comparative analysis with the proposed method.
a. Local pattern-based descriptors
This section focuses on pixel-level or neighbourhood-based feature descriptors that capture local spatial variations in texture, shape, or motion. Local pattern descriptors are employed, to extract directional or fine-grained spatial information from images. They can be used for recognition tasks, and their main purpose is to encode local differences in directionality or strength. LBP is a well-known texture descriptor that encodes the relationship between a pixel and its neighbouring pixels into a binary code [7]. Several studies have explored the use of LBP-based descriptors for human gait recognition. To capture the texture of motion in gait sequences, [8] proposed the LBP Flow, which uses LBP on optical flow fields. This method offers a reliable representation for multi frame gait detection and recognition by encoding both spatial and temporal dynamics. In video surveillance scenarios, the technique increases tolerance to noise and background fluctuations by integrating LBP Flow with incremental hidden Markov models (HMMs). Local binary patterns from three orthogonal planes (LBP-TOP) was proposed in [9] as a dynamic texture descriptor to represent human gait in a spatiotemporal manner. Furthermore, [2] investigated the effectiveness of fuzzy local binary patterns (FLBP) for extracting more discriminative gait features from the GEI.
In the literature, two local pattern descriptors share the same abbreviation local derivative pattern (LDP) but represent different concepts. The local directional pattern (LDP) proposed in [10], encodes the dominant gradient or edge directions within a local neighbourhood, thereby capturing directional texture information. In contrast, the LDP proposed in [11], represents higher-order derivative information by computing differences among neighbouring pixels, which captures fine-grained local intensity changes. It is important to distinguish these descriptors, as their application and extracted information differ significantly. To further enhance directional discrimination, [12] introduced a concept of local directional derivative pattern (LDDP) by computing high-order directional derivatives along circular neighbours of a central pixel. While LBP only considers first-order intensity differences, LDDP captures second- or higher-order differences, providing richer discriminative information. Variants like rotation-invariant LDDP and centre-symmetric local binary pattern (CS-LBP) further improve robustness to rotations. But in LDDP, no convolution kernels are used, so derivatives are calculated directly between pixel intensity values along specific directions, making it effective for capturing fine-grained local variations in texture and motion. However, the absence of convolution kernels makes LDDP more sensitive to noise and small illumination fluctuations, especially when computing higher-order derivatives.
b. Quantization and aggregation-based feature encoders
This section covers techniques that move beyond pixel-level analysis and focus on encoding or aggregating local features into more compact, discriminative representations. In [13], LVQP was proposed to enhances traditional local pattern descriptors, by applying VQ to the difference vector between a central pixel and its neighbouring pixels. Unlike LBP, which performs scalar quantization on each pixel difference independently, LVQP quantizes the entire difference vector using a codebook trained via the Linde–Buzo–Gray (LBG) algorithm. This global quantization preserves inter-element relationships and improves rotation invariance. But LVQP is less robust to noise, because pixel intensity fluctuations directly affect difference vector.
In [14], the VLAD was introduced as a compact representation that aggregates local residuals into a global image descriptor without requiring access to individual features at runtime. By improving vocabulary adaption and normalization, the authors were able to further enhance VLAD and achieved higher retrieval accuracy. The resulting multi-VLAD frameworks offers improved compactness and scalability compare to conventional encoding methods, particularly for images containing small or localized objects. Although VLAD is a popular method for encoding local descriptors into compact representations, but it discards spatial information, which limits its discriminative power. To address this, [15] proposed SP pooling, which aggregate VLAD vectors within sub-regions at multiple resolutions to retain spatial context. Additionally, a new normalization strategy using the Euclidean norm of the entire image improves consistency across subregions. These modifications enhance VLAD's performance while maintaining compactness.
Traditional local descriptors such as LBP [7], and LDP [10] have been employed for gait analysis. While these methods capture local variations, they often fail to represent higher-order directional information, making them sensitive to noise and illumination. On the other hand, deep learning-based approaches demand large-scale training data and significant computational resources, which limits their applicability in real-time scenarios. Hence, there is a pressing need for a lightweight yet robust local descriptor that can effectively capture fine-grained structural changes while maintaining stability under challenging conditions such as noise, background variations, and view changes. The proposed LD2oDP descriptor that goes beyond intensity-based LBP and first-order gradient-based descriptors by explicitly modelling second-order directional derivatives. It extracts sharper variations by emphasizing curvature and contour strength, thereby providing more distinctive structural cues. Unlike LDDP [12], which relies on fixed quantization of derivative responses, the proposed approach suppresses noise using directional masks and integrates with residual-based encoding, ensuring that fine variations are preserved without being dominated by outlier descriptors. This makes LD2oDP both more robust and more discriminative compared to existing handcrafted descriptors. LD2oDP with SP-VLAD is introduced to build a discriminative global representation. While most existing handcrafted gait descriptors rely on direct quantization schemes or local histograms, the proposed framework integrates robust local encoding with hierarchical VLAD aggregation. This design preserves fine-grained local variations while capturing multi-scale spatial structure, thereby significantly enhancing global discriminability. The proposed aggregation strategy reduces bias introduced by outliers, balances the contributions of inlier and outlier descriptors, and captures subtle gait variations that are often lost in fixed quantization-based methods.
c. Handcraft and hybrid gait features extraction methods
Handcrafted gait feature extraction methods have historically played a significant role in gait recognition due to their interpretability and low computational cost. Although recent research trends (2023–2025) increasingly favor hybrid or lightweight learning-based frameworks, handcrafted descriptors remain highly relevant, particularly in scenarios involving limited training data, constrained hardware, or the need for explainable models. This section reviews representative hand-crafted and hybrid gait feature extraction approaches, highlighting their design principles, robustness under covariate variations, and evolution over time.
Table 1 presents a summary of recent hand-crafted and hybrid gait feature extraction methods (2017–2025), including feature types, datasets, covariates, and key contributions. It is worth noting that recent works from 2023 to 2025 increasingly adopt hybrid or lightweight learning frameworks, while purely handcrafted gait recognition methods have become less common, highlighting the need for robust and interpretable handcrafted descriptors such as the proposed LD2oDP. From Table 1, the following observations can be made:
Feature diversity: Methods employ a variety of representations, including silhouette-based shape/texture, optical-flow motion features, skeleton landmarks, and GEI-based descriptors. Hybrid approaches combining multiple feature types generally improve robustness.
Covariate handling: Most methods address common gait covariates such as clothing, carrying conditions, walking speed, and viewpoint variations. Skeleton-based methods, such as OptiGait-LGBM [27], also handle outdoor uncontrolled environments.
Classifier and fusion strategies: Combining handcrafted features with encoding schemes (e.g., Fisher Vector) or deep metric learning improves discriminability and accuracy. Ensemble learning and decision-tree-based classifiers further enhance performance.
Performance trends: Accuracy varies depending on covariates, dataset complexity, and the type of features used. Hybrid and multi-feature approaches generally achieve higher accuracy than single-feature methods.
Table 1:
Summary of handcrafted and hybrid gait feature extraction methods
| Ref. | Year | Feature used | Dataset used | Type of representation | Covariates | Key contribution | Finding |
|---|---|---|---|---|---|---|---|
| [16] | 2017 | MHI, BSIF, HOG | OU-ISIR D, CASIA-B, CMU MoBo | Skeleton-based motion features | Walking speed variations | Proposed a hybrid handcrafted descriptor pipeline that combining motion template (MHI), texture encoding (BSIF), and gradient information (HOG). | The fusion of motion, texture, and gradient descriptors was more effective than using any single handcrafted descriptor alone. |
| [17] | 2018 | Motion-based local descriptors + Fisher Vector encoding | TUM GAID and CASIA-A datasets | Motion-based (spatio-temporal) | - | Proposed a spatio-temporal gait recognition algorithm combining handcrafted motion features, Fisher Vector encoding, and linear SVM classification. | Showed that combining Fisher Vector encoding with motion-based descriptors improved gait recognition robustness and discriminative power. |
| [18] | 2020 | HTG | OU-ISIR D, CASIA-B, CMU MoBo | Silhouette based, Shape/texture representation | - | Proposed a new descriptor: HTG that accumulates temporal pixel gradients instead of just spatial gradients (unlike HOG). | The temporal gradient encoding improved robustness by incorporating dynamic motion cues in addition to static shape cues. |
| [19] | 2021 | SIFT, SURF, Shi-Tomasi edge corner detector | CASIA-A | Silhouette-based, shape/texture representation | General variations | Evaluation of individual and combined feature descriptors (SIFT, SURF, Shi-Tomasi) with multiple classifiers for gait recognition. | Combining descriptors improved recognition accuracy, and Random Forest gives the highest accuracy on CASIA-A. |
| [20] | 2021 | PVTM | CASIA-B | Silhouette-based, shape | View variation, carrying bag, clothing | Proposed PVTM that transforms semantically selected gait parts across views to mitigate angle variation and covariate factors. | Achieved better recognition accuracy than multi-view baselines on CASIA-B, proving robustness under bag-carrying and clothing variations. |
| [21] | 2022 | SURF, HOG, HOF, MBH | KTH, YouTube, and UCF50 datasets | Optical flow-based motion representation | - | Proposed a video representation for motion recognition called MoSURF, which integrates multiple complementary descriptors | Combined motion-based and appearance-based features for more robust recognition in video. |
| [22] | 2022 | HOG | CASIA-B | Silhouette-based (GEI representation) | Clothing, Carrying | Proposed GEI + HOG + SVM approach for gait recognition under clothing and carrying covariates | Clothing changes affected recognition less than carrying conditions. |
| [23] | 2022 | ISMAEI (derived from active energy image with mid-body masking using Improved-Sobel-Masking operator) | CAISA-B, TUM-GAID | Hybrid: Appearance + Silhouette-based (Shape 27 Motion AEI) | Clothing, carrying | Proposed a two-branch Re-ID framework that fuses deep appearance features (ResNet50) with handcrafted gait features (ISMAEI) to handle covariate changes in long-term person Re-ID. | Achieved better Rank-1 and mAP on CASIA-B and TUM-GAID. |
| [24] | 2023 | LR2P descriptor (Local Rotation Robust Pattern) | OU-ISIR B, CASIA-B | GEI based shape and motion representation | Rotation and clothing | Introduced the handcrafted LR2P descriptor for gait recognition, which is rotation- and clothing-invariant | On OUISIR B dataset achieved 86.12% accuracy across different clothing sets. On CASIA-B dataset achieved 92.02% accuracy across 32 tests. |
| [25] | 2025 | LFHEI | CASIA-A, CASIA-B | Optical flow-based motion representation | - | Combined handcrafted LFHEI with deep metric learning to build a robust embedding space. | Showed that frontal-view gait recognition was feasible. Achieved 95.0% accuracy on CASIA-A and 89.9% on CASIA-B datasets. |
| [26] | 2025 | SIFT, SURF | CAISA-A | Silhouette-based, Shape/texture representation | - | Evaluated SIFT and SURF features for non-intrusive gait recognition using Decision Tree and Random Forest classifiers. | Random Forest achieved higher accuracy (87.80%) on CASIA-A, and showed effectiveness of these feature-classifier combinations. |
| [27] | 2025 | Skeletal landmarks + LightGBM | RUET-GAIT | Skeleton-based | Outdoor uncontrolled environment | Proposed OptiGait-LGBM model for skeleton-based gait recognition with low memory usage and minimal computational cost. | Outperformed ensemble methods (Random Forest, CatBoost) in accuracy, memory usage, and training time. |
[i] BSIF, binarized statistical image features, GEI, gait energy image; HOG, histogram of oriented gradients, HTG, histogram of temporal gradients, LFHEI, local fuzzy histogram energy image, MBH, motion boundary histograms, MHI, motion history image, PVTM, part view transformation model, SIFT, scale-invariant feature transform, SURF, speeded-up robust features, SVM, support vector machine.
Based on the observations from recent hybrid and handcrafted gait recognition methods summarized in Table 1, some key challenges and open research issues can be identified.
Limited handling of cross-view variations in many handcrafted descriptors.
Dependency on controlled datasets for evaluation, real-world, unconstrained scenarios are less explored.
Computational efficiency and scalability for large datasets need improvement.
Only a few methods explicitly model temporal dynamics in gait sequences.
Integration of handcrafted features with deep learning is still limited, more work is needed to achieve low-complexity, high-accuracy solutions.
III. Proposed Methodology
The proposed overall framework of the gait-based person recognition system is illustrated in Figure 1. The method integrates a novel LD2oDP descriptor with an advanced VQ-based SP-VLAD encoding scheme to extract compact and discriminative gait representations. The silhouette sequence is first converted into a GEI image, from which local descriptors (LD2oDP) are extracted. These descriptors are quantized using a learned dictionary and aggregated into residual vectors via VLAD encoding at each cell of the SP. Finally, VLAD vectors across all levels are concatenated to form the final SP-VLAD feature representation. The feature vectors are then fed into a support vector machine (SVM) classifier trained in a one-vs-all strategy to perform subject identification. The integration of LD2oDP descriptors with SP-VLAD encoding results in highly discriminative and compact feature vectors that enhance recognition performance across varied viewing angles and covariate conditions.
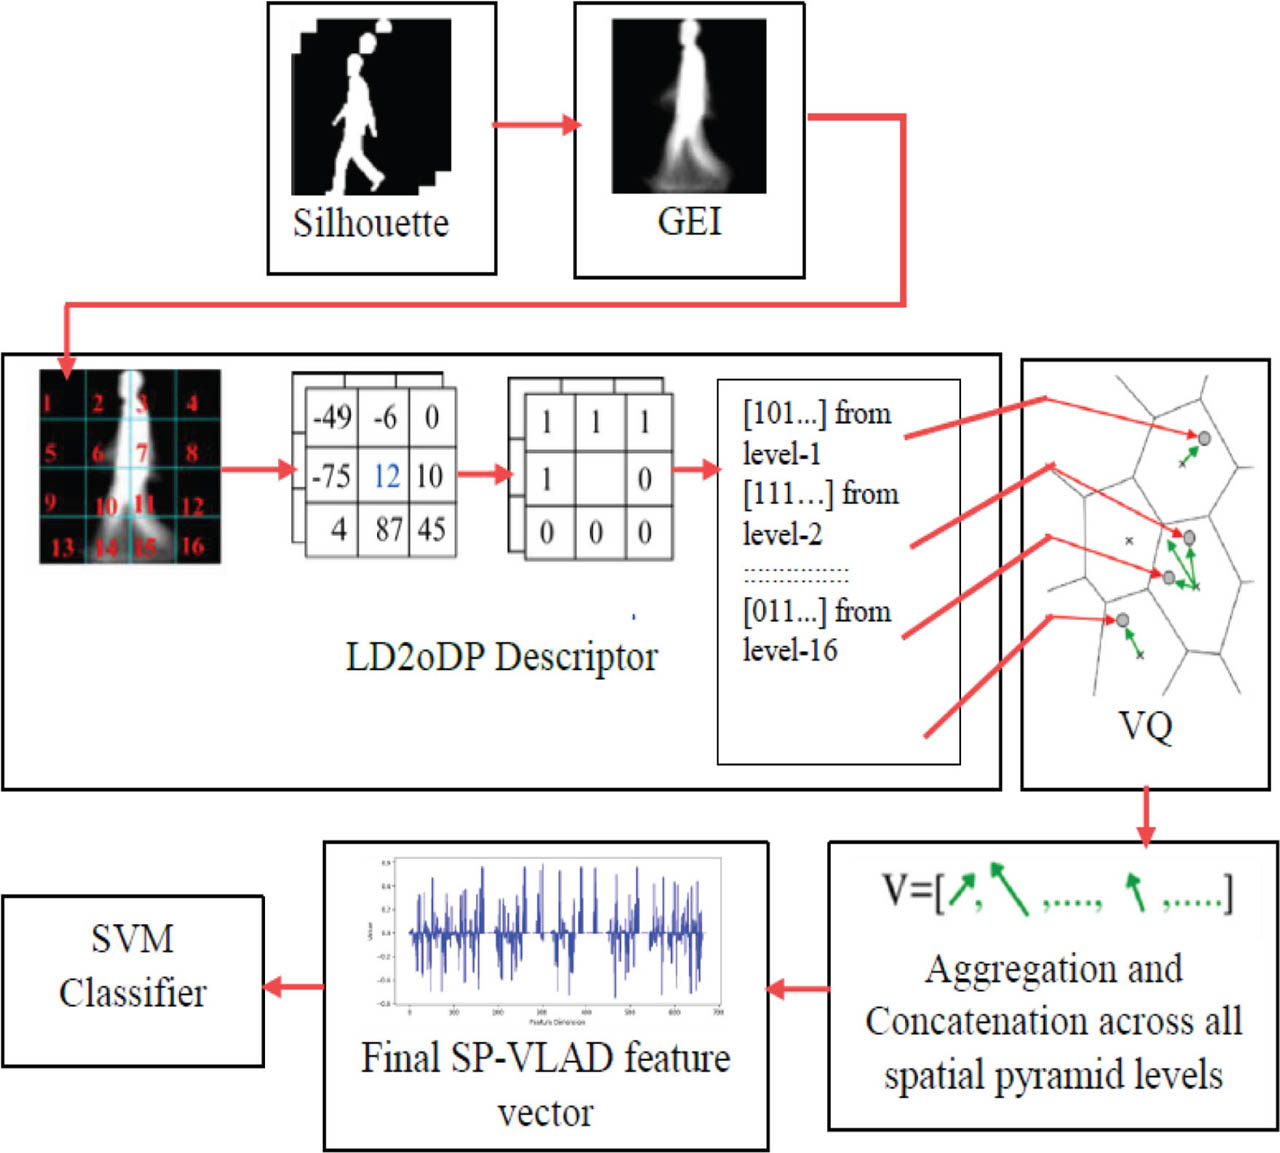
Figure 1:
Block diagram of proposed methodology. GEI, gait energy image; LD2oDP, local directional second-order derivative pattern; SP-VLAD, spatial pyramid vector of locally aggregated descriptors; SVM, support vector machine; VQ, vector quantization.
a. Local descriptor extraction: LD2oDP
We consider a GEI image I and denoted the central pixel at the location (ic, jc) with intensity I(ic, jc). Let represent the eight neighboring pixels in 3 × 3 neighborhood centered at (ic, jc), excluding the central pixel. Let Rθ be the Robinson mask with θ direction θ ∈ {0°, 45°, 90°, 135°, 180°, 225°, 270°, 315°}, as illustrated in Figure 2.
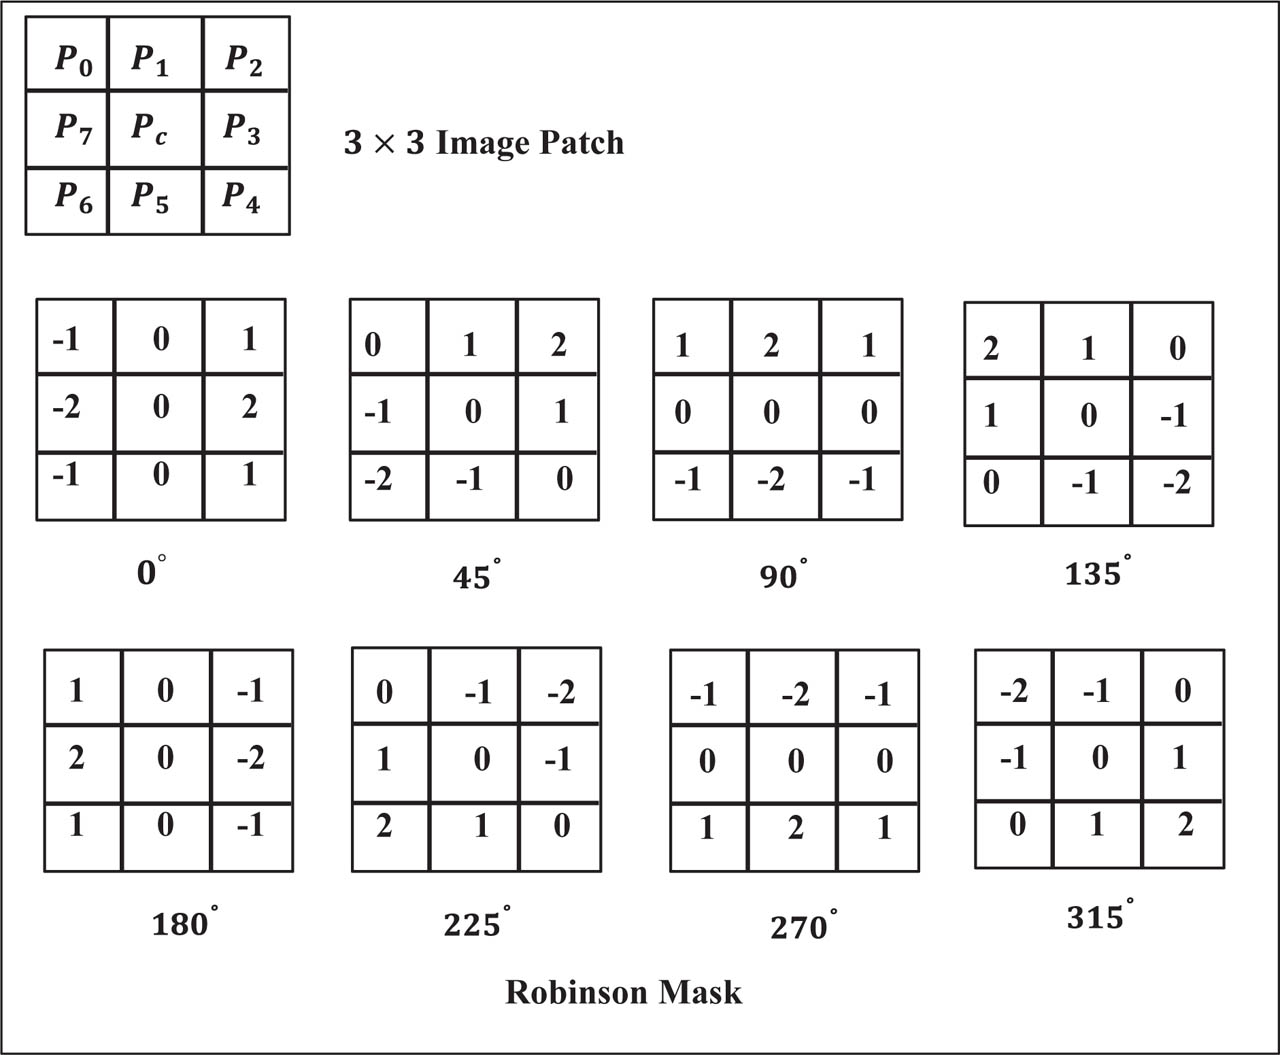
Figure 2:
Robinson mask with 3 × 3 image patch.
The first-order directional derivative of the image along direction θ at pixel location (ic, jc) is computed by convolving a 3 × 3 image patch Ipatch with the corresponding Robinson mask as described in Eq. (1).
Where Ω = {(δi,δj)|δi, δj ∈ {−1, 0, 1}} denotes the 3 × 3 neighborhood centered at (ic, jc).
Each directional derivative matrix highlights the edges in a particular direction (0°, 45°, 90°, 135°, 180°, 225°, 270°, 315°). The robinson mask help in smoothing the image and reducing high frequency noise that could otherwise affect the derivative calculation. The second order derivative pattern for θ is defined as
Where each element bv is computed as
The second-order LDP for θ direction encodes local changes (sign changes) of the derivative in that direction. For each derivative directional channel, we collect sampled 8-bit binary codes shown in Figures 3 and 4. Rather than fixing the descriptor extraction to a single density, a sampling stride is introduced as a controllable parameter to balance discriminative power and computational efficiency. The stride determines the spatial interval at which LD2oDP descriptors are extracted from the GEI. In this work, a stride of 1 corresponds to dense descriptor extraction, where features are computed at every pixel location, while larger strides result in sparser sampling. Dense sampling preserves fine-grained spatial variations in silhouette contours and motion boundaries, which are crucial for robust gait representation. Although larger strides reduce computational cost, they may discard subtle local structural information. Therefore, stride = 1 is adopted throughout all experiments.
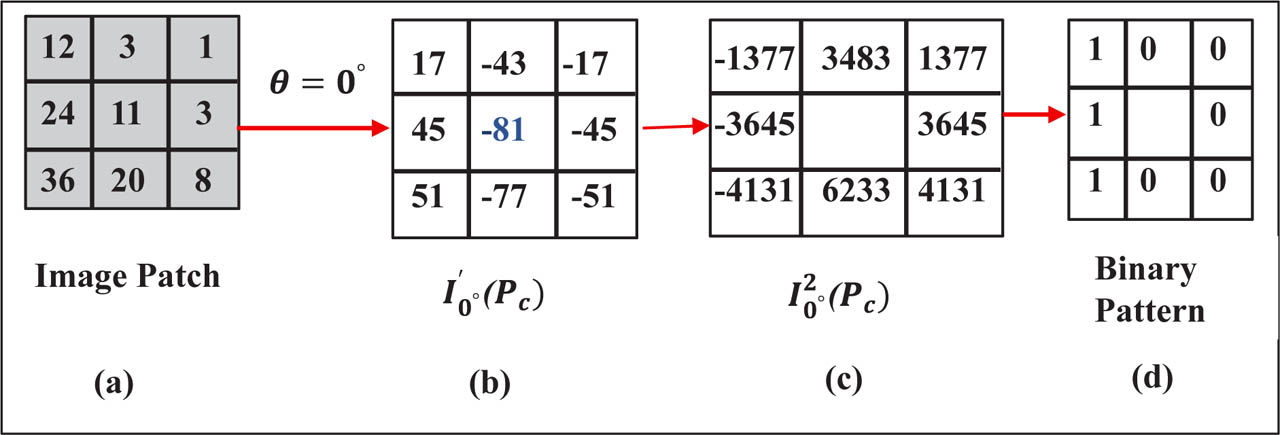
Figure 3:
Example calculation of with θ = 0. The reference pixel Pc is highlighted in blue. (A) GEI image patch. (B) First-order directional derivative response at direction. (C) Second-order directional derivative response at direction. (D) Generated binary pattern at direction.
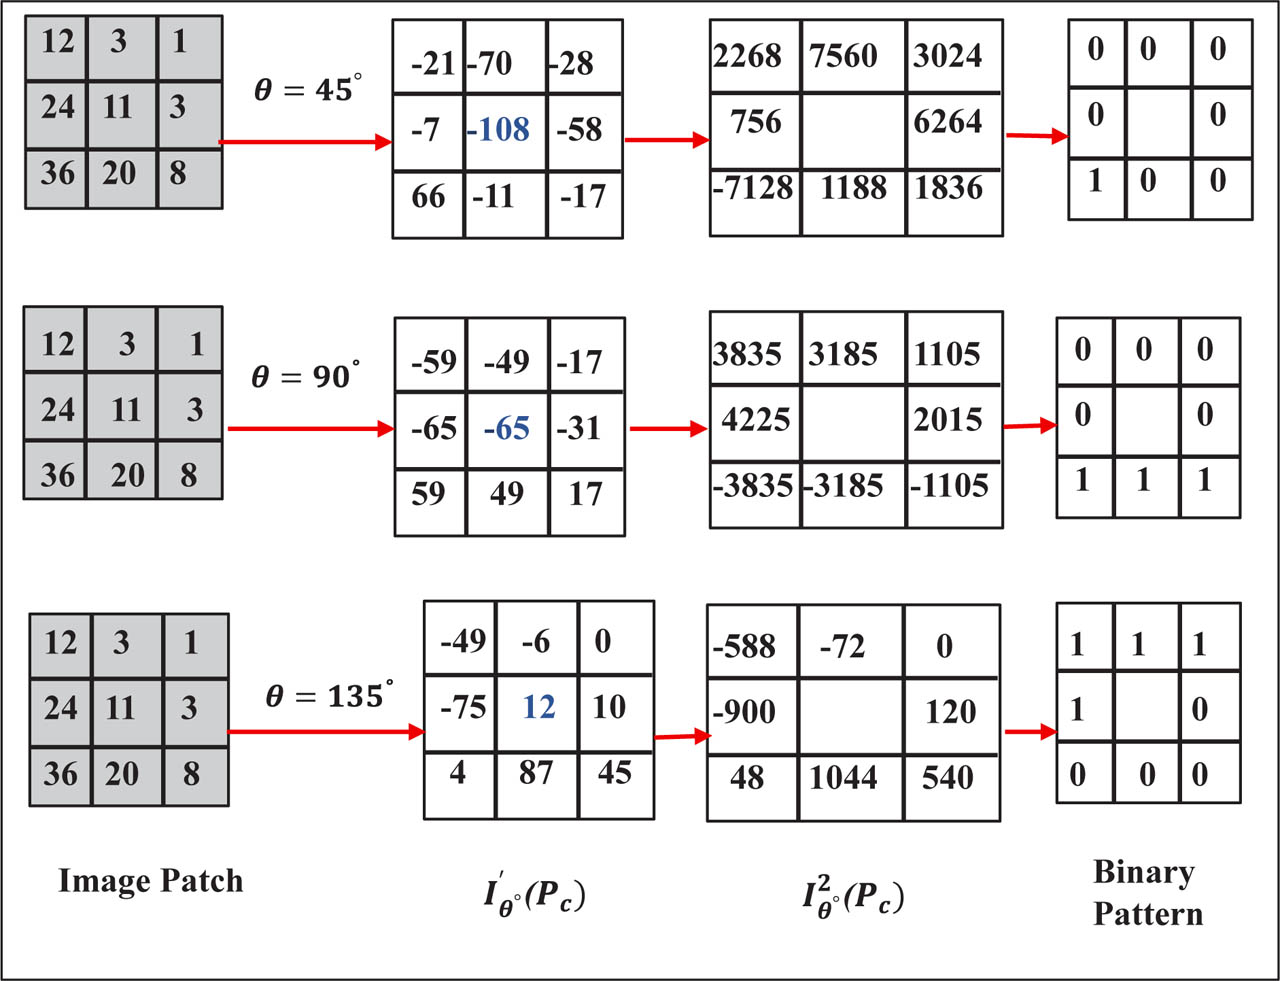
Figure 4:
Example calculation of with θ = 45°, 90°, 135°.
The set of extracted descriptors is defined in Eq. (3).
Where, S = sampled pixels.
To demonstrate the calculation of second-order derivatives, along θ = 0°. We begin with a 3 × 3 image patch as shown in Figure 3A. The first-order derivatives along θ = 0° at the central pixel Pc and its neighbouring pixels are obtained by convolving the patch with the Robinson mask oriented in the 0° direction, as illustrated in Figure 3B. Subsequently, the second-order derivatives along θ = 0° are computed by multiplying the intensity of the central pixel with that of each of its neighbouring pixels, as depicted in Figure 3C. Furthermore, the obtained results are encoded as given in Eq. (2). We obtained 8-bit binary patterns as shown in Figure 3D. Similarly, the calculation of can be performed for direction θ = 0°, 45°, 90°, 135°, 180°, 225°, 270°, 315°. For illustration, the results for for θ = 45°, 90°, 135° are shown in Figure 4.
The LVQP descriptor relies on first-order derivatives. however, its quantization may lose fine variations. In contrast, the proposed LD2oDP–SP-VLAD descriptor first applies the Robinson directional mask, which reduces high-frequency noise and provides smoothing. Subsequently, second-order derivatives are computed to capture sharper intensity transitions, such as edges and contours, resulting in distinct intensity values for the central pixel Pc. Consequently, the pixel intensity values obtained from LVQP and LD2oDP with VQ differ. Figures 5–7 illustrate this difference.
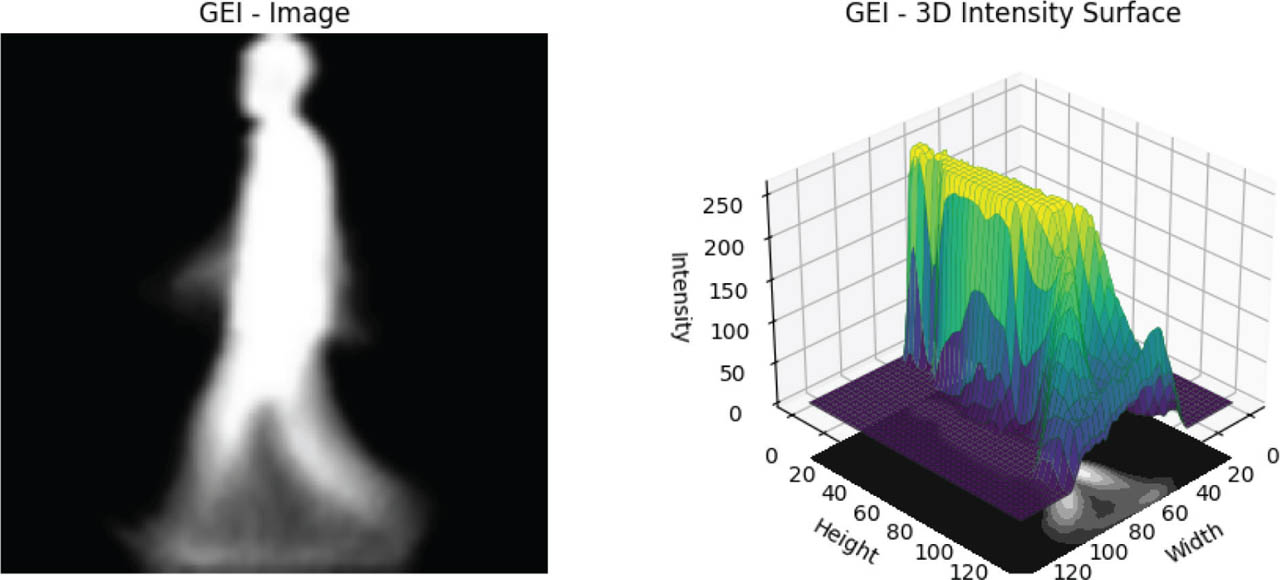
Figure 5:
GEI representation of a sample subject and corresponding intensity plot. GEI, gait energy image.
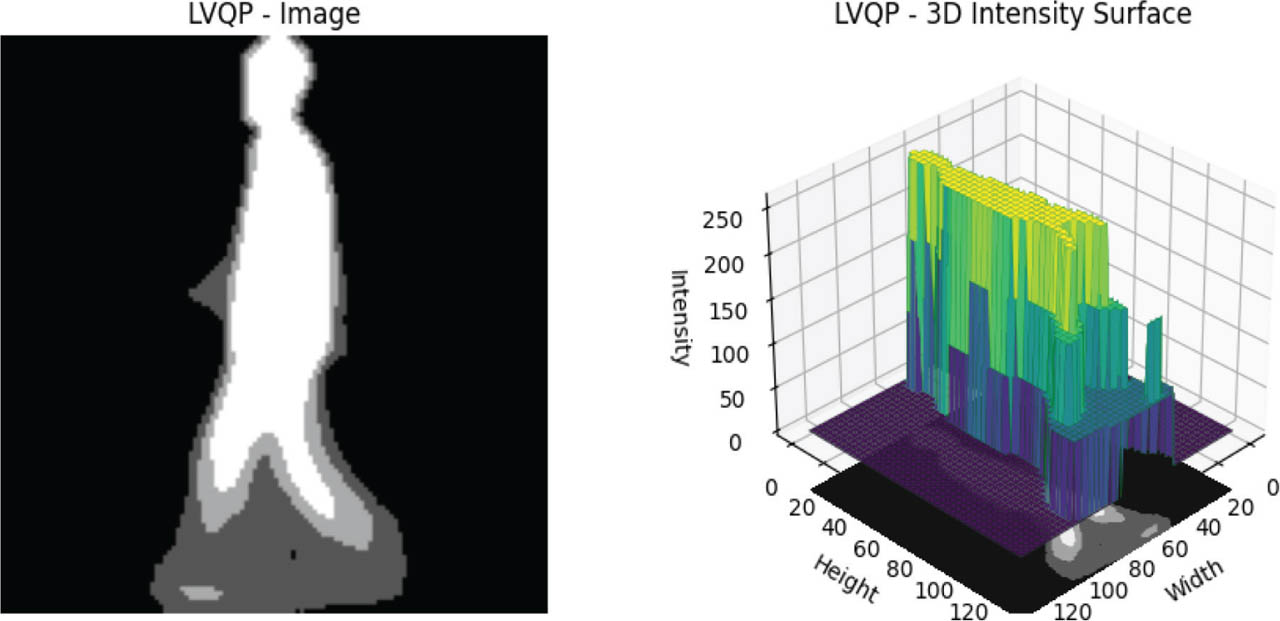
Figure 6:
LVQP descriptor and corresponding intensity plot. LVQP, local vector quantization pattern.
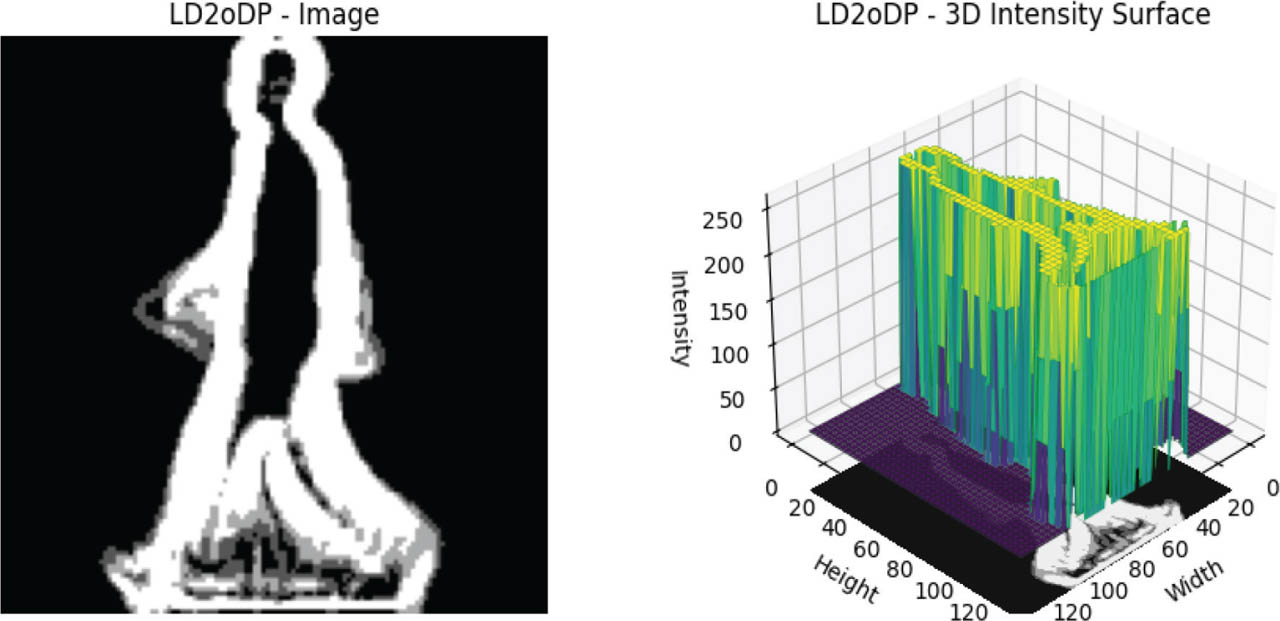
Figure 7:
LD2oDP descriptor with simple VQ and corresponding intensity plot. LD2oDP, local directional second-order derivative pattern; VQ, vector quantization.
For visualization purposes, we employ a simplified quantization scheme, which discretizes directional responses into a limited number of intensity levels to highlight variations across the GEI. This facilitates interpretation of the distribution of local directional patterns. Additionally, 3D surface plots are provided to reveal the spatial distribution of response magnitudes. However, in the actual recognition pipeline, we adopt true VQ within SP-VLAD, ensuring that the final global representation remains data-driven and highly discriminative.
b. VQ with SP-VLAD
Traditional scalar quantization of local patterns often causes information loss, particularly in flat regions or under low noise, where similar local structures may generate significantly different codes. To overcome this limitation, we employ VQ, which maps each LD2oDP descriptor to the nearest centroid of a learned dictionary (codebook). The codebook is generated using the MiniBatch K-Means algorithm as described in Algorithm 1, ensuring efficient learning even with large-scale descriptor sets. VQ produces compact and discriminative residuals by encoding each descriptor relative to its assigned centroid. VQ is more resilient to noise and intensity homogeneity, while also producing compact and discriminative feature representations. Due to its efficiency and robustness, VQ has been widely adopted in applications such as image retrieval, image compression, retrieval, and secure communication [13]. However, it is not yet utilized for gait recognition as per my knowledge. In this framework, VQ serves as the foundation for encoding LD2oDP descriptors within the SP-VLAD structure.
To efficiently cluster a large set of LD2oDP descriptors, the MiniBatch K-Means algorithm is employed. Unlike standard K-Means, which updates cluster centroids using the entire dataset at each iteration, MiniBatch K-Means performs incremental updates using small randomly sampled batches, significantly reducing computational cost while maintaining clustering quality. Given a set of LD2oDP descriptors X = {x1, x2,…,xN}. where xe ∈ ℝd, the objective is to minimize the sum of squared distances between descriptors and their assigned cluster centroids.
Where, CI ∈ ℝd denote the lth cluster centroid, and the assignment function is defined as
The distance between descriptor and centroid is
Algorithm 1: MiniBatch K-Means
Input:
LD2oDP descriptors X = {x1, x2,…,xN} where xk ∈ ℝd
Number of clusters K
Mini-batch size B
Maximum iterations T
Output:
Cluster centroids C = {c1, c2,…,cK}
Algorithm:
Initialize centroids C = {c1, c2,…,cK} by randomly selecting K points from X.
For each iteration t = 1, 2, … T do:
Sample a mini-batch M ⊂ X, with |M| = B.
For each x ∈ M do:
Assign x to the nearest centroid:
Update the centroid ck* incrementally:
Where and ηk* is the number of points assigned to cluster k* so far.
Repeat until convergence or until max iteration T is reached.
Once the codebook is constructed, the VLAD encoding procedure is applied to aggregate the information from the assigned descriptors. Instead of simply counting the occurrences of visual words, VLAD accumulates the residuals between each descriptor and its corresponding cluster centroid. This residual accumulation captures both the distribution and direction of deviations, leading to a more powerful representation. For each cluster centroid, the residuals of all descriptors assigned to it are summed. For each centroid, ck, accumulate residuals of assigned descriptors is defined as
The resulting vectors are concatenated into a single high-dimensional representation.
To prevent the dominance of large magnitude responses, a two-step normalization strategy is applied. power normalization, which suppresses burstiness by dampening large values, followed by L2 normalization to ensure scale invariance.
This normalization process enhances the discriminability of the encoded feature vectors, particularly when dealing with gait data where intensity variations may be subtle but important.
To further enhance spatial awareness, we introduce a SP partitioning scheme within the VLAD framework. The GEI is hierarchically divided into increasingly finer grids across multiple pyramid levels. Partitioning the GEI ensures that VLAD encoding respects the spatial arrangement of gait motion patterns (top = head/arms, middle = torso, bottom = legs). At the coarsest level, the whole GEI is treated as a single cell, while at higher levels, the image is split into smaller subregions, such as a 2 × 2 grid at level 1 and a 4 × 4 grid at level 2. For each cell at each level, independent VLAD encoding is performed, producing a local residual vector that characterizes the distribution of descriptors within that spatial subregion. This hierarchical partitioning enables the model to capture not only global variations in gait but also fine-grained, localized structural differences in body movement patterns, which are often critical for robust recognition.
Finally, the VLAD vectors computed from all cells across all pyramid levels are concatenated to form the final SP-VLAD feature vector.
Where, v(0) represent VLAD of whole image, vf(0) denote VLAD vector extracted from the fth spatial cell at pyramid level 1. The number of cells at the level 1 is given by
In this work Lmax = 2, corresponding to spatial partitions of 1 × 1, 2 × 2, and 4 × 4. This concatenated representation integrates information across multiple spatial scales, effectively combining global gait characteristics with localized motion cues.
We employ larger codebook sizes (e.g., 64) during recognition, since they allow finer partitioning of the feature space and capture more discriminative details. However, for illustration purposes, we present visualizations with smaller codebook sizes (e.g., 4), because they provide a clearer and more interpretable depiction of the residual distributions and SP assignments. Using a high codebook size in the figures would lead to cluttered and less informative visualization.
Figure 8 visualize the SP level-2 with LD2oDP descriptor. In the Figure 8, each arrow starts at a position in the image where the descriptor was extracted. The arrow points in the direction of the residual between the descriptor and its assigned cluster centre. The direction of arrow represents how this local feature deviates from its visual word centre. Length of arrow describes the size of that deviation (but normalized in the plot for visibility) and the arrow colour indicate which visual word (cluster) that feature belong to. VLAD residual histogram at each SP level-0, level-1, level-2 are illustrated in Figures 9–11 respectively. The VLAD residual histograms at each SP level capture the direction and magnitude of deviation of local descriptors from their assigned cluster centres. Positive and negative values indicate whether descriptors tend to lie above or below the cluster centre along each dimension, revealing local feature distribution patterns across different spatial regions. Combined VLAD residual histogram at SP level-1 and level-2 is visualized in Figure 12. The combined VLAD residual histogram at Level-2 highlights the dominant visual words at this spatial scale. Unlike traditional histograms, the presence of both positive and negative values reflects not only the contribution of each cluster but also the direction of deviation of local descriptors from their cluster centres.
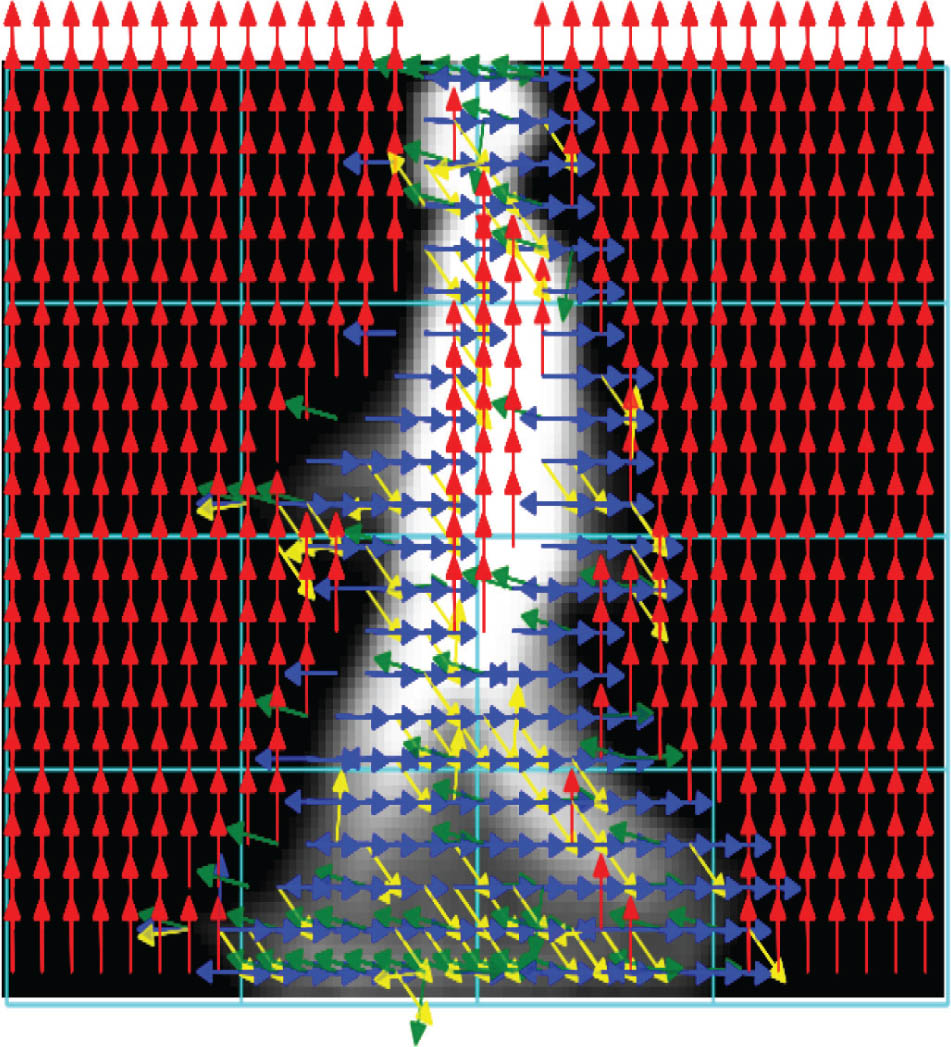
Figure 8:
Visualization of the SP level 2 with LD2oDP descriptor. LD2oDP, local directional second-order derivative pattern; SP, spatial pyramid.
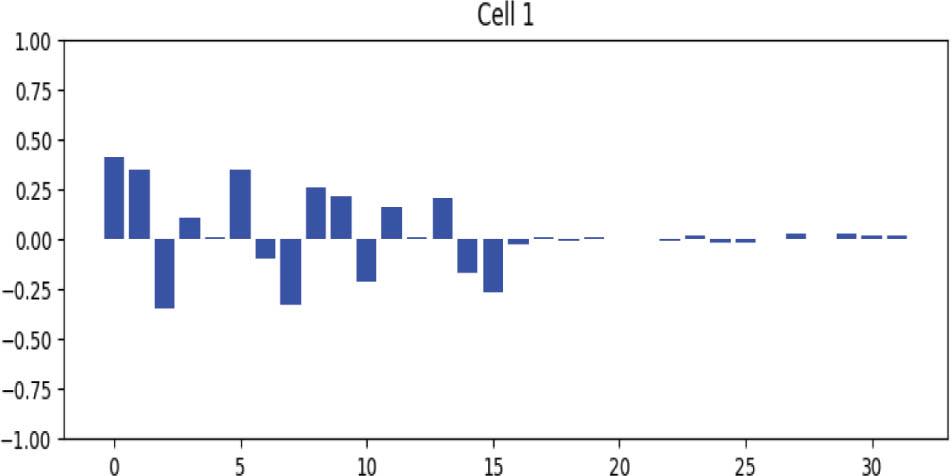
Figure 9:
VLAD residual histograms across SP level-0. SP, spatial pyramid; VLAD, vector of locally aggregated descriptors.
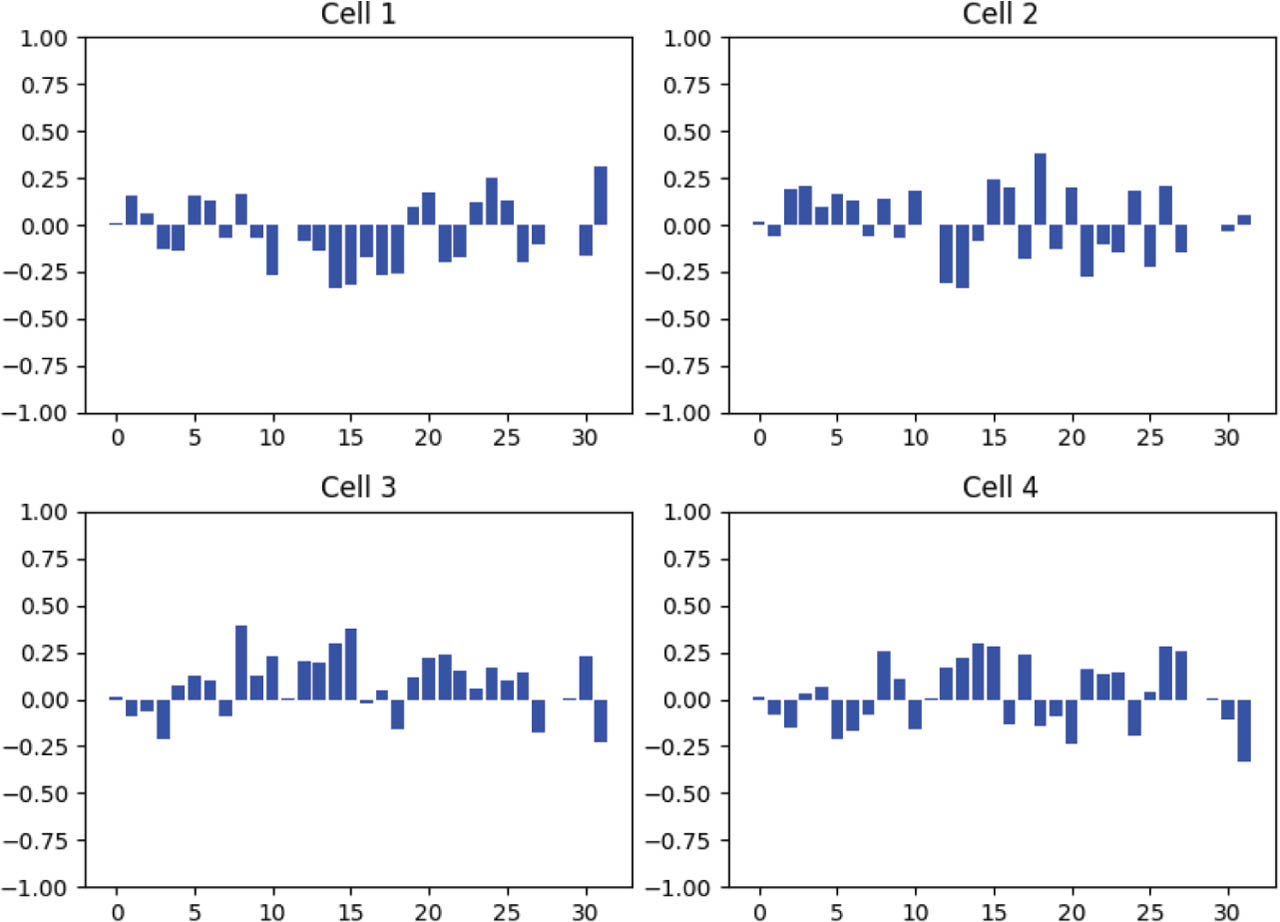
Figure 10:
VLAD residual histograms across SP level-1. SP, spatial pyramid; VLAD, vector of locally aggregated descriptors.
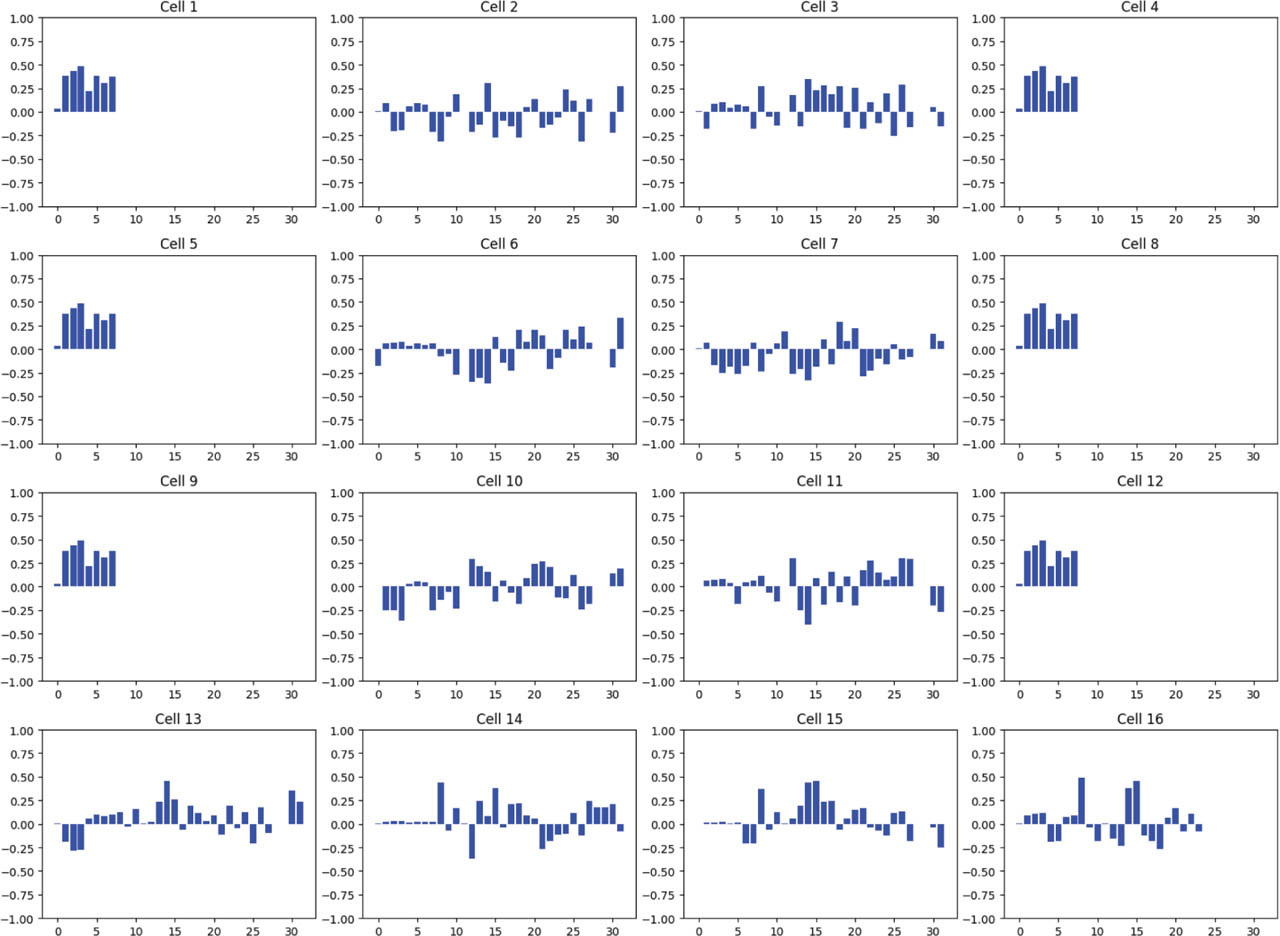
Figure 11:
VLAD residual histograms across SP level-2. SP, spatial pyramid; VLAD, vector of locally aggregated descriptors.
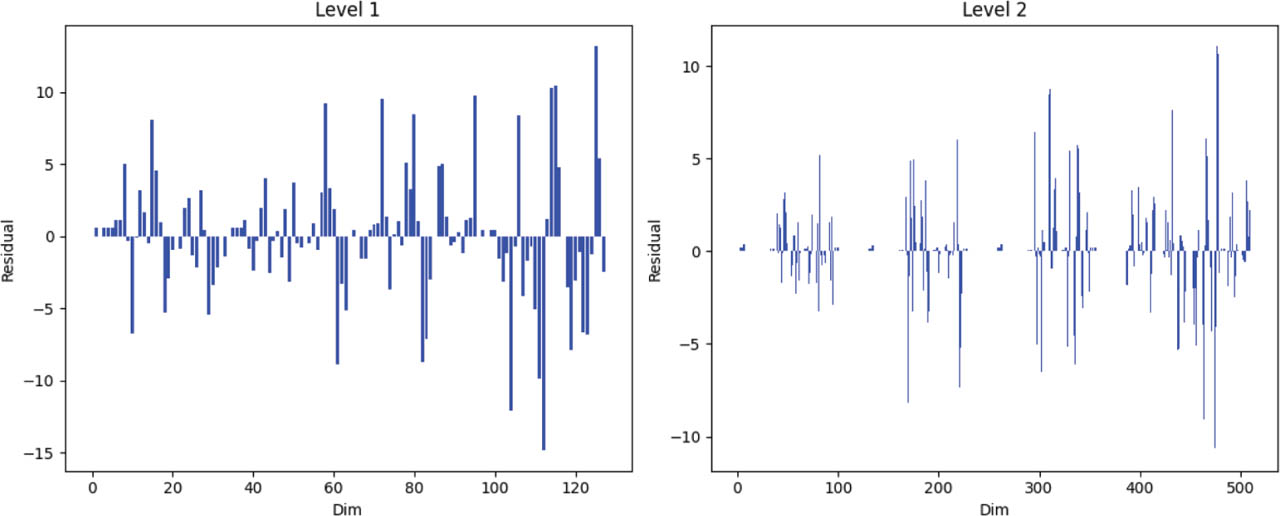
Figure 12:
Combined VLAD residual histograms across SP level-1 and level-2. SP, spatial pyramid; VLAD, vector of locally aggregated descriptors.
IV. Experimental Result Analysis
The two widely used public gait databases, namely the CASIA-B gait dataset [28], and the CASIA-C gait data-set [29], are employed to evaluate the effectiveness of the proposed method. Each dataset is first described in detail, including its overall structure as well as the training and testing protocols. Subsequently, the performance of the proposed method is compared with existing state-of-the-art gait recognition methods. All algorithms and experiments were implemented in Python using Google Collab, leveraging its available computational resources, including free GPU support. During the implementation phase, all gait sequences were converted into GEIs and resized to a fixed resolution of 128 × 88 pixels for the CASIA-B dataset and 64 × 64 pixels for the CASIA-C dataset prior to feature extraction. The LD2oDP descriptor computes second-order directional gradients using eight Robinson compass masks, and a stride of 1 was adopted for both datasets to enable dense sampling of local gait patterns. The extracted local descriptors were subsequently encoded using a SP-VLAD scheme with a codebook size of 64 and three SP levels (levels 0, 1, and 2).
a. CASIA-B dataset
The CASIA-B dataset contains gait recording of 124 individuals. Everyone's walking style is captured under the different conditions, including normal walking (NW), walking while carrying a bag, and walking while wearing a coat. These walking style of the persons are captures from 11 camera viewpoint around each subject, ranging from 0° to 180° in 18° increments. Some examples of GEI image from 0°, 90° and 180° view of CASIA-B dataset are shown in Figure 13.
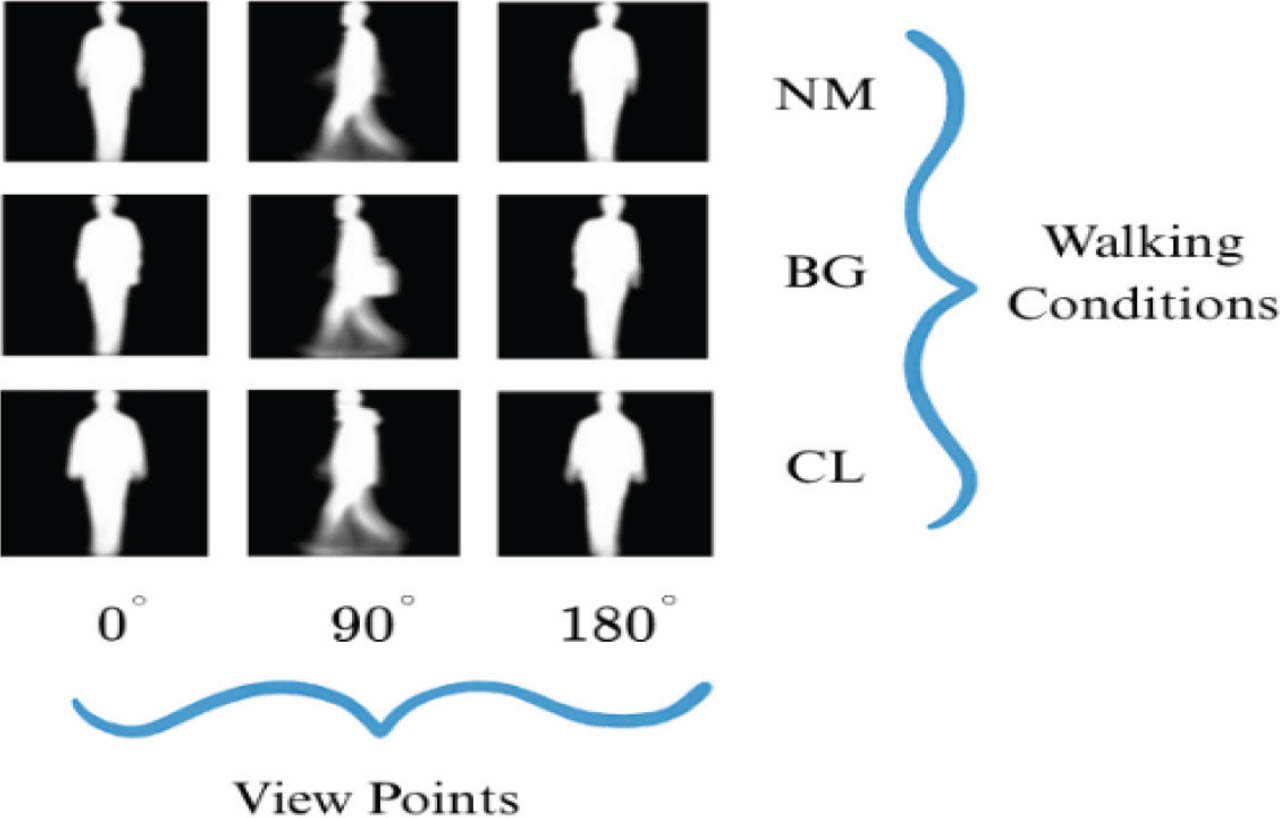
Figure 13:
Sample GEI image examples from the CASIA-C dataset. GEI, gait energy image.
A series of experiments were conducted on the CASIA-B gait database. In this dataset, each subject has six NW sequences (denoted as Data A), two sequences involving carrying variations such as walking with a bag (denoted as Data B), and two sequences with clothing variations (denoted as Data C). In the first experiment, the initial four NW sequences from Data A (referred to as Data A1) were used for training, while the remaining two NW sequences (referred to as Data A2) were used for testing. The experimental results in terms of accuracy, precision, recall, and F1-score are reported in Table 2, and detailed comparison of accuracy with existing methods is presented in Tables 3A and 3B. These results demonstrate that the proposed method achieves superior or highly competitive performance across multiple viewing angles. In the second experiment, Data A1 (four NW sequences) was used for training, and the two sequences from Data B were employed to test robustness against carrying variations. The corresponding results are summarized in Table 4. In the third experiment, Data A1 was again used for training, while the two sequences from Data C were utilized to evaluate robustness against clothing variations. The results of this experiment are presented in Table 5.
Table 2:
View-wise performance of the proposed LD2oDP + SP-VLAD method on the CASIA-B dataset in terms of accuracy, precision, recall and F1 score under NW condition
| View | Accuracy (%) | Precision (%) | Recall (%) | F1-score (%) |
|---|---|---|---|---|
| 0° | 98.20 | 98.10 | 97.97 | 97.72 |
| 18° | 95.54 | 95.03 | 95.97 | 94.89 |
| 36° | 87.05 | 86.22 | 87.10 | 84.73 |
| 54° | 87.44 | 85.95 | 87.10 | 84.52 |
| 72° | 92.57 | 93.41 | 93.15 | 91.69 |
| 90° | 93.07 | 93.65 | 93.94 | 92.60 |
| 108° | 94.20 | 94.35 | 94.76 | 93.36 |
| 126° | 94.14 | 94.17 | 94.72 | 93.50 |
| 144° | 88.74 | 89.05 | 89.11 | 86.96 |
| 162° | 95.05 | 94.62 | 95.16 | 93.82 |
| 180° | 98.20 | 96.91 | 97.98 | 97.15 |
Table 3A:
Comparison of recognition accuracy (%) at lower viewing angles on the CASIA-B dataset
| Method (Ref) | Year | Category | 0° | 18° | 36° | 54° | 72° |
|---|---|---|---|---|---|---|---|
| Genetic template segmentation [30] | 2017 | Handcrafted | 97.00 | 99.49 | 97.50 | 94.00 | 88.00 |
| Specialized CNN [31] | 2017 | Deep learning | 79.10 | 82.52 | 76.00 | 81.63 | 85.20 |
| Deterministic learning [32] | 2018 | Handcrafted | 97.81 | 98.80 | 98.05 | 95.00 | 92.56 |
| Deep learning framework [33] | 2024 | Deep learning | 96.20 | 98.70 | 97.70 | 97.10 | 85.30 |
| Frontal-view gait dynamics + deep transfer learning [25] | 2025 | Hybrid (handcrafted + deep learning) | 96.9 | - | - | - | - |
| Part-based Ensemble CNN [34] | 2025 | Deep learning | 88.30 | 94.60 | 97.30 | 94.90 | 90.80 |
| GaitSet-based [35] | 2025 | Deep learning | 89.8 | 96.40 | 97.70 | 96.30 | 91.40 |
| Deep learning fusion + MFO (EfficientNetB0 + MobileNetV2) [36] | 2025 | Deep learning | 95.70 | 91.90 | - | - | - |
| Proposed method (LD2oDP + SP-VLAD) | Handcrafted | 98.20 | 95.97 | 87.05 | 87.44 | 92.57 |
Table 3B:
Comparison of recognition accuracy (%) at higher viewing angles on the CASIA-B dataset
| Method (Ref) | Year | Category | 90° | 108° | 126° | 144° | 162° | 180° |
|---|---|---|---|---|---|---|---|---|
| Genetic template segmentation [30] | 2017 | Handcrafted | 90.50 | 89.50 | 94.50 | 92.00 | 91.28 | 93.94 |
| Specialized CNN [31] | 2017 | Deep learning | 84.46 | 82.77 | 79.26 | 84.70 | 86.40 | 82.00 |
| Deterministic learning [32] | 2018 | Handcrafted | 92.80 | 91.52 | 93.10 | 92.73 | 91.60 | 94.52 |
| Deep learning framework [33] | 2024 | Deep learning | 88.90 | 93.20 | 88.90 | 93.20 | 88.20 | 90.90 |
| Frontal-view gait dynamics + deep transfer learning [25] | 2025 | Hybrid (handcrafted + deep learning) | - | - | - | - | - | - |
| Part-based Ensemble CNN [34] | 2025 | Deep learning | 88.50 | 90.70 | 93.40 | 96.10 | 94.60 | 85.70 |
| GaitSet-based [35] | 2025 | Deep learning | 88.40 | 92.80 | 96.00 | 97.70 | 96.10 | 82.70 |
| Deep learning Fusion + MFO (EfficientNetB0 + MobileNetV2) [36] | 2025 | Deep learning | 82.70 | 85.30 | - | - | 91.70 | 98.90 |
| Proposed method (LD2oDP + SP-VLAD) | Handcrafted | 93.07 | 94.20 | 94.14 | 88.74 | 95.05 | 98.20 |
Table 4:
Experiments conducted on the CASIA-B gait database to evaluate robustness against variations in viewpoint and clothing
| View point | Training dataset | Test dataset | Size of training dataset | Size of test dataset | Proposed method (accuracy in %) |
|---|---|---|---|---|---|
| 0° (NM) | NM + CL | NM | 124 × 5 | 124 × 2 | 99.59 |
| 0° (CL) | NM + CL | CL | 124 × 5 | 124 × 1 | 96.75 |
| 18°(NM) | NM + CL | NM | 124 × 5 | 124 × 2 | 97.98 |
| 18°(CL) | NM + CL | CL | 124 × 5 | 124 × 1 | 90.32 |
| 36°(NM) | NM + CL | NM | 124 × 5 | 124 × 2 | 93.95 |
| 36°(CL) | NM + CL | CL | 124 × 5 | 124 × 1 | 87.10 |
| 54°(NM) | NM + CL | NM | 124 × 5 | 124 × 2 | 92.74 |
| 54°(CL) | NM + CL | CL | 124 × 5 | 124 × 1 | 82.11 |
| 72°(NM) | NM + CL | NM | 124 × 5 | 124 × 2 | 97.18 |
| 72°(CL) | NM + CL | CL | 124 × 5 | 124 × 1 | 95.97 |
| 90°(NM) | NM + CL | NM | 124 × 5 | 124 × 2 | 96.77 |
| 90°(CL) | NM + CL | CL | 124 × 5 | 124 × 1 | 95.97 |
| 108°(NM) | NM + CL | NM | 124 × 5 | 124 × 2 | 95.97 |
| 108°(CL) | NM + CL | CL | 124 × 5 | 124 × 1 | 91.94 |
| 126°(NM) | NM + CL | NM | 124 × 5 | 124 × 2 | 95.97 |
| 126°(CL) | NM + CL | CL | 124 × 5 | 124 × 1 | 92.68 |
| 144°(NM) | NM + CL | NM | 124 × 5 | 124 × 2 | 95.16 |
| 144°(CL) | NM + CL | CL | 124 × 5 | 124 × 1 | 95.92 |
| 162°(NM) | NM + CL | NM | 124 × 5 | 124 × 2 | 97.18 |
| 162°(CL) | NM + CL | CL | 124 × 5 | 124 × 1 | 83.99 |
| 180°(NM) | NM + CL | NM | 124 × 5 | 124 × 2 | 99.19 |
| 180°(CL) | NM + CL | CL | 124 × 5 | 124 × 1 | 96.77 |
| Avg (NM) | 96.51 | ||||
| Avg (CL) | 91.77 |
Table 5:
Experimental conducted on the CASIA-B gait dataset to evaluate robustness against viewpoint and carrying variations (e.g., walking with a bag)
| View point | Training dataset | Test dataset | Size of training dataset | Size of test dataset | Proposed method (accuracy in %) |
|---|---|---|---|---|---|
| 0° (NM) | NM + BG | NM | 124 × 5 | 124 × 2 | 99.19 |
| 0° (BG) | NM + BG | BG | 124 × 5 | 124 × 1 | 95.12 |
| 18°(NM) | NM + BG | NM | 124 × 5 | 124 × 2 | 97.98 |
| 18°(BG) | NM + BG | BG | 124 × 5 | 124 × 1 | 89.52 |
| 36°(NM) | NM + BG | NM | 124 × 5 | 124 × 2 | 94.76 |
| 36°(BG) | NM + BG | BG | 124 × 5 | 124 × 1 | 87.10 |
| 54°(NM) | NM + BG | NM | 124 × 5 | 124 × 2 | 93.95 |
| 54°(BG) | NM + BG | BG | 124 × 5 | 124 × 1 | 86.89 |
| 72°(NM) | NM + BG | NM | 124 × 5 | 124 × 2 | 95.97 |
| 72°(BG) | NM + BG | BG | 124 × 5 | 124 × 1 | 95.16 |
| 90°(NM) | NM + BG | NM | 124 × 5 | 124 × 2 | 97.18 |
| 90°(BG) | NM + BG | BG | 124 × 5 | 124 × 1 | 94.35 |
| 108°(NM) | NM + BG | NM | 124 × 5 | 124 × 2 | 95.56 |
| 108°(BG) | NM + BG | BG | 124 × 5 | 124 × 1 | 95.16 |
| 126°(NM) | NM + BG | NM | 124 × 5 | 124 × 2 | 95.56 |
| 126°(BG) | NM + BG | BG | 124 × 5 | 124 × 1 | 93.50 |
| 144°(NM) | NM + BG | NM | 124 × 5 | 124 × 2 | 95.16 |
| 144°(BG) | NM + BG | BG | 124 × 5 | 124 × 1 | 93.55 |
| 162°(NM) | NM + BG | NM | 124 × 5 | 124 × 2 | 97.58 |
| 162°(BG) | NM + BG | BG | 124 × 5 | 124 × 1 | 94.26 |
| 180°(NM) | NM + BG | NM | 124 × 5 | 124 × 2 | 98.79 |
| 180°(BG) | NM + BG | BG | 124 × 5 | 124 × 1 | 97.77 |
| Avg (NM) | 96.51 | ||||
| Avg (BG) | 92.94 |
b. Experimental result using CASIA-B dataset
Table 2 reports the view-wise performance of the proposed LD2oDP + SP-VLAD method on the CASIA-B dataset in terms of accuracy, precision, recall, and F1-score under the NW condition. The results demonstrate that the proposed framework maintains consistently high classification performance across all viewing angles. High precision values indicate a low false-positive rate, while strong recall scores confirm the method's ability to correctly identify subjects across varying viewpoints. The F1-score, which balances precision and recall, remains stable across most views, reflecting reliable and balanced classification performance even under challenging lateral viewpoints. Slight performance drops are observed at extreme side views, which is expected due to increased self-occlusion and reduced discriminative silhouette information. Overall, the consistent alignment between accuracy, precision, recall, and F1-score confirms the robustness and reliability of the proposed handcrafted framework for multi-view gait recognition.
Tables 3A and 3B present a comprehensive comparison of recognition accuracy across multiple viewing angles on the CASIA-B dataset, covering handcrafted, hybrid, and deep learning–based gait recognition methods published between 2017 and 2025. The comparison includes classical template-based handcrafted approaches as well as recent deep learning frameworks such as ensemble CNNs, GaitSet-based models, and deep feature fusion methods.
From the results, it is evident that earlier hand-crafted approaches, including genetic template segmentation and deterministic learning, achieve strong performance under frontal and near-frontal views. However, their recognition accuracy generally degrades as the viewing angle moves toward lateral or rear views. Recent deep learning–based methods demonstrate improved robustness across a wider range of viewpoints, nevertheless, this performance gain is often accompanied by increased computational complexity, reliance on large-scale annotated datasets, and higher training costs.
Despite being a purely handcrafted method, the proposed LD2oDP + SP-VLAD framework demonstrates highly competitive and consistent performance across all evaluated viewpoints. It achieves 98.20% accuracy at 0° and 98.20% at 180°, while maintaining stable recognition rates at challenging side views, such as 93.07% at 90° and 94.20% at 108°. In several viewpoints, the proposed approach matches or outperforms recent deep learning and hybrid methods. These results highlight that carefully designed local second-order directional descriptors combined with an effective spatial encoding strategy can achieve robust view-invariant gait recognition. The strong performance of the proposed handcrafted framework demonstrates its suitability for scenarios where computational resources are limited or large annotated training datasets are unavailable.
Table 4 further evaluates the robustness of the proposed method under clothing variations. The results indicate consistently strong performance across different viewpoints, regardless of the degree of clothing variation. When trained using both NW and clothing sequences, the proposed method achieves over 92% accuracy across all viewpoints for NW tests. Additionally, it maintains over 82% accuracy across all viewpoints for tests involving clothing variation, demonstrating its robustness to appearance changes.
Figure 14 presents a comparison between the proposed method and the approach reported in [1] on the CASIA-B gait database, considering variations in viewpoint and clothing. In [1], the same training and testing setup was used, with a training dataset of 124 × 4 sequences and the same testing data-set as ours for the clothing scenarios. The method in [1] achieved higher accuracy at the 72° viewpoint under clothing variation conditions. In contrast, the proposed method achieved higher accuracies at 72°, 90°, 144°, and 180° viewpoints under the same conditions, while a slight reduction was observed at the 54° viewpoint, where it attained 82.11% accuracy. Overall, these results indicate that the proposed approach demonstrates improved robustness across most viewing angles under clothing variations, particularly at side and back views, which are generally more challenging for gait recognition systems.
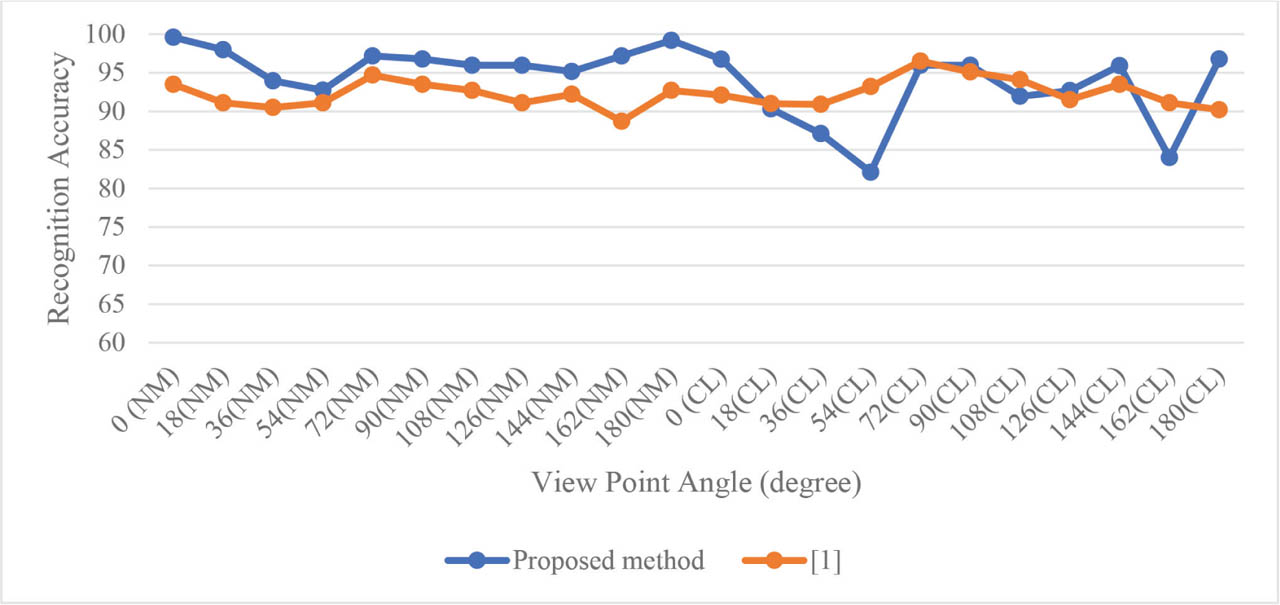
Figure 14:
Comparison of the proposed method with [1] on the CASIA-B gait database under viewpoint and clothing variations.
From Table 5, it can be observed that strong performance is maintained across various viewpoints, irrespective of the extent of carrying variations. The proposed method achieves over 93% accuracy across all viewpoints for NW tests when both NW and carrying scenarios are used for training, and maintains over 86% accuracy across all viewpoints for tests involving carrying variations under the same training setup. The proposed method obtains an average accuracy of 92.94% for the carrying-bag condition, indicating that it performs well across different viewpoints and carrying conditions.
c. CASIA-C dataset
The CASIA-C infrared gait dataset contains gait recordings of 153 individuals captured at night. Everyone's walking style is captured under four gait conditions: NW, fast walking (FW), slow walking (SW), and walking while carrying a bag (BW). Each subject has four NW sequences, two FW sequences, two SW sequences, and two BW sequences. The first 62 subjects are used as the training set, and the remaining subjects are used as the testing set. For each subject, NW sequences serve as the gallery set, while the remaining sequences are used as the probe set, resulting in a cross-condition gait recognition setting. Some examples of GEI image of the CASIA-C dataset are shown in Figure 15.
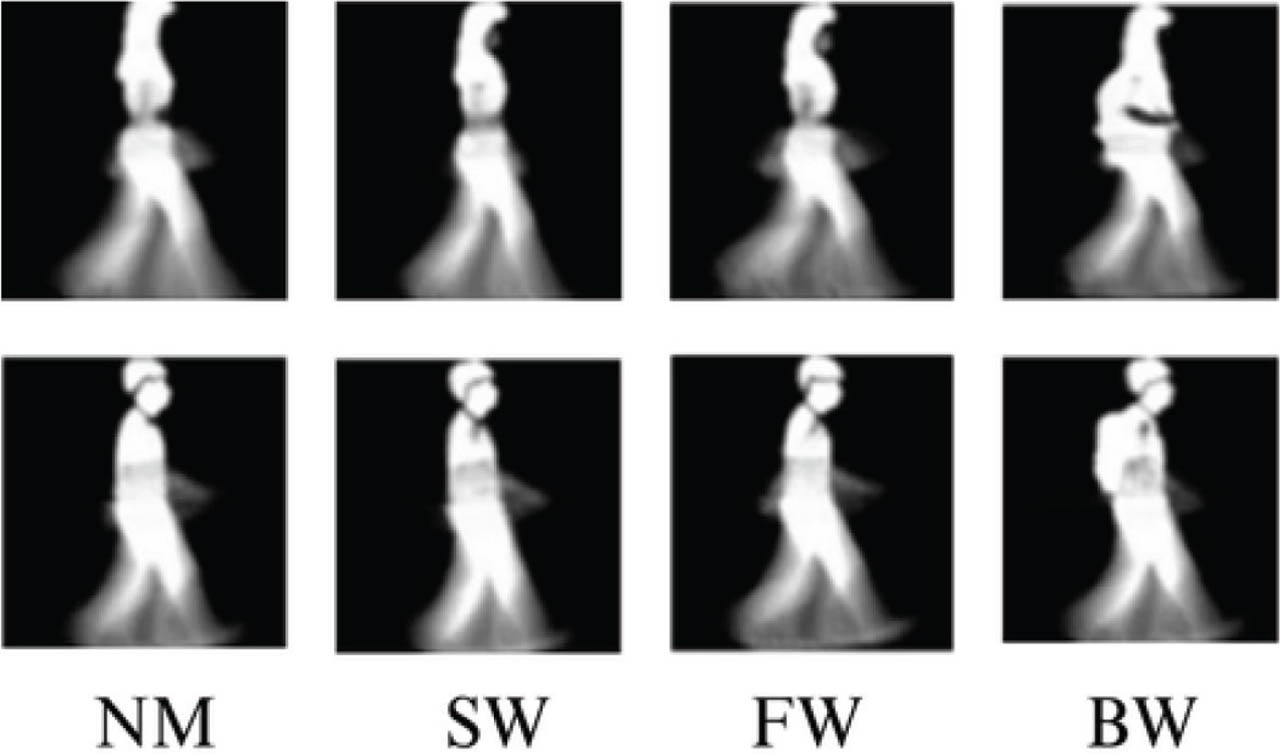
Figure 15:
Sample GEI image examples from the CASIA-C dataset. FW, fast walking; GEI, gait energy image; SW, slow walking.
d. Experimental result using CASIA-C dataset
Table 6 presents the cross-condition performance of the proposed method on the CASIA-C dataset. The reported metrics accuracy, precision, recall, and F1-score, are macro-averaged across all test subjects. The proposed method achieves the highest performance under FW, with 81.32% accuracy, showing that it effectively captures gait dynamics when subjects walk at a faster pace. The performance under SW is slightly lower (76.37%), indicating robustness to variations in walking speed. A significant performance drop is observed under BW (36.26%), reflecting the challenge posed by occlusion and appearance changes when subjects carry a bag. Precision, recall, and F1-score follow the same trend, demonstrating that the method maintains a balanced recognition ability across FW and SW, but struggles in BW conditions.
Table 6:
Cross-condition performance of the proposed method on the CASIA-C dataset under different walking conditions
| Condition | Accuracy (%) | Precision (%) | Recall (%) | F1-score (%) |
|---|---|---|---|---|
| FW | 81.32 | 80.08 | 81.32 | 78.50 |
| SW | 76.37 | 76.01 | 76.37 | 73.31 |
| BW | 36.26 | 35.11 | 36.26 | 32.17 |
The CASIA-C dataset was employed to further evaluate the robustness of the proposed LD2oDP + SP-VLAD framework under cross-condition gait recognition. Table 7 reports the macro-averaged accuracy, precision, recall, and F1-score obtained when NW sequences are used as the gallery and FW, SW, and bag-carrying (BW) sequences are used as probe conditions. As shown in Table 7, the proposed method achieved an accuracy of 81.32% when trained on 62 subjects, demonstrating superior performance under FW condition. Compared with [37], the proposed method increases the accuracy by about 10% under FW conditions and by about 16% on SW condition. It outperforms [37,38,39] methods, which can be understood by its ability for decoding thermal (infrared) images efficiently, particularly under normal and FW conditions, compared to SW and bag-carrying scenarios. Overall, these results indicate that the proposed handcrafted LD2oDP + SP-VLAD representation is particularly effective under fast and SW conditions, while bag-carrying remains a challenging scenario due to occlusion-induced appearance changes.
Table 7:
Comparison of cross-condition gait recognition accuracy (%) on the CASIA-C dataset
| Models (Ref) | Year | Category | FW (%) | SW (%) | BW (%) |
|---|---|---|---|---|---|
| Local graphical skeleton descriptor [38] | 2021 | Hybrid (handcrafted + deep learning) | 63.6 | 60.0 | 42.3 |
| Gait optical flow network [39] | 2023 | Deep learning | 69.3 | 58.2 | 43.5 |
| GaitSTAR [37] | 2024 | Deep learning | 71.5 | 59.1 | 44.6 |
| Proposed method (LD2oDP + SP-VLAD) | Handcrafted | 81.32 | 76.37 | 36.26 |
e. Comparative analysis of LBP, LVQP, and the proposed method
Figures 5–7 display the results of all three descriptors (LBP, LVQP, and the Proposed Method) on a typical gait GEI respectively. These figures shows that the pixel intensities differ for the proposed descriptors, LBP, and LVQP. Figures 16 and 17 show the classification accuracy of each of the three descriptors for the CASIA-B gait database (for 0°, 90°, 180° views) and the CASIA-C gait database under NW, respectively. The proposed method demonstrated attractive results and achieved superior recognition accuracy in all cases, as can be seen in Figures 16 and 17. According to the experimental data, the proposed descriptors outperform both LBP and LVQP descriptors for gait recognition.
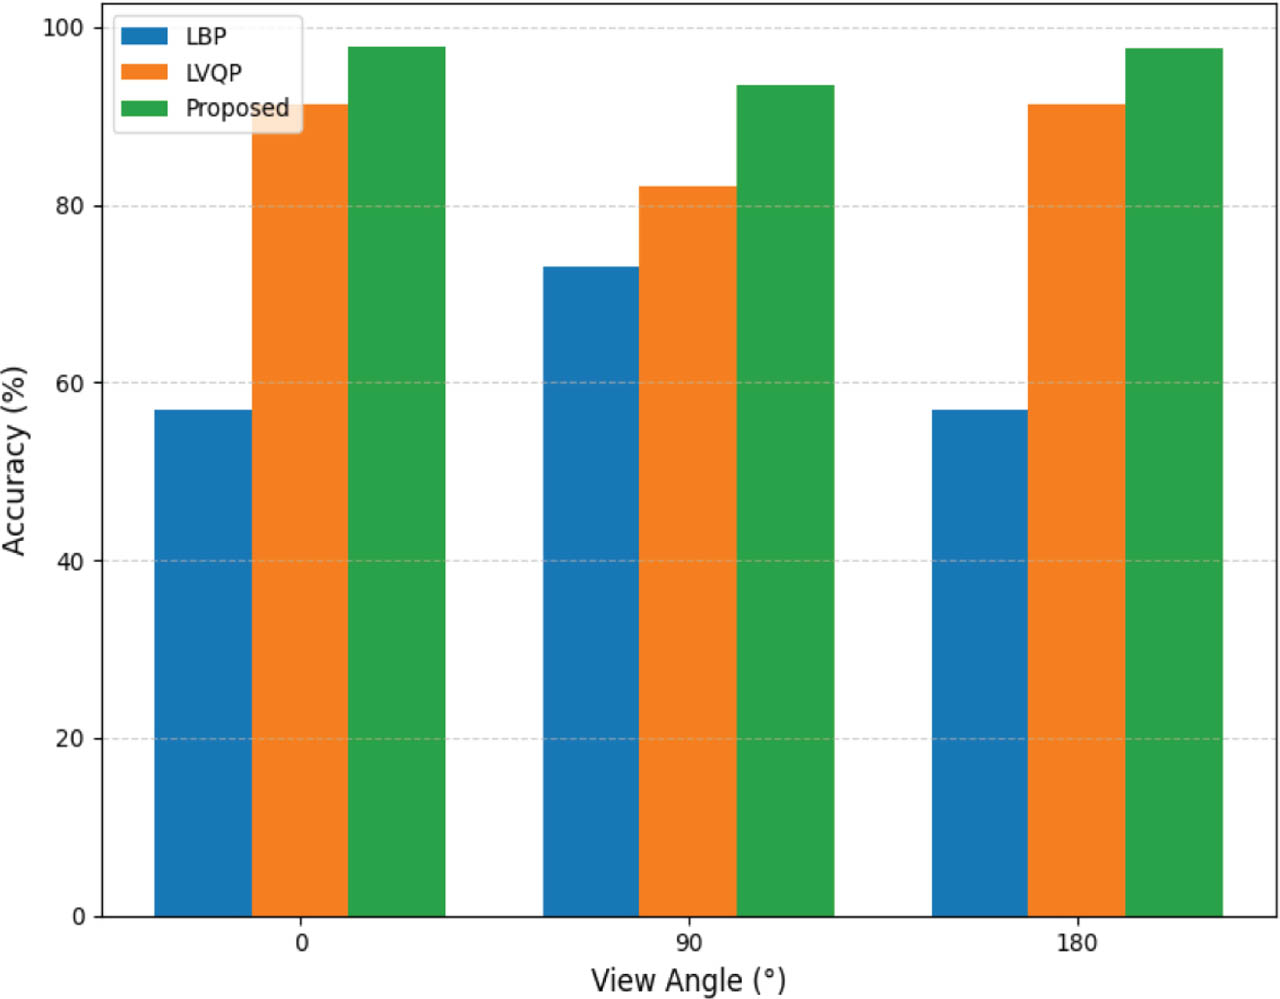
Figure 16:
Performance analysis of different feature descriptors on the CASIA-B dataset at 0°, 90°, and 180° view angles. LBP, local binary pattern; LVQP, local vector quantization pattern.
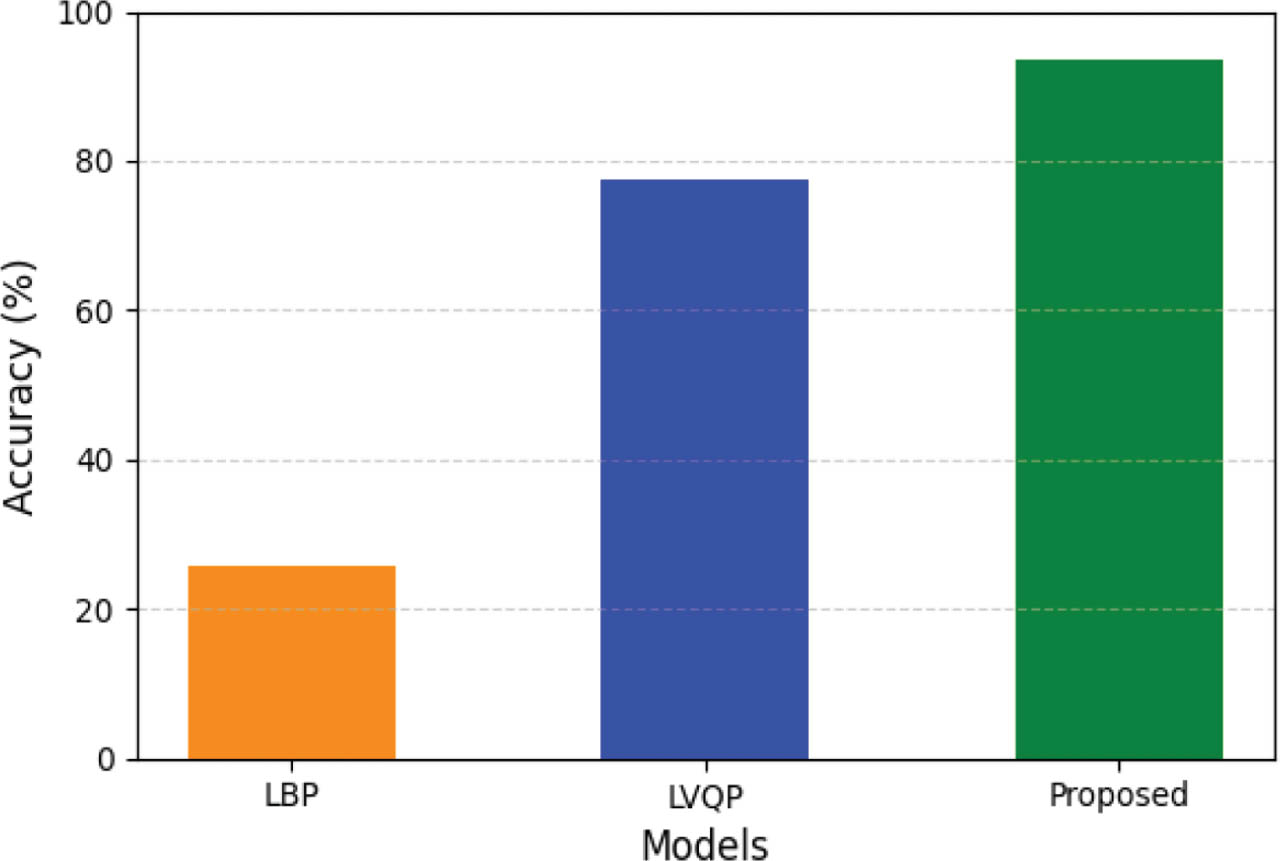
Figure 17:
Performance evaluation of various feature descriptors on the CASIA-C dataset under NW condition. NW, normal walking.
f. Ablation study
The ablation study evaluates the impact of code-book size, stride, and SP levels on cross-view gait recognition performance on the CASIA-B dataset and cross-condition gait recognition performance on the CASIA-C dataset using the LD2oDP + SP-VLAD framework. Tables 8 and 9 report the recognition accuracy (%) on the CASIA-B and CASIA-C datasets, respectively, under different configurations.
Table 8:
Ablation experiments on LD2oDP + SP-VLAD with CASIA-B dataset
| Method | Codebook size | Stride | SP-levels | 0° (%) | 90° (%) | 180° (%) |
|---|---|---|---|---|---|---|
| LD2oDP + SP-VLAD | 64 | 1 | [0, 1, 2] | 98.20 | 93.07 | 98.20 |
| LD2oDP + SP-VLAD | 64 | 2 | [0, 1, 2] | 96.85 | 85.40 | 97.30 |
| LD2oDP + SP-VLAD | 64 | 1 | [0] | 80.63 | 66.29 | 77.93 |
| LD2oDP + SP-VLAD | 64 | 2 | [0] | 56.76 | 38.61 | 57.66 |
| LD2oDP + SP-VLAD | 96 | 1 | [0, 1, 2] | 98.30 | 92.18 | 98.65 |
| LD2oDP + SP-VLAD | 96 | 2 | [0, 1, 2] | 98.20 | 87.71 | 95.95 |
Table 9:
Ablation experiments on LD2oDP + SP-VLAD with CASIA-C dataset
| Representation | Codebook size | Stride | SP-levels | FW (%) | SW (%) | BW (%) |
|---|---|---|---|---|---|---|
| LD2oDP + SP-VLAD | 64 | 1 | [0, 1, 2] | 81.32 | 76.37 | 36.26 |
| LD2oDP + SP-VLAD | 64 | 2 | [0, 1, 2] | 58.24 | 52.75 | 27.47 |
| LD2oDP + SP-VLAD | 64 | 1 | [0] | 32.97 | 37.91 | 17.03 |
| LD2oDP + SP-VLAD | 64 | 2 | [0] | 16.48 | 15.38 | 10.44 |
| LD2oDP + SP-VLAD | 96 | 1 | [0, 1, 2] | 81.32 | 76.37 | 36.26 |
| LD2oDP + SP-VLAD | 96 | 2 | [0, 1, 2] | 58.24 | 52.75 | 27.47 |
The configuration with a codebook size of 64, stride 1, and three SP levels [0, 1, 2] is selected as the baseline, as it consistently achieves the best balance between recognition accuracy and computational efficiency. A stride of 1 enables dense pixel-wise sampling, where LD2oDP features are extracted from every adjacent pixel location. This allows the descriptor to capture fine-grained second-order directional variations in gait silhouettes. In contrast, a stride of two performs sparser sampling, skipping alternate pixels, which leads to loss of subtle local motion and edge information, resulting in reduced recognition accuracy. A closer analysis reveals that the impact of stride selection is view and condition dependent. On the CASIA-B dataset, increasing the stride from 1 to 2 results in only a marginal performance drop (approx. 1%–2%) for frontal (0°) and back (180°) views, while a more noticeable degradation is observed for the side-view (90°) condition. This is because side-view gait sequences exhibit stronger limb articulation and continuous silhouette deformation, particularly in the leg and arm regions. Dense sampling (stride = 1) is therefore crucial to preserve subtle second-order directional variations along the silhouette contours. Sparser sampling may skip informative pixels, reducing discriminability in the side-view scenario. On the CASIA-C dataset, which includes infrared imagery and covariate variations such as walking speed and carrying conditions, the performance drop with stride 2 is more pronounced across all conditions. This indicates that dense LD2oDP sampling is especially important for preserving fine local motion cues in low-texture infrared silhouettes, where discriminative information is already limited.
The effect of SP modelling is also significant, using a single spatial level [0] causes a notable drop in accuracy, while multi-level spatial encoding ([0, 1, 2]) progressively improves performance by capturing both global gait structure and localized motion cues. Experiments with a larger codebook size of 96 do not yield consistent performance improvements across datasets or viewing conditions. On the CASIA-B dataset, minor gains are observed for front and back views. However, side-view performance often degrades, indicating that an overly fine partitioning of the feature space may fragment structurally similar gait patterns. On the CASIA-C infrared dataset, increasing the codebook size provides no measurable benefit, as the lower texture diversity of thermal silhouettes limits the effective utilization of additional visual words. Moreover, larger codebooks significantly increase feature dimensionality and computational cost without proportional accuracy gains.
The result from the Tables 8 and 9 demonstrate that the 64-codebook, stride-1, multi-level SP configuration provides a favourable trade-off between discriminative power, model compactness, and scalability, consistently yielding high gait recognition accuracy across both datasets.
V. Conclusion
In this paper, we propose a novel LD2oDP + SP-VLAD gait representation that extracts discriminative local features from gait silhouettes and encodes them into a robust global descriptor. Experiments on the CASIA-B and CASIA-C datasets demonstrate that the framework achieves high performance under both cross-view and cross-condition scenarios, effectively handling speed variations, carrying conditions, and partial occlusions. Extensive experimental evaluation demonstrates that the proposed method outperforms traditional handcrafted descriptors such as LBP and LVQP under varying viewpoints conditions. The strong performance across different scenarios validates the effectiveness of the proposed contributions and highlights their suitability for real-world applications such as security surveillance, access control, and forensic person identification, particularly in environments where large annotated datasets required for deep learning approaches are unavailable. Ablation studies show that using stride 1, multi-level SP [0, 1, 2], and codebook size 64 provides the best trade-off between accuracy and computational efficiency, highlighting the contributions of dense sampling, multi-scale spatial encoding, and compact feature representation. Despite its strong performance, the proposed approach has certain limitations. While robustness to speed and carrying variations is validated through cross-condition evaluation on the CASIA-C dataset, the current framework does not explicitly model temporal dynamics within gait sequences. Furthermore, cross-view robustness is achieved implicitly through discriminative feature encoding rather than via a dedicated cross-view learning or view-normalization mechanism. In addition, computational efficiency can be further optimized for large-scale or real-time deployment. Future work will focus on temporal modelling, attention mechanisms, and cross-view learning to further improve recognition and enable real-time deployment in practical applications.
Abbreviations
- AEI
Active Energy Image
- BG
Walking with a bag (bag-carrying condition for CASIA-B Dataset)
- CASIA-A
Chinese Academy of Sciences Institute of Automation Dataset A
- CASIA-B
Chinese Academy of Sciences Institute of Automation Dataset B
- CASIA-C
Chinese Academy of Sciences Institute of Automation Dataset C
- CL
Walking with a coat (coat-wearing condition for CASIA-B Dataset)
- CNNs
Convolutional Neural Networks
- GPU
Graphics Processing Unit
- HOF
Histogram of Optical Flow
- IIoT
Industrial Internet of Things
- ISMAEI
Improved-Sobel Masking Based Active Energy Image
- KTH
Royal Institute of Technology Human Action Dataset
- LGBM
Light Gradient Boosting Machine
- MFO
Moth Flame Optimization
- MoSURF
Modified Speeded-Up Robust Features
- NM
Normal Walking
- SP-VLAD
Spatial Pyramid-Vector of Locally Aggregated Descriptors