
Table 1:
Analogy of the traditional system with DRL principles
| DRL component | Traditional control equivalent | Description |
|---|---|---|
| Agent | Controller | Decides the actions to control the system. |
| Environment | Plant/process | The system is being controlled. |
| State | System measurements | Information about the system’s current status. |
| Action | Control input | Adjustments made to influence the process. |
| Reward | Error feedback | Guides the agent to improve performance. |
| Policy | Control law | Strategy linking states to optimal actions. |
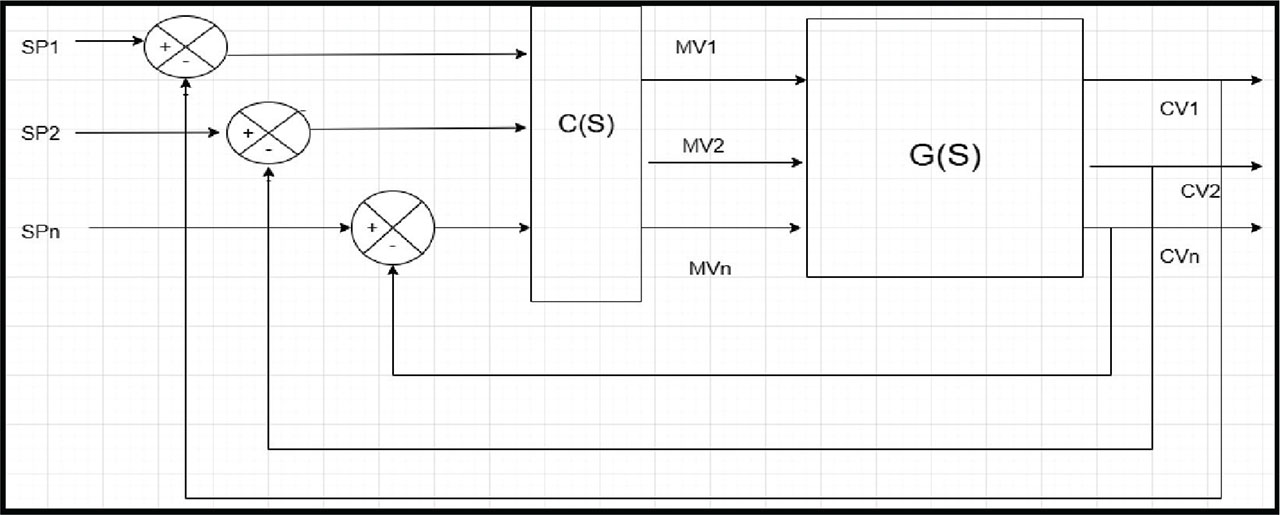
Figure 1:
Overall structure of the MIMO control system.
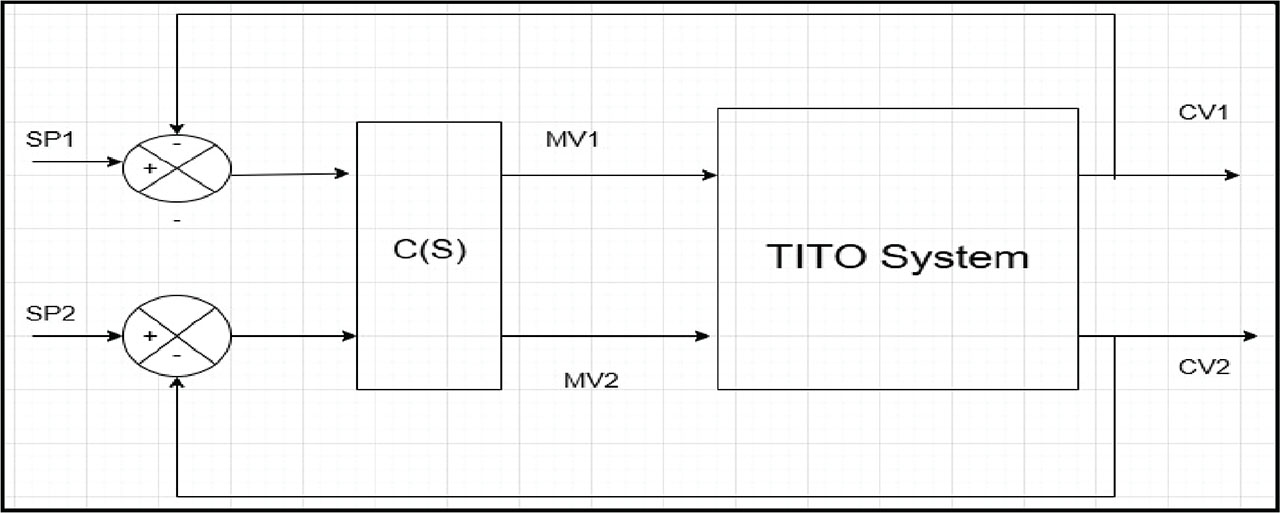
Figure 2:
TITO system with controller (TITO). TITO, two input–two output.
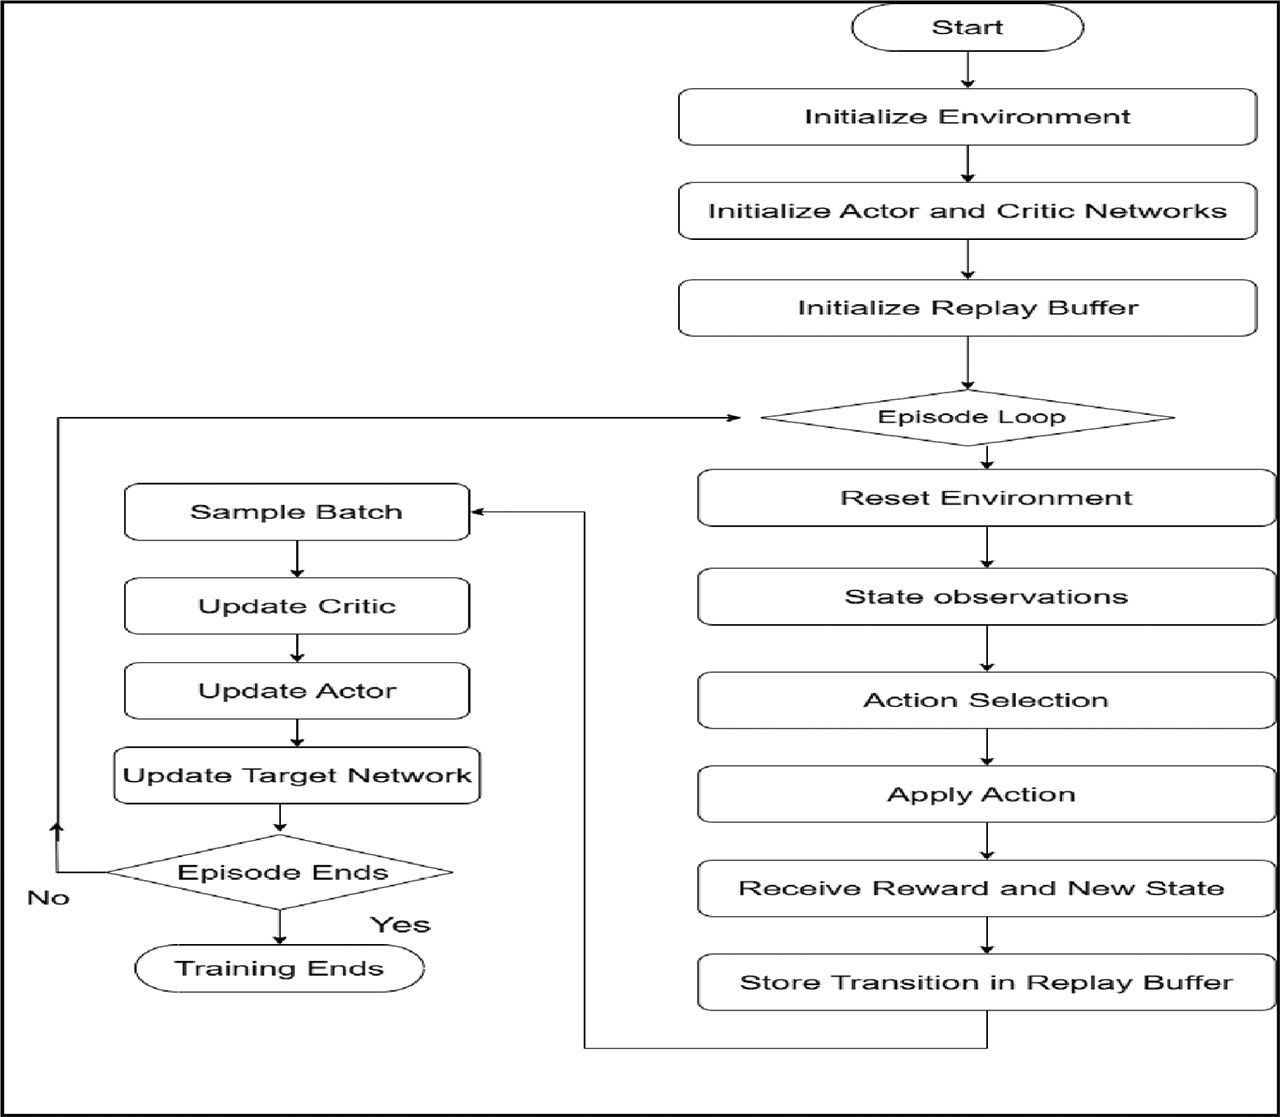
Figure 3:
Simple flow chart of TITO control system using DDPG. DDPG, deep deterministic policy gradient; TITO, two input–two output.
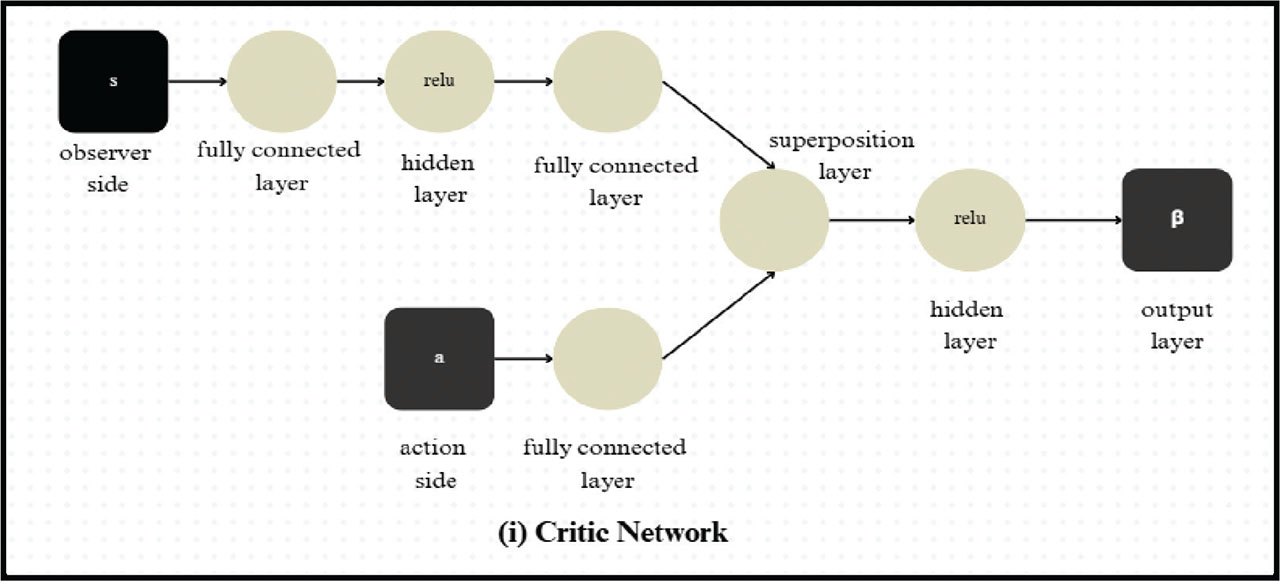
Figure 4:
Critic Network design for DDPG for TITO system. DDPG, deep deterministic policy gradient; TITO, two input–two output.
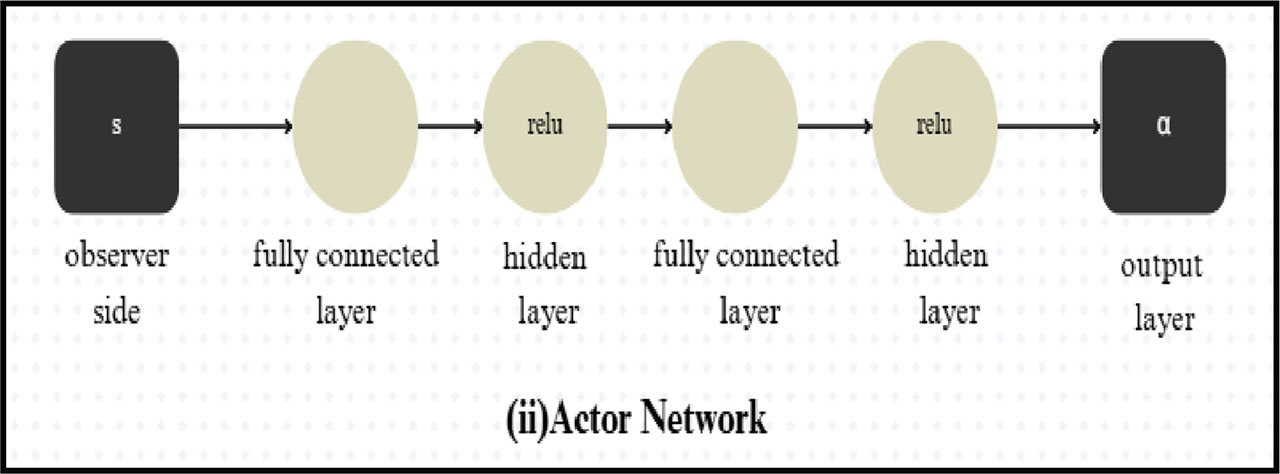
Figure 5:
Actor network design for DDPG for TITO system. DDPG, deep deterministic policy gradient; TITO, two input–two output.
Table 2:
Parameters for configuration of DDPG agent
| Parameter | Description | Value |
|---|---|---|
| Discount factor (γ) | Future reward discounting | 0.99 |
| Target smooth factor (τ) | Target network update rate | 0.001 |
| Actor learning rate | Learning rate for actor updates | 0.0001 |
| Critic learning rate | Learning rate for critic updates | 0.001 |
| Mini-batch size | Sample size for experience replay | 64 |
| Experience buffer length | Total memory for experience replay | 1,000,000 |
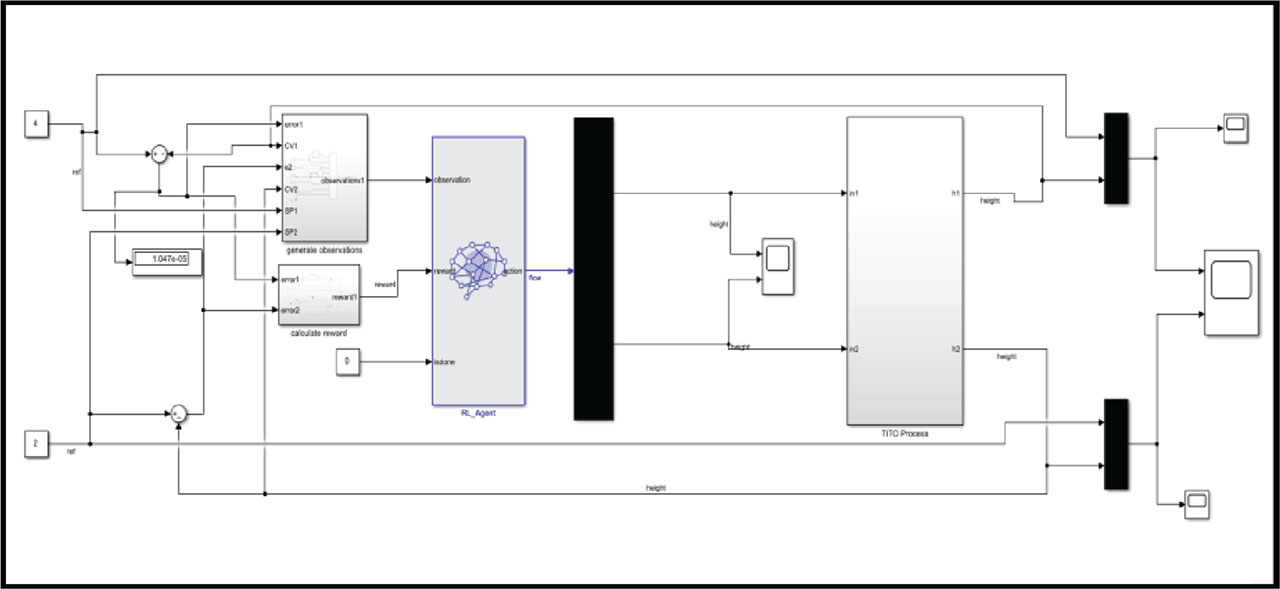
Figure 6:
Simulink model for TITO system. TITO, two input–two output.
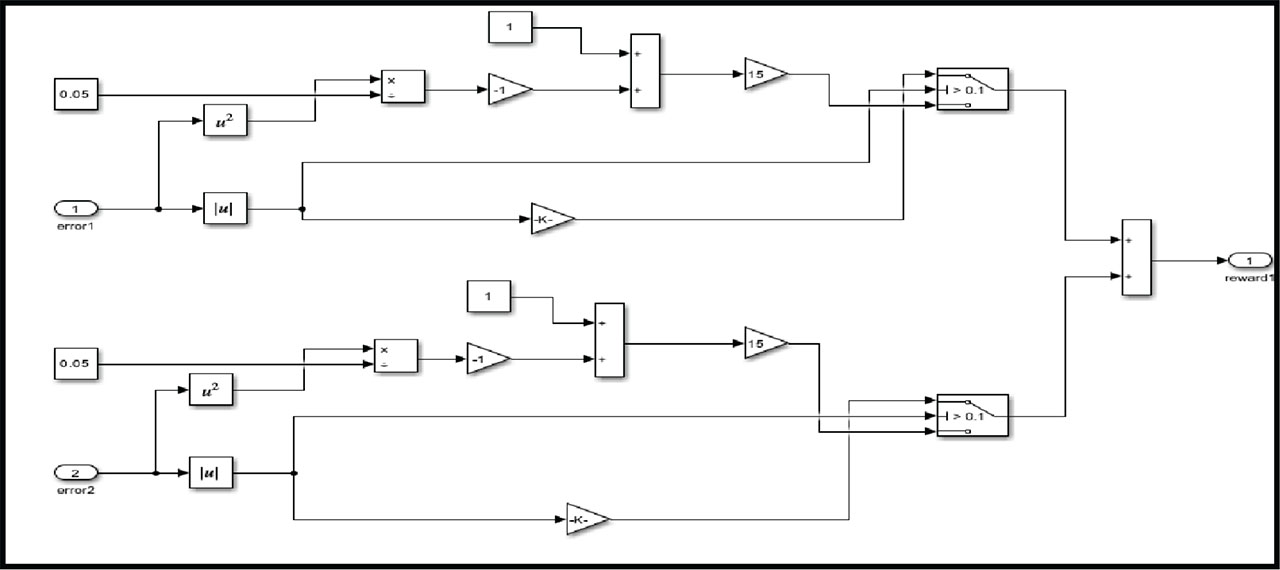
Figure 7:
Reward function representation using DDPG for TITO system. DDPG, deep deterministic policy gradient; TITO, two input–two output.
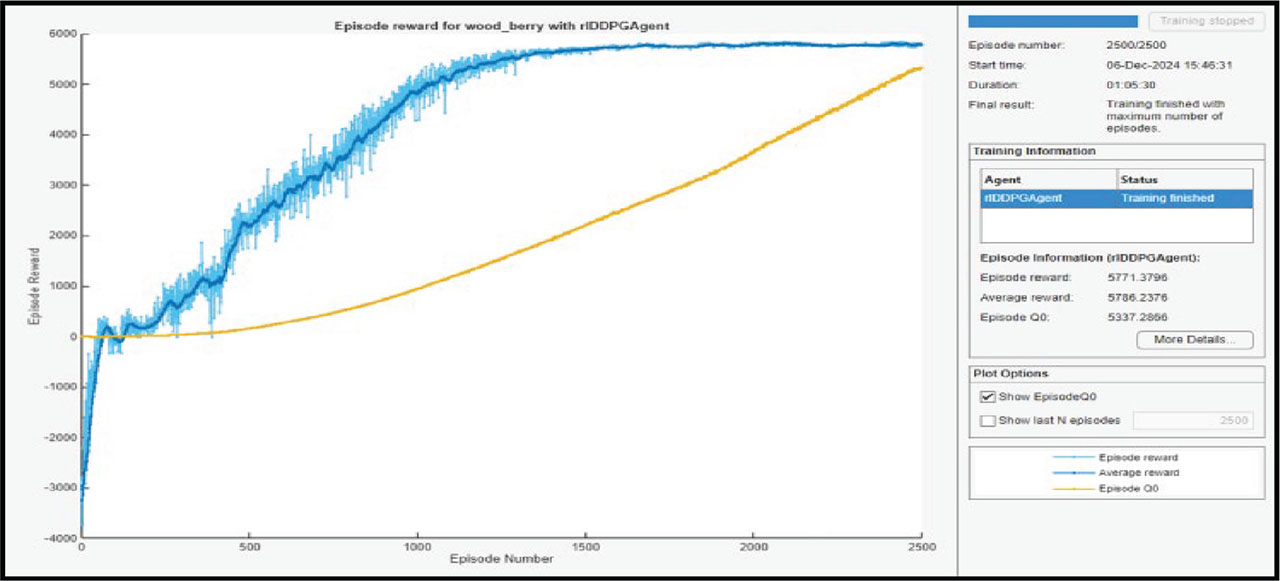
Figure 8:
Training performance of the DDPG agent for TITO for set point tracking. DDPG, deep deterministic policy gradient; TITO, two input–two output.
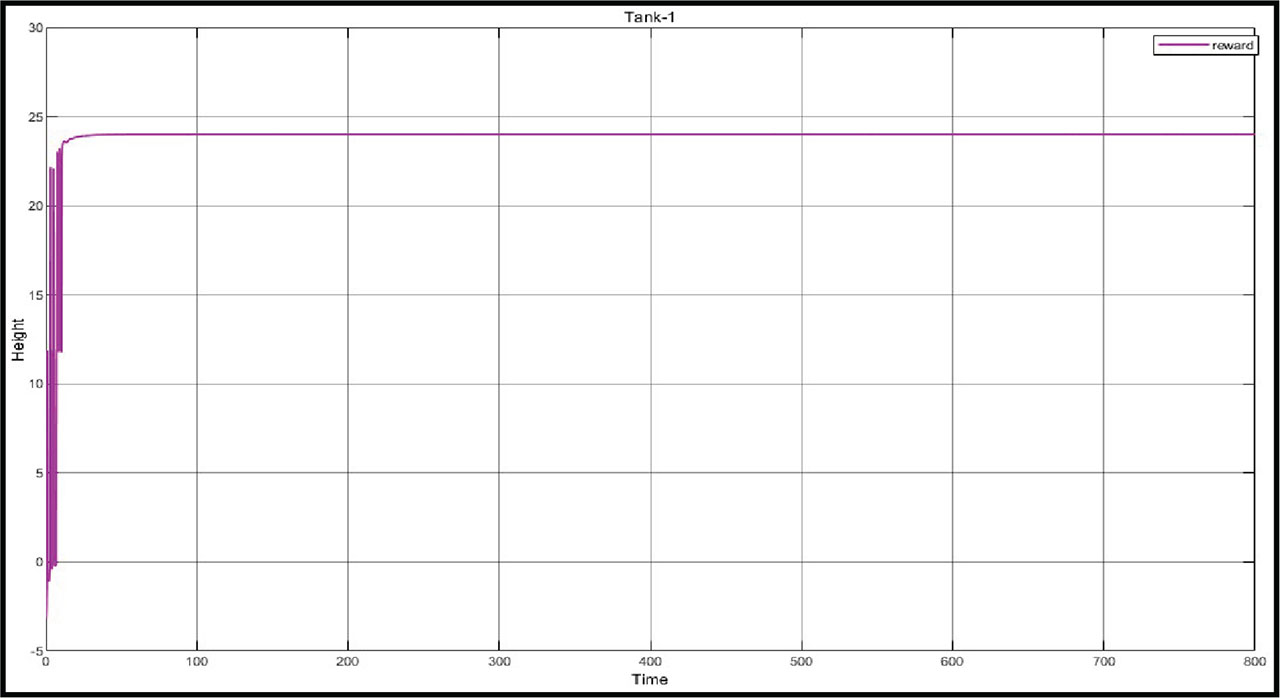
Figure 9:
Reward function progression of the DDPG agent for TITO system for set point tracking. DDPG, deep deterministic policy gradient; TITO, two input–two output.
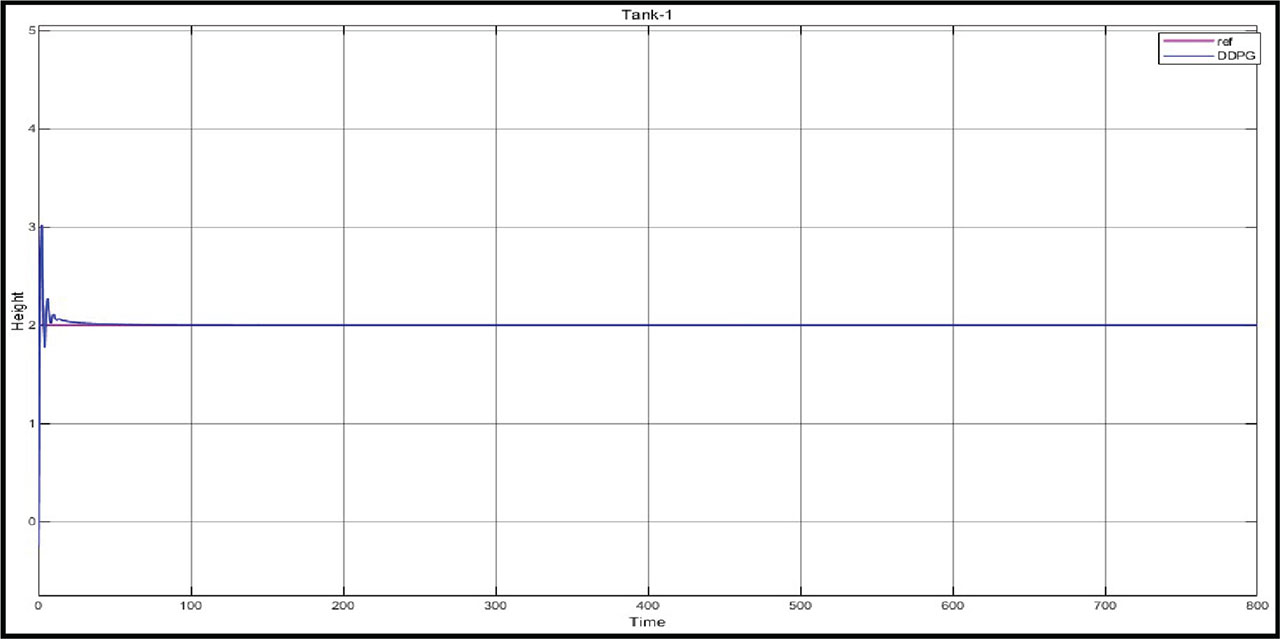
Figure 10:
Simulation of transfer function on Loop 1.
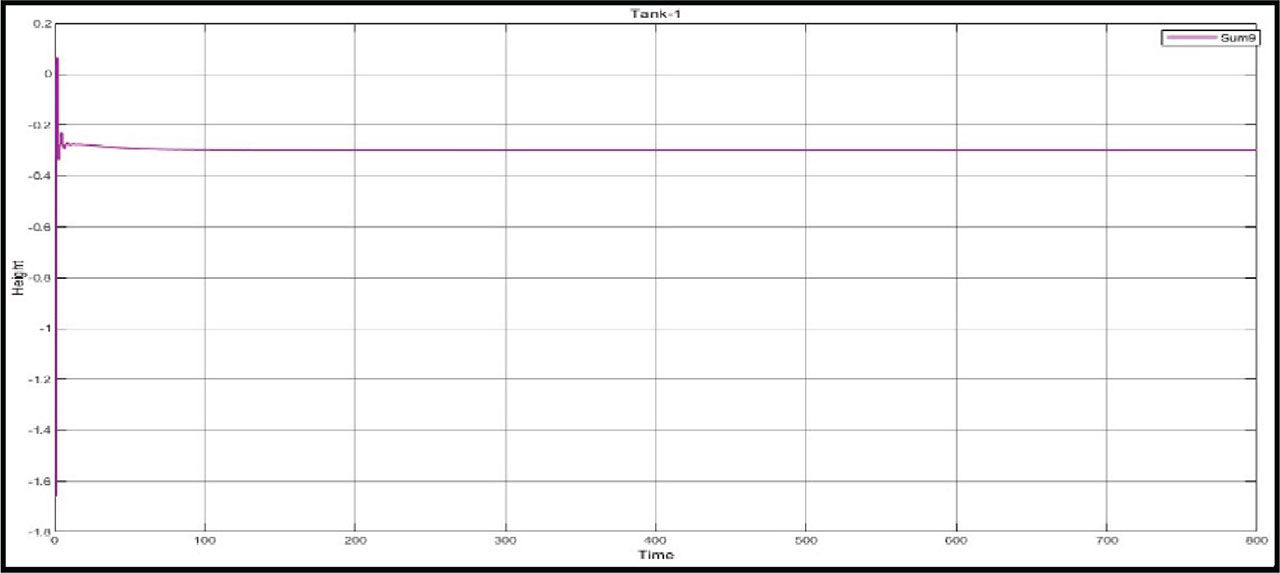
Figure 11:
MV values for Loop 1. MV, manipulated variable.
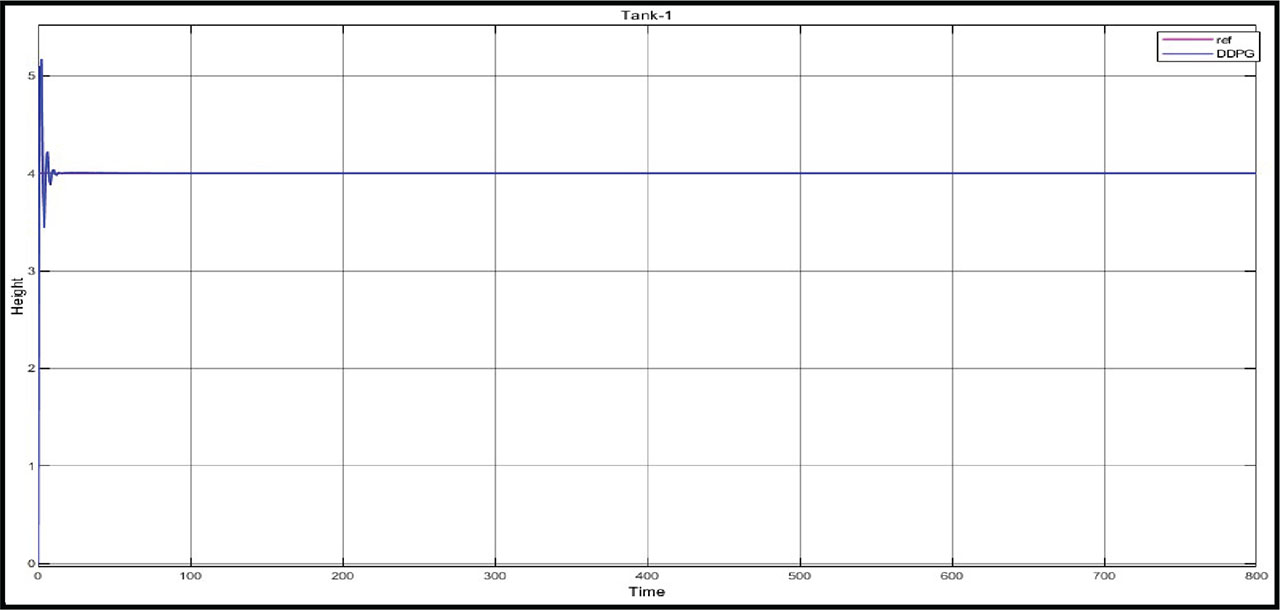
Figure 12:
Simulation of transfer function on Loop 2.
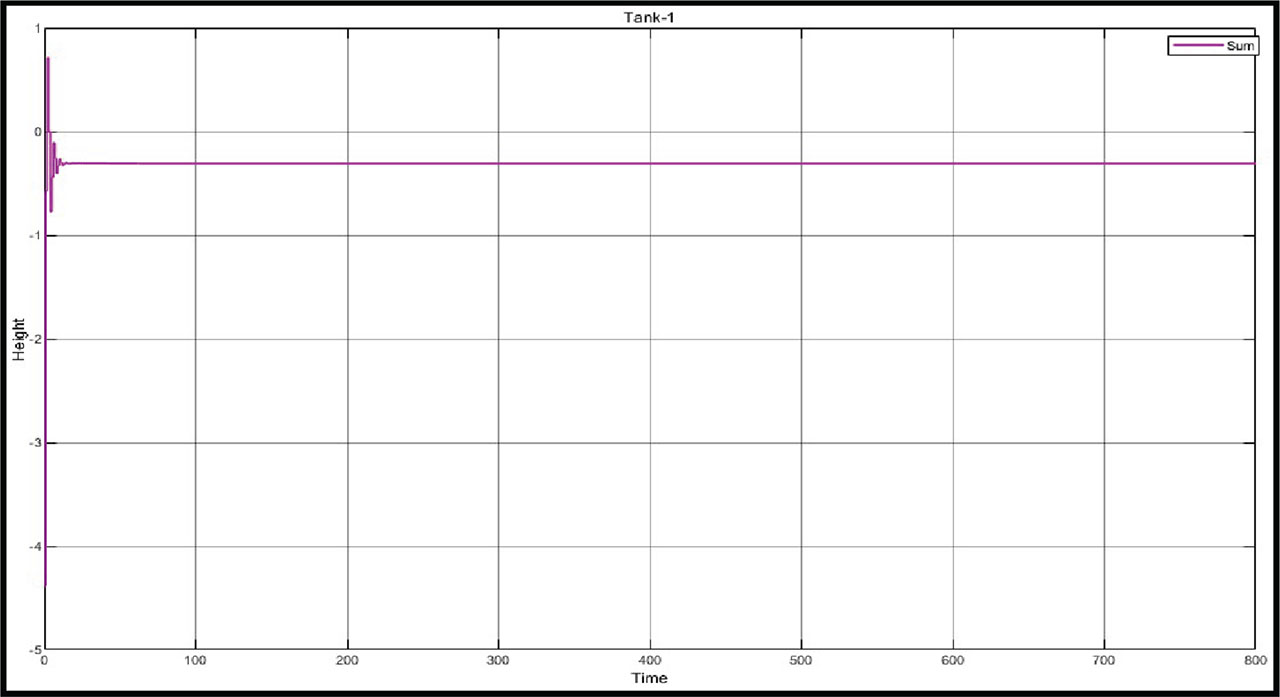
Figure 13:
MV values for Loop 2.
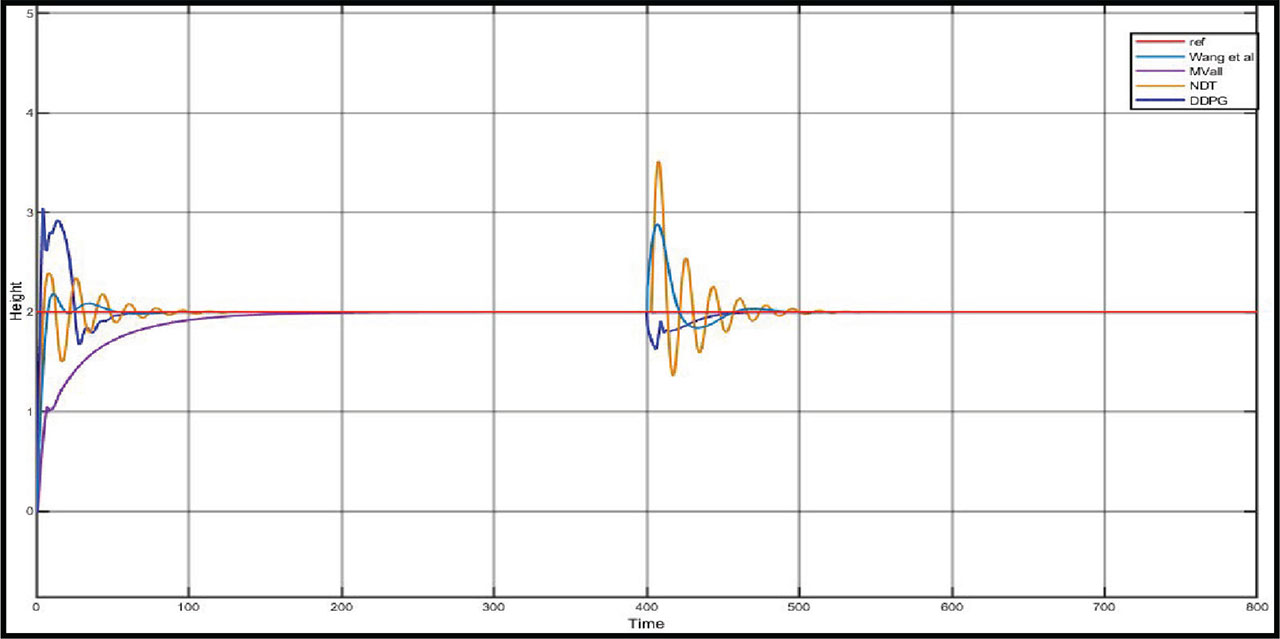
Figure 14:
Comparison of proposed method on Loop 1 with traditional methods. DDPG, deep deterministic policy gradient.
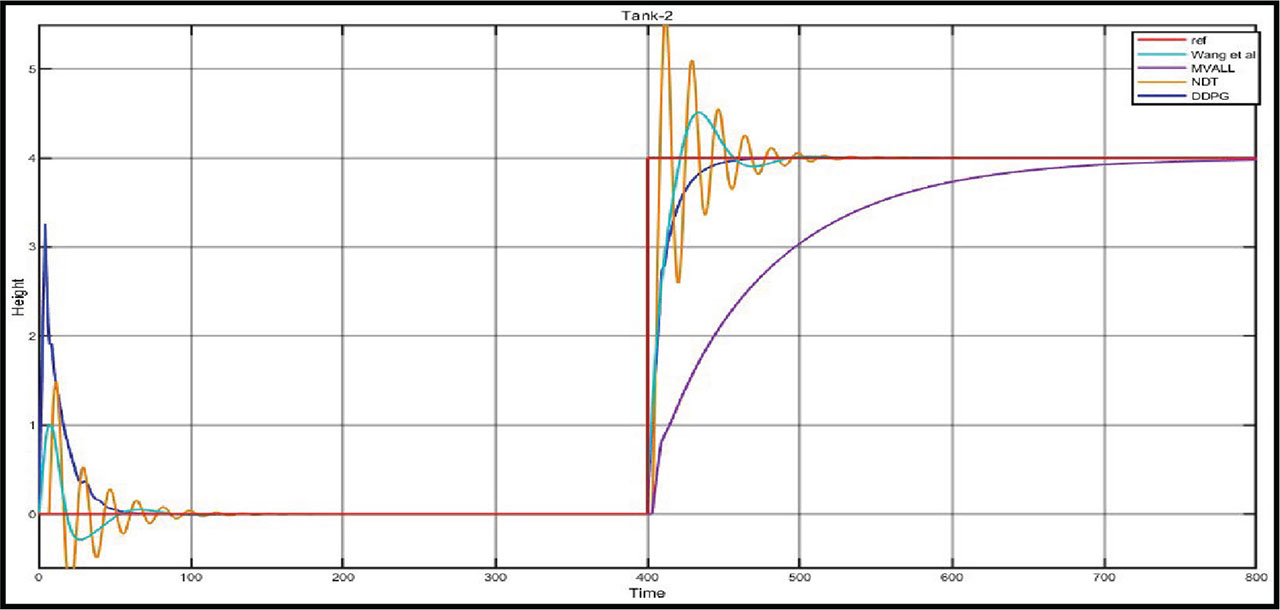
Figure 15:
Comparison of proposed methods on Loop 2 with traditional methods. DDPG, deep deterministic policy gradient.
Table 3:
Performance indices of Loop 1
| Method | ISE | IAE | ITSE | ITAE | Overshoot (%) | Settling time | Steady-state error |
|---|---|---|---|---|---|---|---|
| DDPG | 18.31 | 29.92 | 722.9 | 3325 | 35 | 48 | 0 |
| NDT [PI] | 26.82 | 39.9 | 6631 | 1.032e + 04 | 25 | 100 | 0 |
| Mvall [PI] | 34.61 | 47.25 | 488.3 | 1880 | 0 | 150 | 0 |
| Wang et al [PID] | 16.26 | 24.82 | 3206 | 6517 | 20 | 53 | 0 |
Table 4:
Performance indices of Loop 2
| Method | ISE | IAE | ITSE | ITAE | Overshoot (%) | Settling time | Steady-state error |
|---|---|---|---|---|---|---|---|
| DDPG | 137.7 | 79.13 | 3.217e + 04 | 1.707e + 04 | 0 | 42 | 0 |
| NDT[PI] | 122.1 | 82.69 | 4.434e + 04 | 2.515e + 04 | 60 | 110 | 0 |
| Mvall [PI] | 510.3 | 275.3 | 2.228e + 05 | 1.305e + 04 | 0 | 380 | 0 |
| Wang et al [PID] | 81.82 | 61.27 | 2.947e + 04 | 1.856e + 04 | 30 | 85 | 0 |
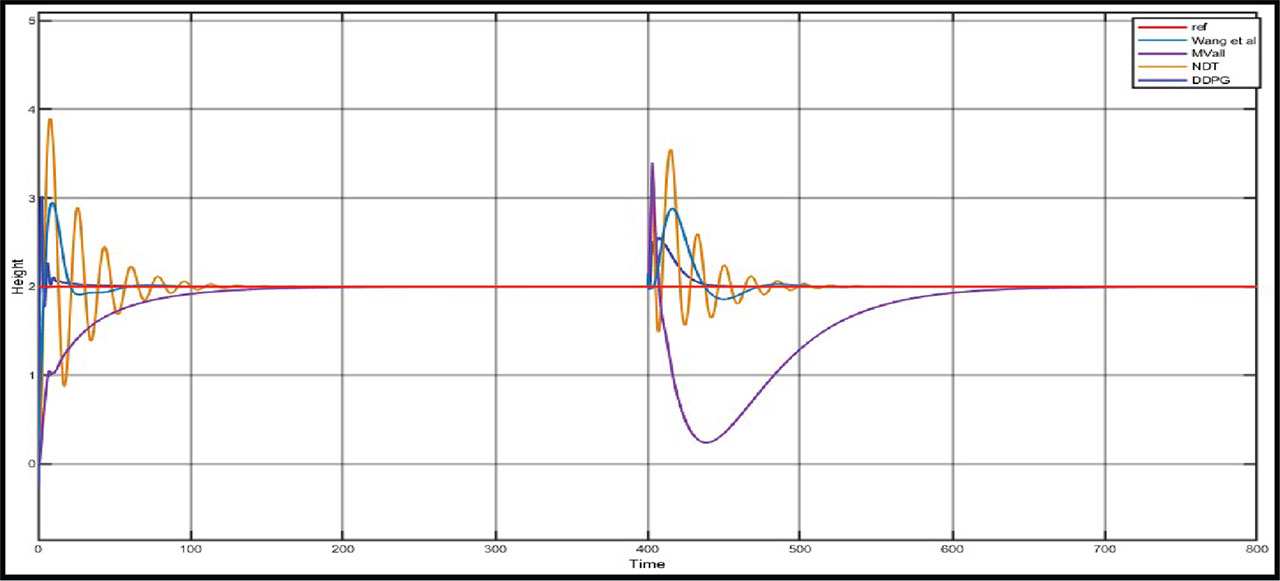
Figure 16:
Response to disturbance on Loop 1. DDPG, deep deterministic policy gradient.
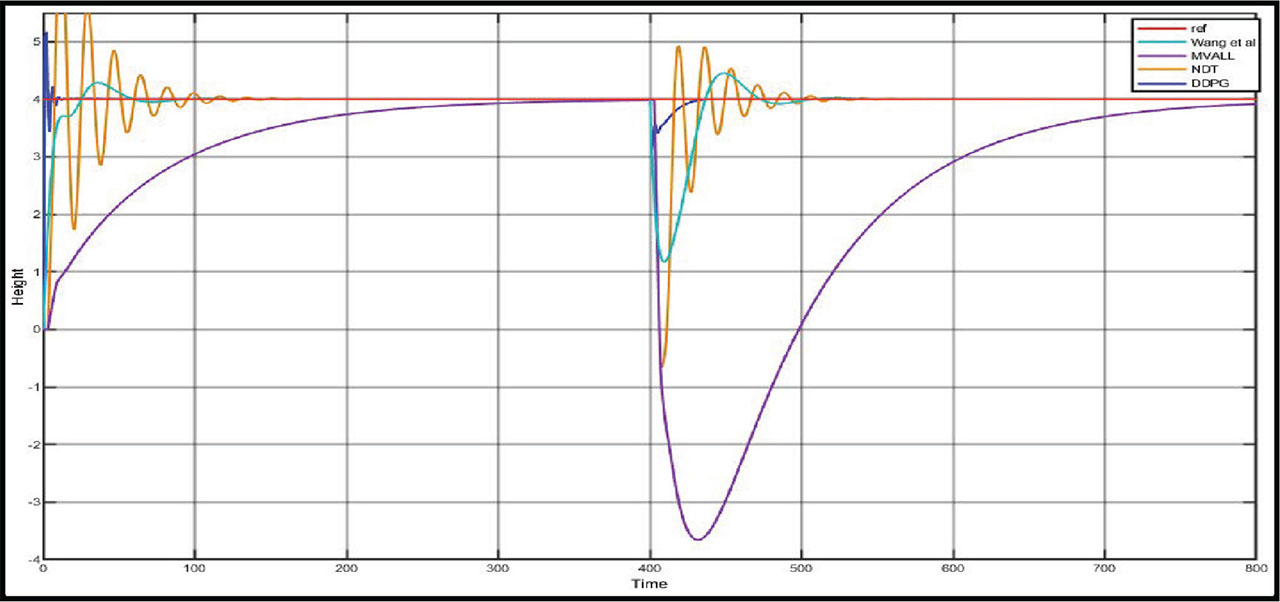
Figure 17:
Response to disturbance on Loop 2. DDPG, deep deterministic policy gradient.