
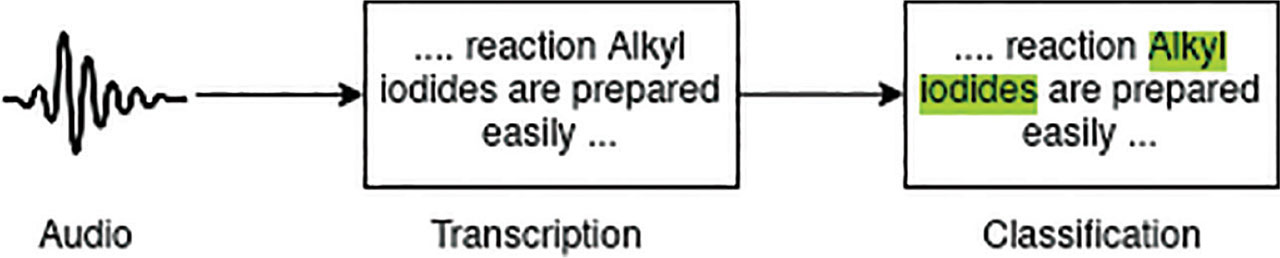
Figure 1:
Overview of the proposed work.
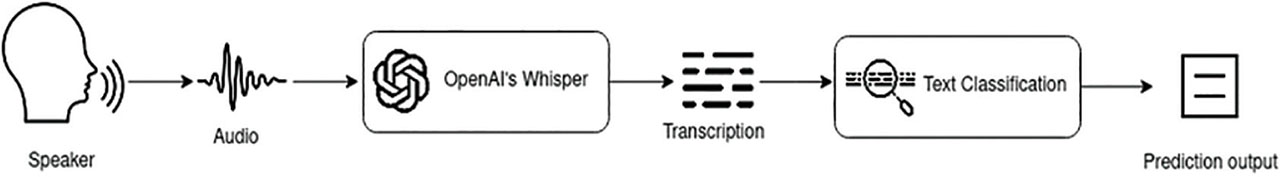
Figure 2:
Initial model.
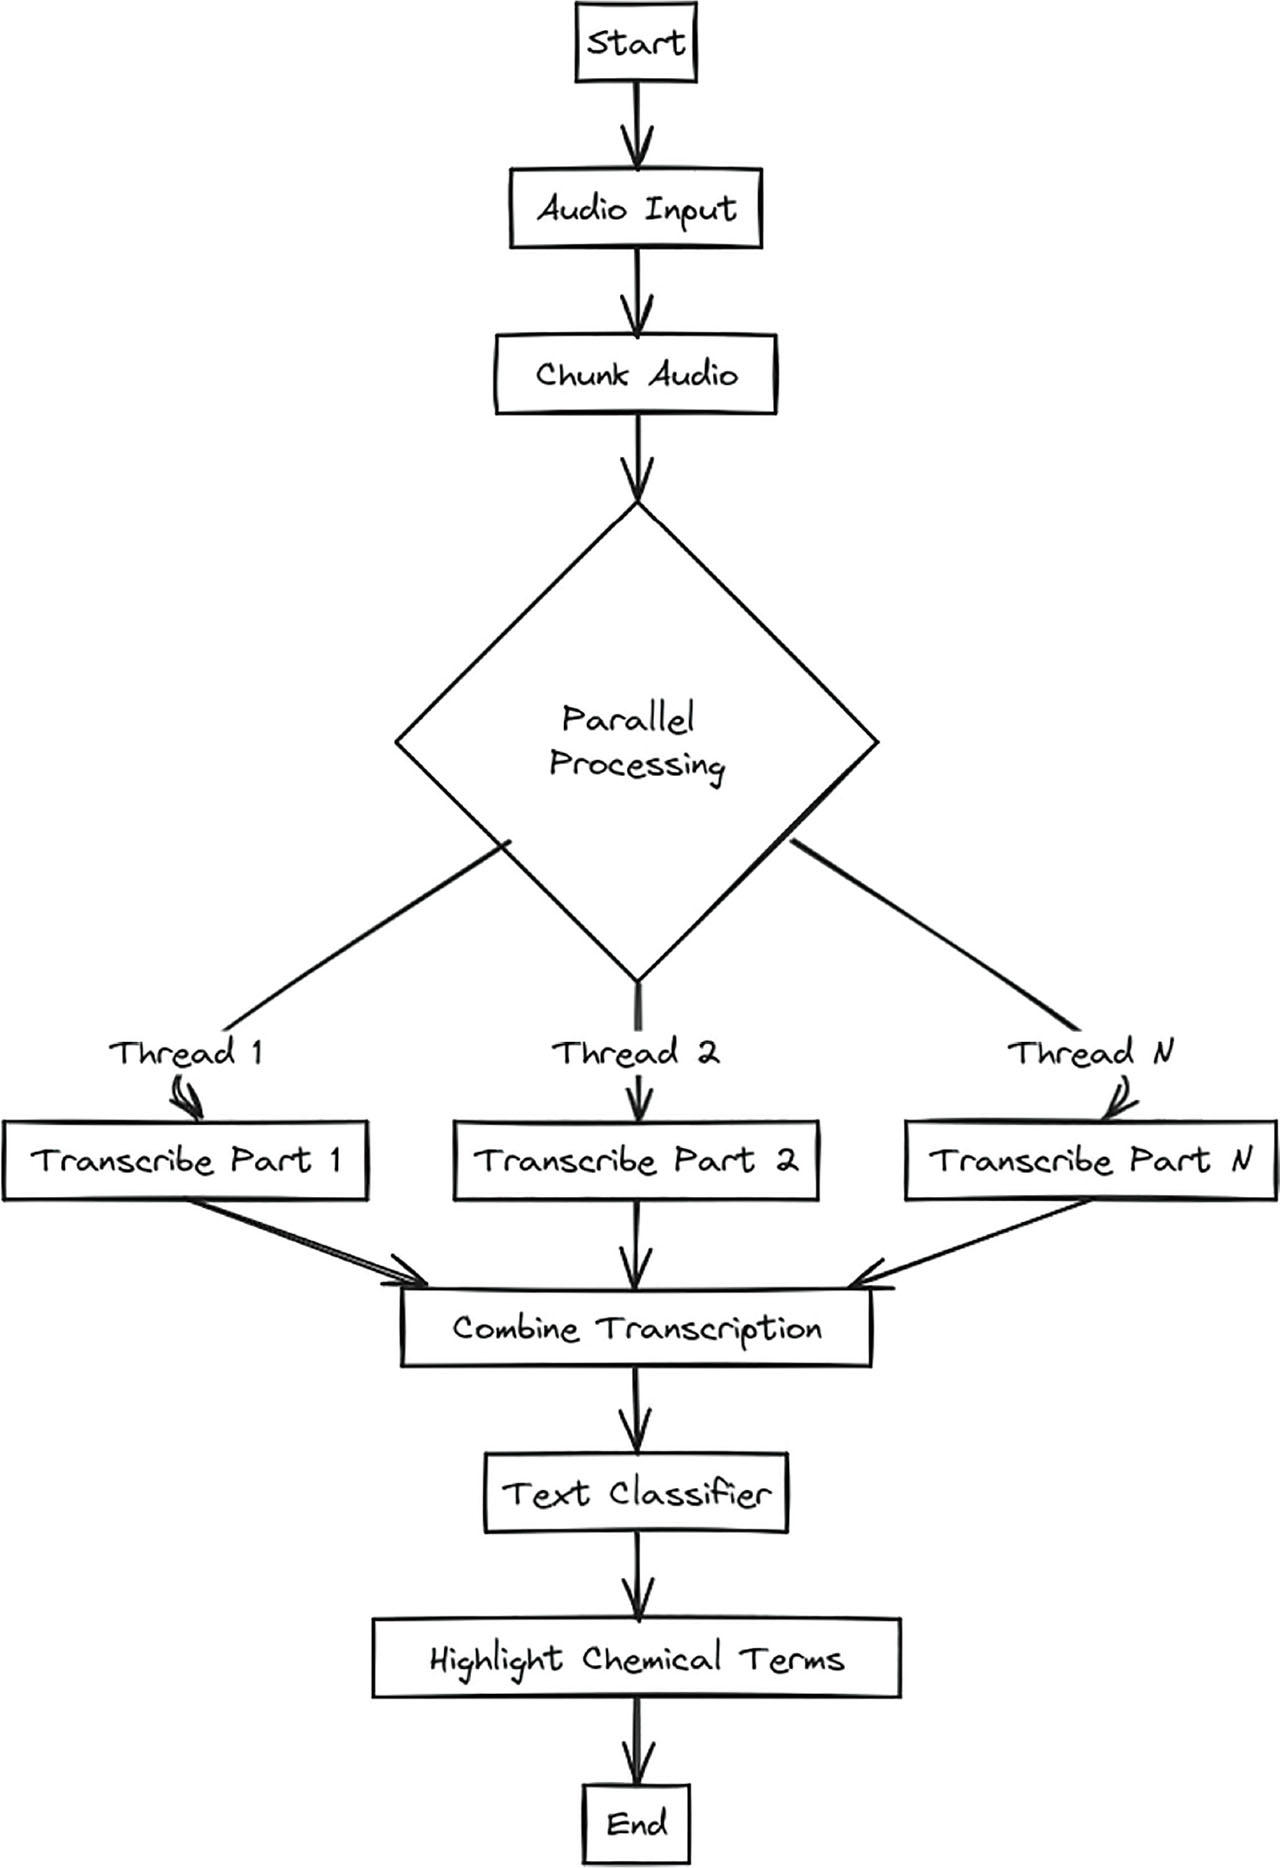
Figure 3:
Flow diagram of improved model.
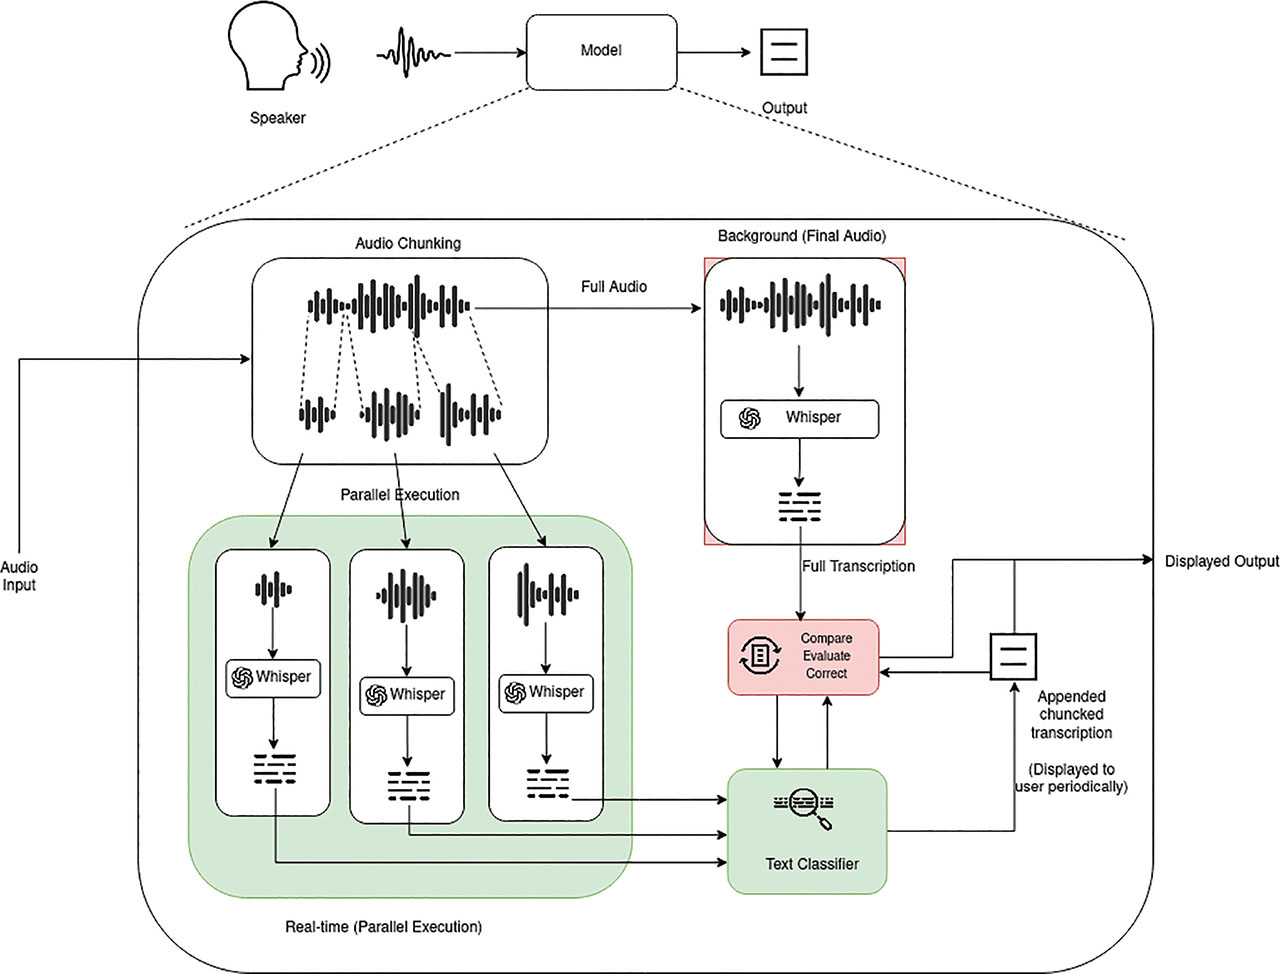
Figure 4:
Improved model.
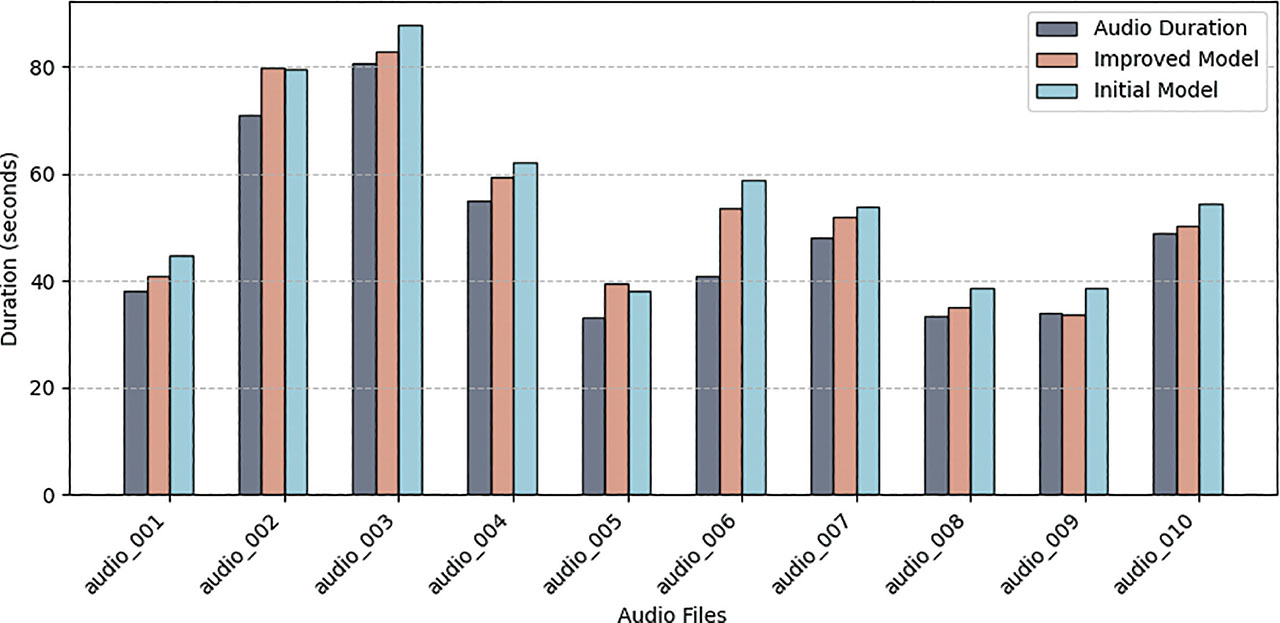
Figure 5:
Comparison performance (in seconds).
Table 1:
Comparative results (in seconds)
| Audio file | Audio duration | Initial model | Improved model |
|---|---|---|---|
| audio 001 | 38.15 | 44.80 | 40.83 |
| audio 002 | 70.97 | 79.53 | 79.83 |
| audio 003 | 80.69 | 87.78 | 82.72 |
| audio 004 | 54.86 | 62.19 | 59.21 |
| audio 005 | 33.25 | 38.09 | 39.40 |
| audio 006 | 40.93 | 58.66 | 53.68 |
| audio 007 | 48.13 | 53.85 | 51.81 |
| audio 008 | 33.49 | 38.68 | 35.13 |
| audio 009 | 33.94 | 38.55 | 33.82 |
| audio 010 | 48.95 | 54.28 | 50.15 |
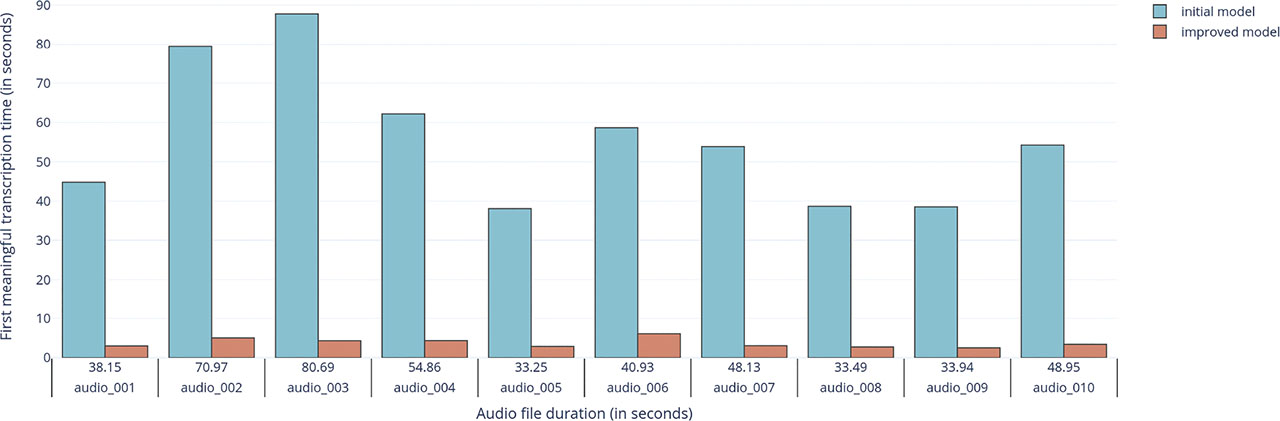
Figure 6:
First meaningful transcription time.
Table 2:
First meaningful transcription time (in seconds)
| Audio | Duration | Initial model | Improved model |
|---|---|---|---|
| audio 001 | 38.15 | 44.80 | 3.00 |
| audio 002 | 70.97 | 79.53 | 5.05 |
| audio 003 | 80.69 | 87.78 | 4.33 |
| audio 004 | 54.86 | 62.19 | 4.35 |
| audio 005 | 33.25 | 38.09 | 2.87 |
| audio 006 | 40.93 | 58.66 | 6.10 |
| audio 007 | 48.13 | 53.85 | 3.05 |
| audio 008 | 33.49 | 38.68 | 2.73 |
| audio 009 | 33.94 | 38.55 | 2.51 |
| audio 010 | 48.95 | 54.28 | 3.40 |
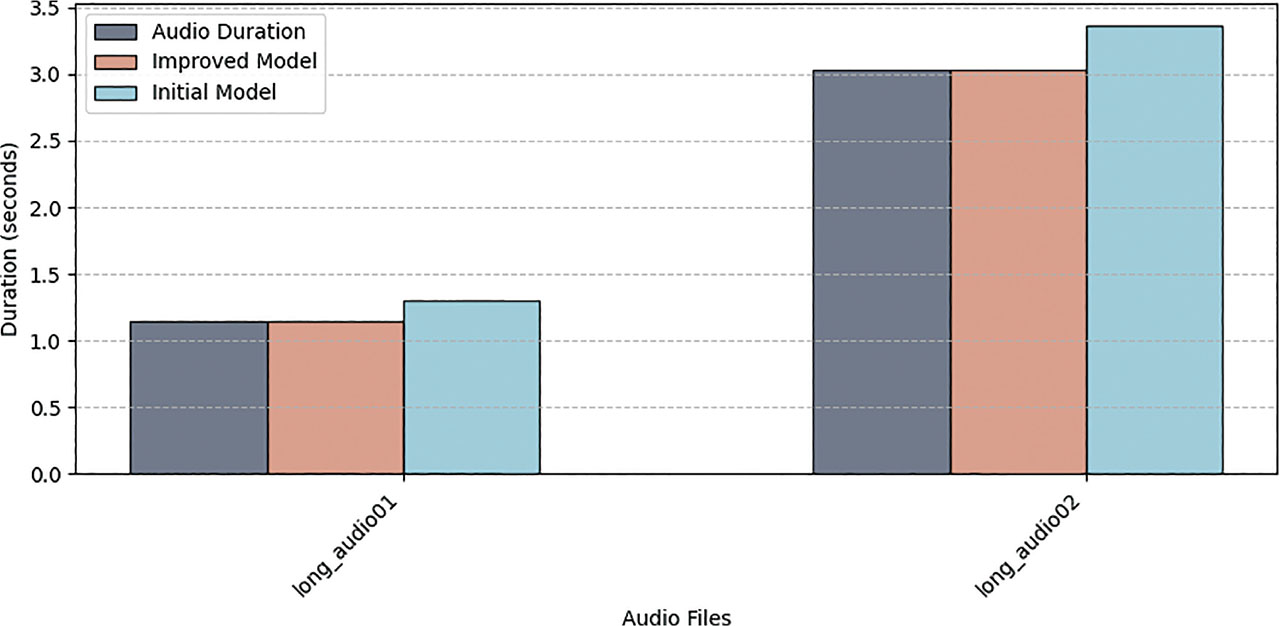
Figure 7:
Stress testing (hours).
Table 3:
Stress testing (hours)
| Audio | Duration | Initial model | Improved model |
|---|---|---|---|
| long audio01 | 1.144 | 1.299 | 1.144 |
| long audio02 | 3.027 | 3.363 | 3.029 |
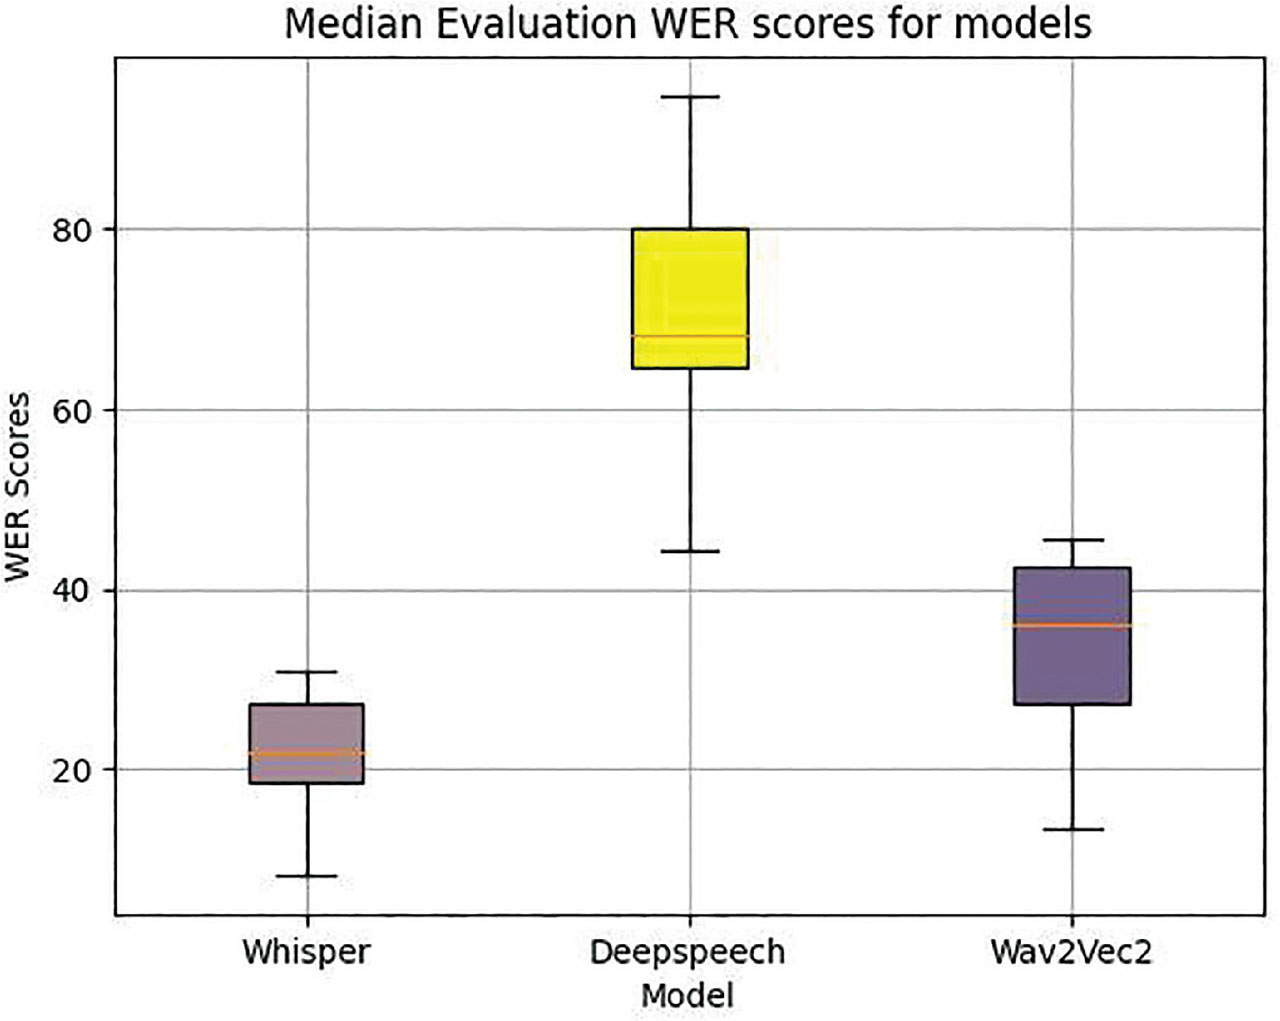
Figure 8:
WER scores without noise. WER, word error rate.
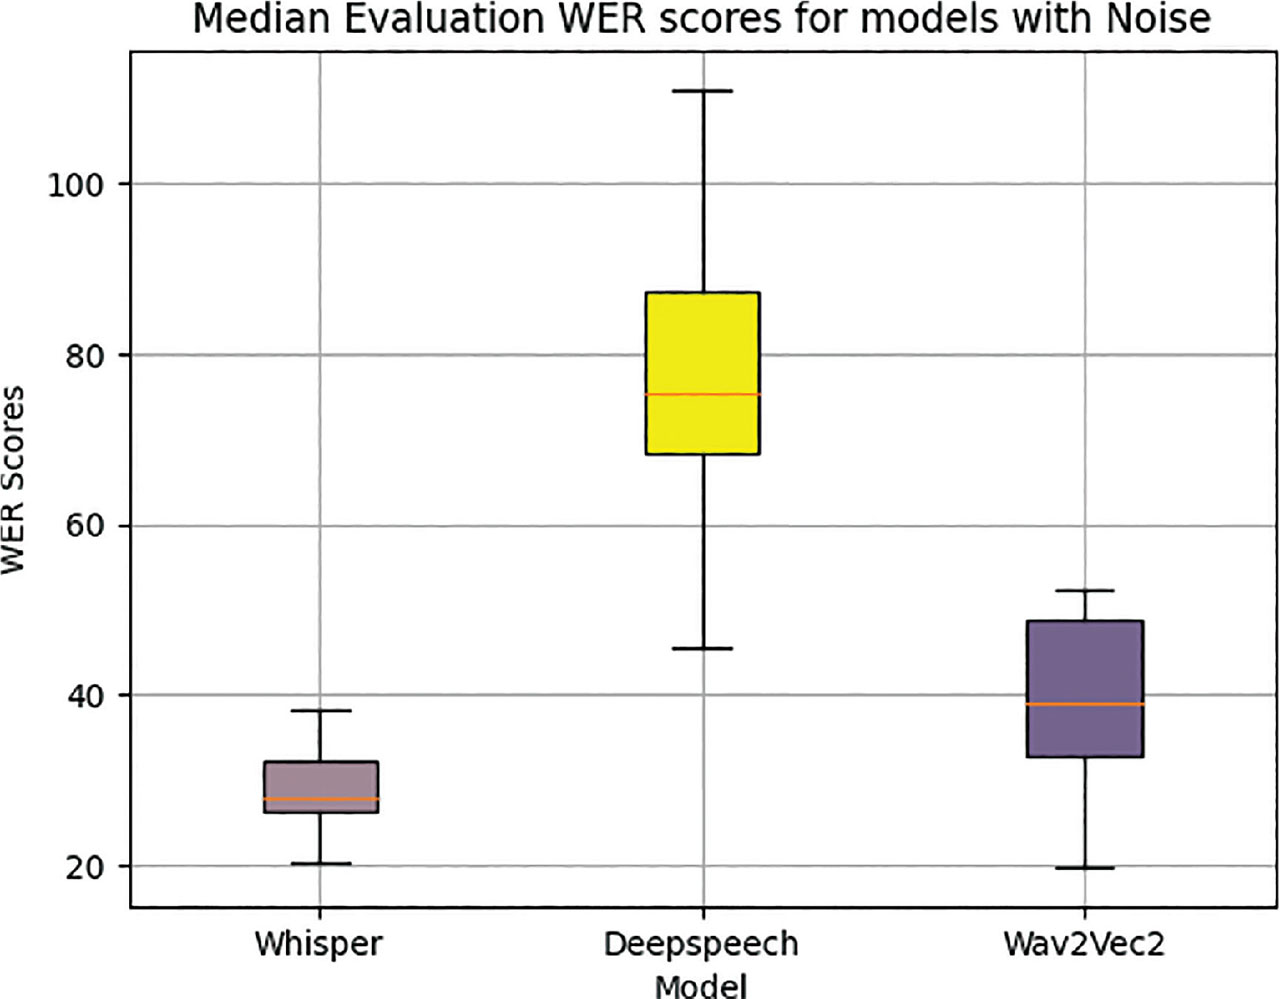
Figure 9:
WER scores with noise. WER, word error rate.
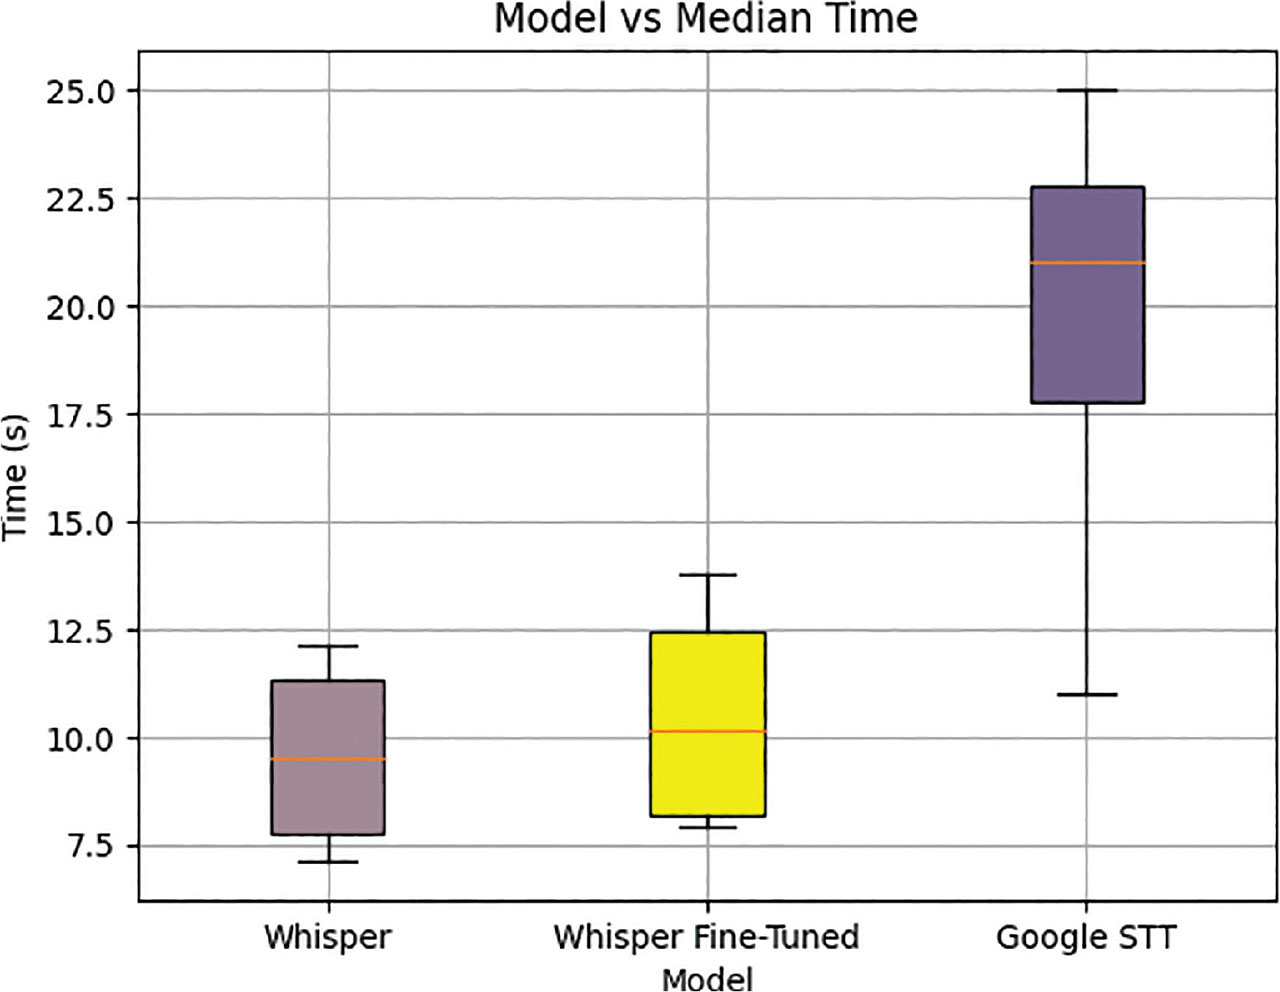
Figure 10:
Time taken for transcription.
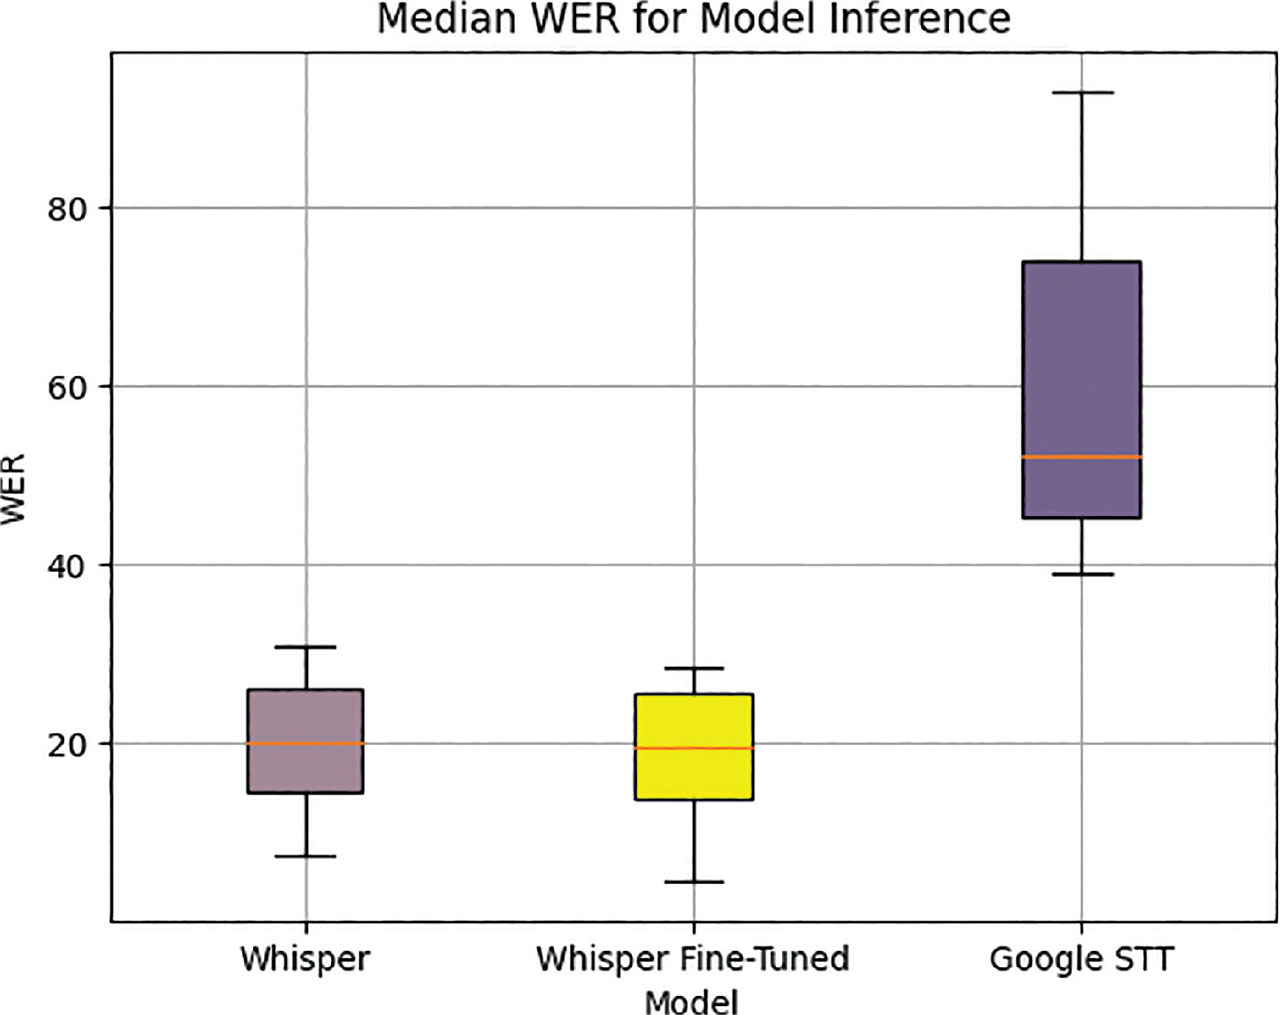
Figure 11:
WER comparison with Google-STT. WER, word error rate; STT, Speech-to-Text.
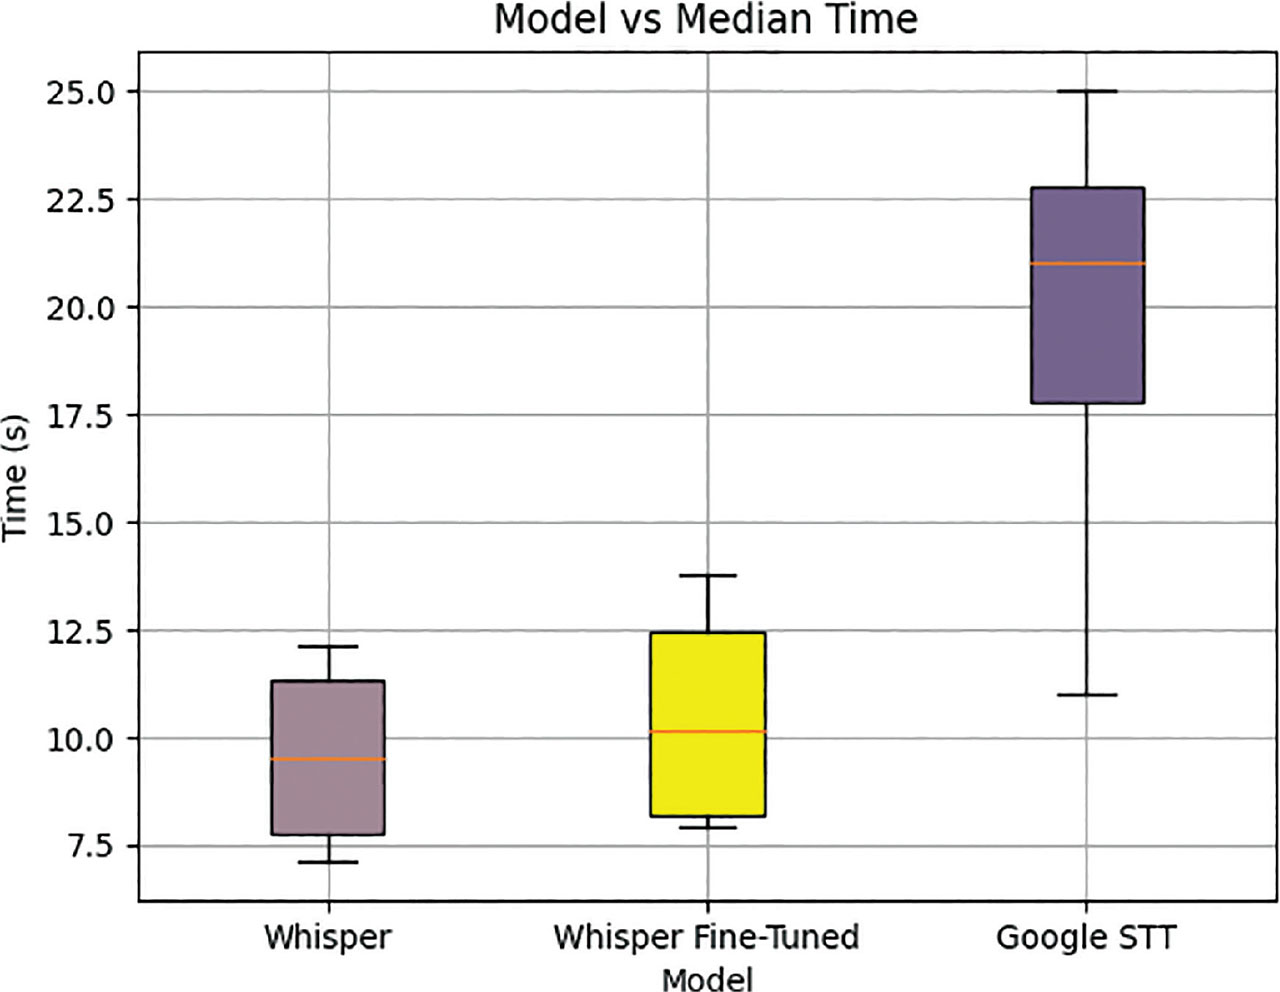
Figure 12:
Time taken for transcription comparison with Google STT. STT, Speech-to-Text.
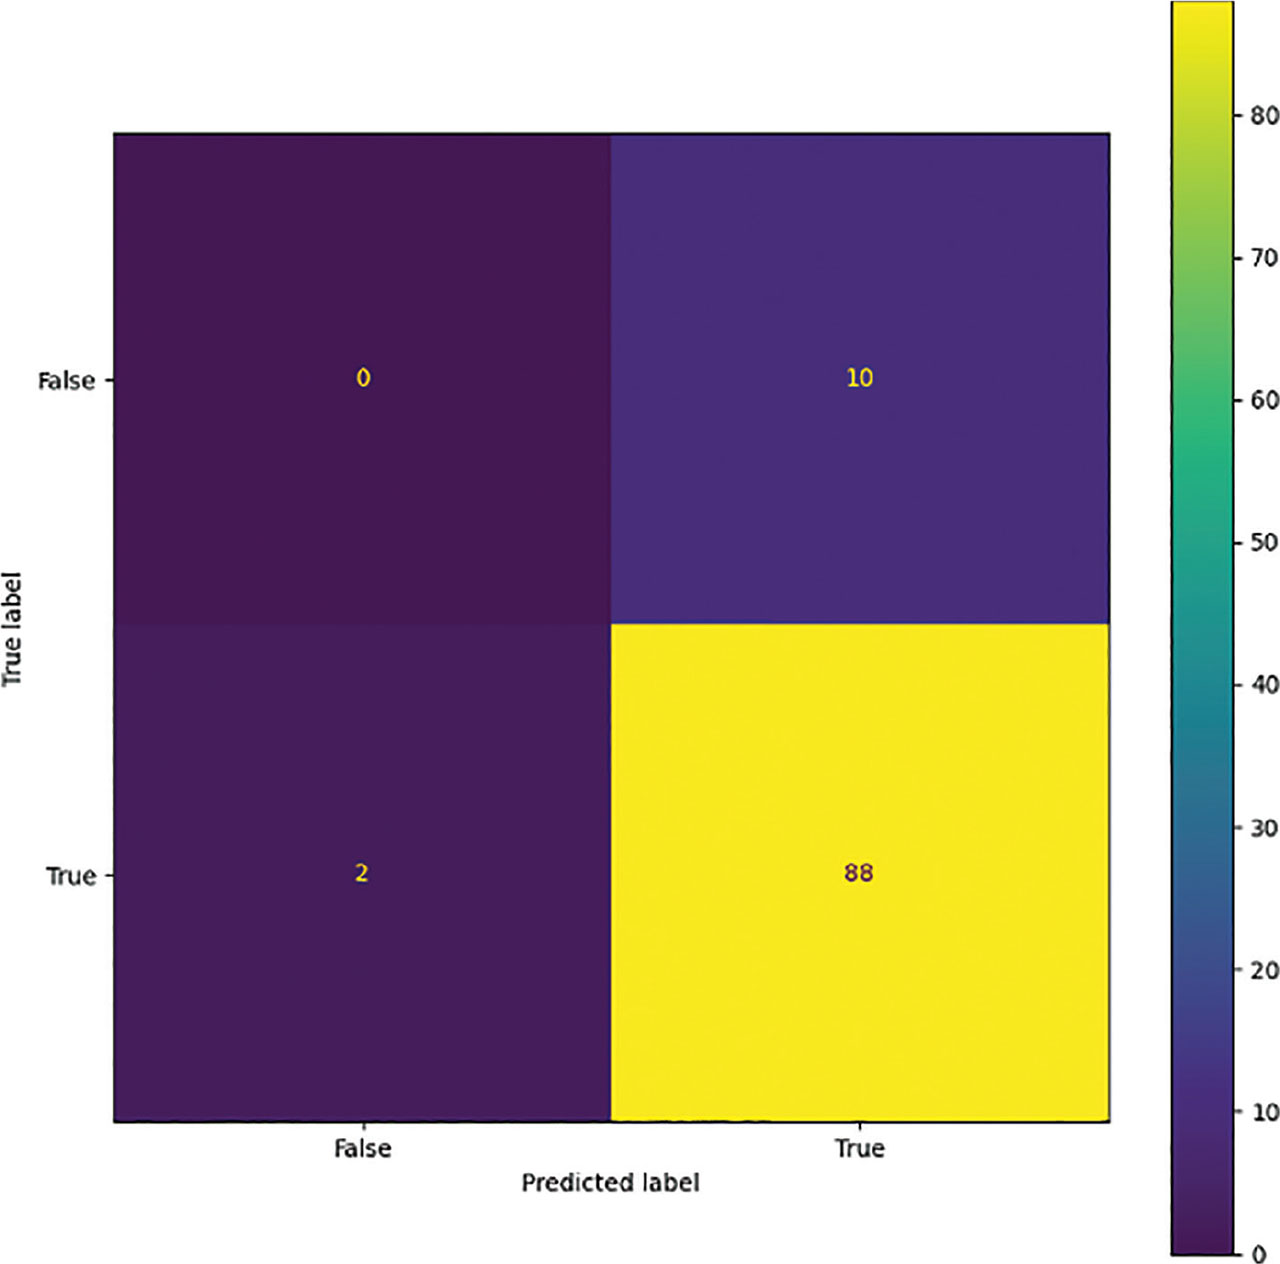
Figure 13:
Confusion matrix for classification of chemical elements from text.
Table 4:
Performance of existing AER systems over Indian accents
| Feature | Whisper (OpenAI) [16] | Wav2Vec2 (Meta) [17] | Google STT [18] |
|---|---|---|---|
| Indian Accent Support | Strong (multilingual model trained on diverse accents) [19,20] | Varies (depends on fine-tuned dataset) [20] | Good (Google has extensive Indian English training data) [21] |
| Regional Variants (Hindi-English, Tamil-English, etc.) | Handles code-switching well [22] | Requires specific fine-tuning for mixed languages [23] | Decent but struggles with heavy accents [18] |
| Noise Robustness | Strong (performs well in real-world noisy environments) [16] | Moderate (depends on fine-tuned model) [17] | Good (handles background noise effectively) [18] |
| Spoken Speed Adaptability | Good (handles fast speech well) [22] | Varies (pre-trained models sometimes struggle) [23] | Good (adjusts well to fast-paced speech) [18] |
Table 5:
Performance of existing AER systems for chemical term recognition
| Feature | Whisper (OpenAI) | Wav2Vec2 (Meta) | Google STT |
|---|---|---|---|
| Chemical Terms Recognition | Limited (depends on general training data, not domain-specific) [16] | Can be fine-tuned for better accuracy [17] | Good (Google’s general corpus covers some scientific terms) [18] |
| Adaptability to Scientific Jargon | Poor without custom fine-tuning [19] | Can be trained on specialized datasets [20] | Better but not perfect [21] |
| Handling of Long & Complex Terms | Struggles with rare chemical names [16] | Can be improved with domain-specific training [17] | Sometimes recognizes common scientific terms but struggles with rare ones [18] |
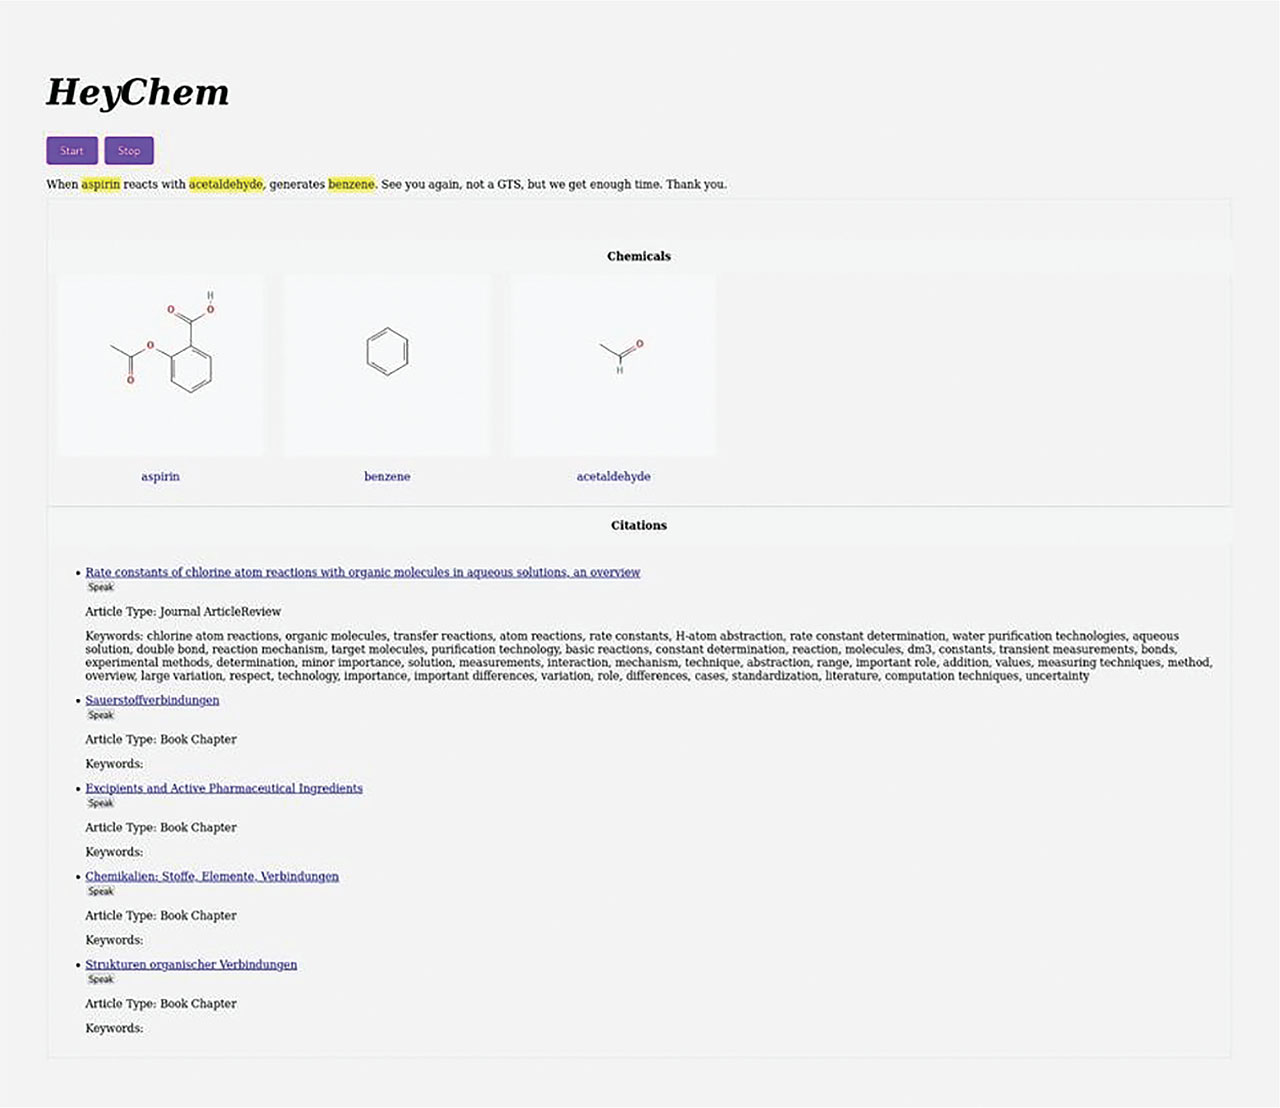
Figure 14:
Web application.
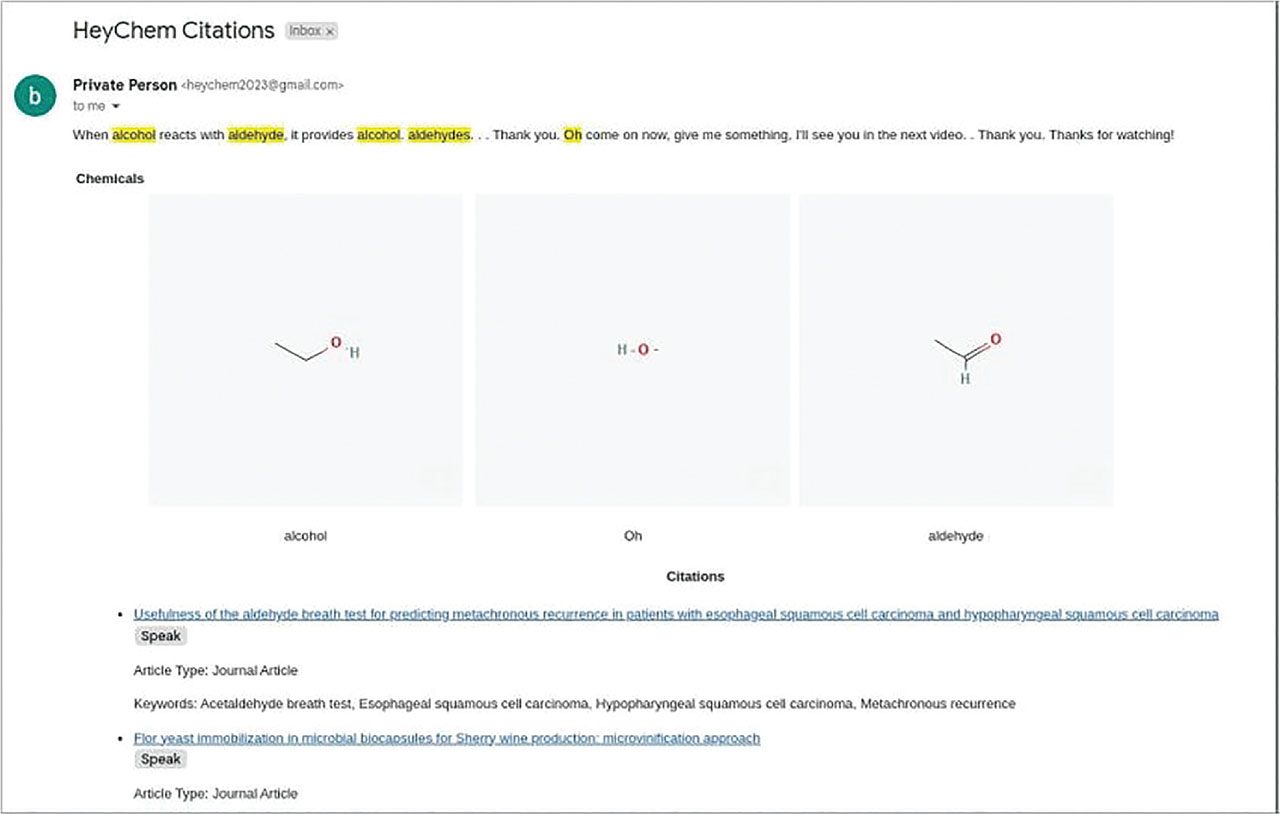
Figure 15:
Email details.